






Terminal-first proof
Prove the request in cURL before the workflow disappears into code
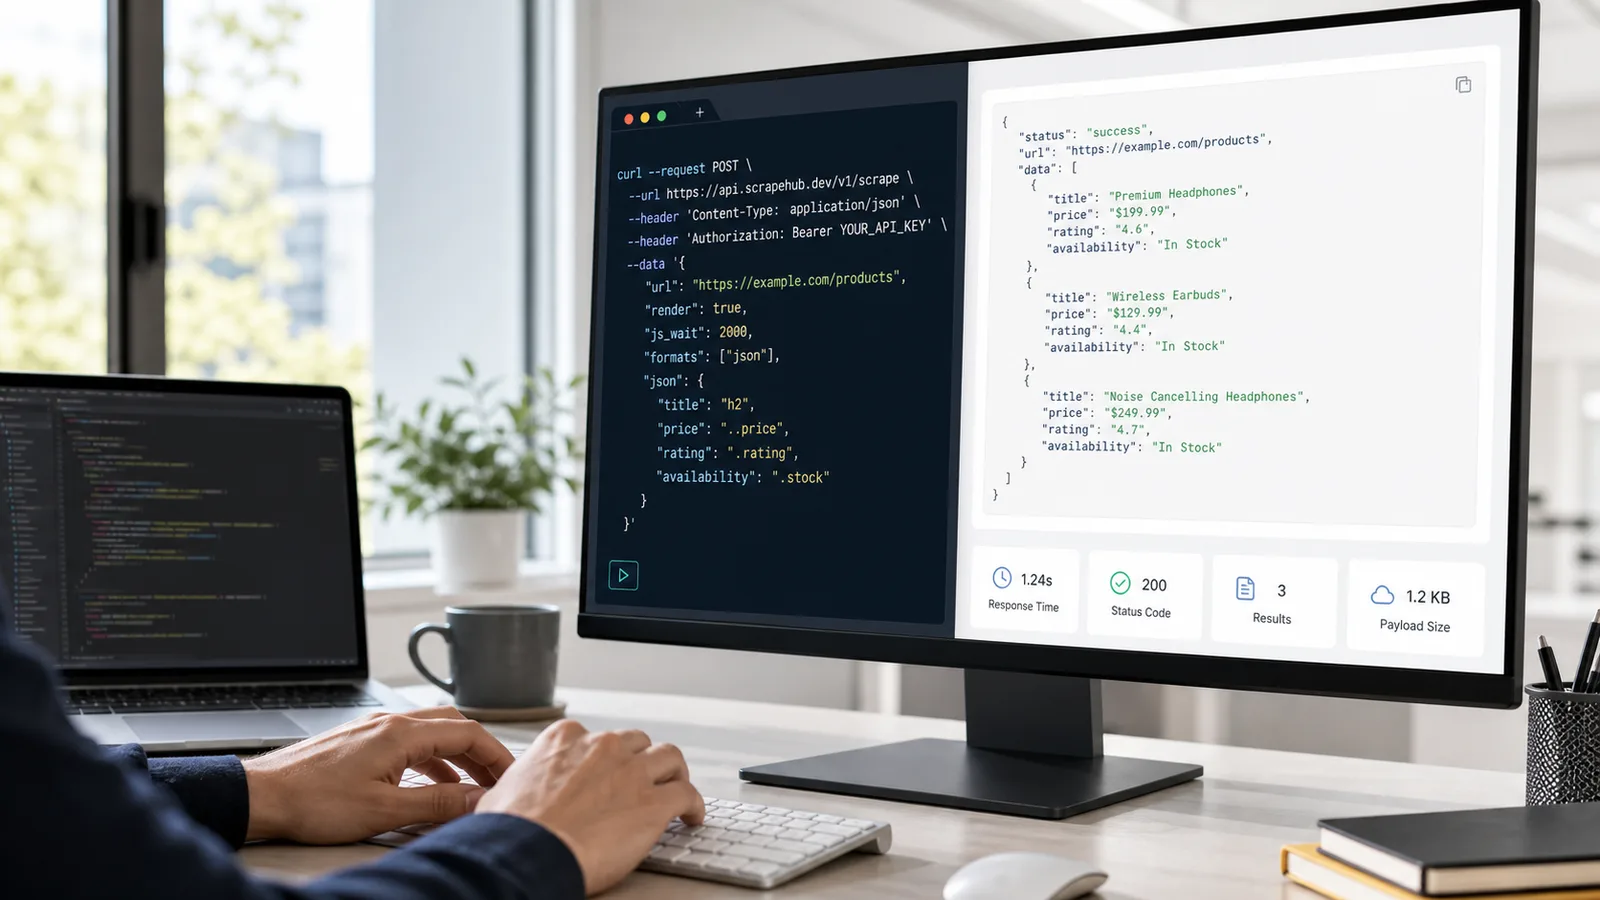
cURL is the fastest way to see whether a scraping request is shaped correctly. The target URL, API key, output format, rendering choice, headers, sessions, and routing controls stay visible in one terminal command before a backend worker or SDK wrapper hides the details.
ScraperFly gives that terminal test a production path. Start with a clean public URL request, inspect the response, then add browser rendering, stronger routing, country targeting, headers, sessions, waits, screenshots, or PDFs only when the target proves they improve the result.
How do you use cURL with a web scraping API?
Use cURL to send a public target URL and response options to a hosted web scraping API from the terminal. A good cURL workflow proves the page response first, then adds rendering, routing, headers, sessions, or visual output only when the captured evidence shows those controls are needed.
That makes cURL useful before any integration code exists. A developer can test one page, compare response formats, see status and content evidence, and hand the exact request shape to a teammate, API Builder, Postman, Python, Node.js, a queue worker, or a production job. The terminal command becomes a small contract: this is the URL, this is the output, these are the controls, and this is why they are enabled.
Practical takeaway: start with cURL when you need a transparent proof request before turning a public page capture workflow into application code.
Why should scraping tests start in the terminal?
Early scraping work fails most often because teams write code around a target they have not fully inspected. A script may hide the URL encoding, authentication, output format, redirect behavior, response size, or rendering decision behind helper functions. When the response is empty, blocked, too large, or missing the expected content, the team has to debug both the target and its own integration at the same time.
A terminal-first test keeps that first decision clean. cURL shows the raw request shape. You can copy it, adjust one parameter, compare the next response, and document the final version without touching application code. If the page is simple, the command stays simple. If the page needs browser rendering, sessions, headers, country routing, or stronger delivery, those controls are added with a reason that can be seen in the response.
This is especially useful when several people touch the workflow. A data engineer can prove the request, a backend developer can move it into code, and a product owner can understand why a heavier profile is required for one target but not another.
| Terminal test | What it proves | Why it matters before code |
|---|---|---|
| Send one public URL | The target can be reached through the API | The team avoids writing integration logic around a bad or unrepresentative URL. |
| Choose an output format | The response shape fits the downstream consumer | Parsers, AI pipelines, QA flows, and archives need different outputs. |
| Compare raw and rendered capture | JavaScript either changes the useful content or it does not | Rendering becomes a precise choice, not a default expense. |
| Add headers or sessions deliberately | Request context changes the returned public page | The workflow keeps stateful controls tied to evidence. |
| Inspect errors in the terminal | The failure is input, auth, format, target, limit, network, or rendering related | Retries and escalation do not become guesswork. |
What should the first cURL scraping request test?
The first request should answer one question: does the simplest public page capture give your workflow usable evidence? Send a real target URL, choose one output format, and inspect the status, final URL, content type, response size, and body. If the body contains the fields you need, the target may not need a browser, premium routing, long waits, or visual files. If the body is a thin shell, missing key content, redirected unexpectedly, or clearly different from the visible page, then you have a reason to test a heavier option.
Do not start by enabling every available control. That makes the first result harder to interpret. If the request succeeds, you do not know which option mattered. If it fails, you do not know which option created the problem. Start with a small profile, change one thing at a time, and keep the final command easy to explain.
For a cleaner starting point, use the API Builder to generate the canonical request, then copy the result into cURL, Postman, or backend code once the response is proven.
Which response format should a cURL workflow try first?
The right response format depends on the next system, not on habit. HTML is best when a parser needs DOM structure, selectors, attributes, links, tables, or embedded metadata. Text and Markdown are better when a content workflow, search index, RAG pipeline, or review tool needs readable page content without layout noise. JSON metadata helps with logging and diagnostics because it exposes operational evidence such as status, final URL, content type, and response details. Screenshots and PDFs are useful when humans need visual proof, QA review, compliance evidence, or archives.
cURL is good for this choice because it makes format testing quick. You can send the same public URL, request HTML, then text, then Markdown, then a visual output if the workflow needs it. The result is a decision about what the application can use immediately, not a pile of converters built before the team knows what the target returns.
| Output to test | Use it when | Terminal decision |
|---|---|---|
| HTML | Your parser needs structure, links, selectors, or embedded markup | Use it as the first test for source-first capture. |
| Rendered HTML | The useful DOM appears only after browser execution | Compare against raw HTML before making rendering the default. |
| Text or Markdown | The workflow needs readable content for search, summaries, or AI ingestion | Choose the cleanest readable format your downstream tool can use. |
| JSON metadata | You need operational context for logging, debugging, or request classification | Use it to make response evidence visible in later automation. |
| Screenshot or PDF | The result must be reviewed, archived, or proven visually | Reserve visual output for workflows that need human-readable evidence. |
When should a cURL request add rendering, headers, sessions, or routing?
Add controls when the response gives you a specific reason. Enable JavaScript rendering when source HTML is missing content that appears after browser execution. Add headers when a public target expects legitimate request context such as language, content type, or referer behavior. Use sessions when related requests depend on shared cookies or state. Add country routing when public content changes by location, language, currency, availability, or regional redirect behavior. Consider stronger routing when repeated evidence shows the simple path does not retrieve a usable response.
The point is not to keep every request minimal forever. The point is to keep each upgrade connected to the target. cURL helps because every option remains visible. If someone asks why a request uses rendering or premium routing, the answer should be in the sample history: raw HTML missed the content, the regional page changed, the session carried necessary state, or the target repeatedly failed through the lighter path.
For pages that depend heavily on browser execution, compare the JavaScript rendering API path. For stateful request flows, use the sessions API page. For request context, review custom headers.
How should developers move from cURL to production code?
Move only the proven request shape into code. The application should not inherit every experimental option that was tried in the terminal. Keep the final request profile small, name why each control exists, and log the response evidence that matters for the workflow. That makes future failures easier to diagnose because the team can compare production behavior to the original terminal proof.
Python and Node.js integrations should own scheduling, queues, parsing, storage, alerting, retry policy, and business logic. ScraperFly should own the public page capture layer: request delivery, rendering when needed, output formats, routing controls, and response evidence. cURL sits between those worlds. It proves the API request before the integration turns it into reusable code.
When the request is stable, hand it to the right implementation path: Python for scripts, notebooks, data jobs, and analysis workflows; Node.js for backend services, queues, agents, and web applications.
What mistakes make cURL scraping tests misleading?
The biggest mistake is testing an easy URL and assuming the whole target set behaves the same way. A production workflow should sample the actual page types: static pages, JavaScript-heavy pages, regional pages, pages with redirects, pages that may require state, and pages where visual proof matters. Another mistake is using cURL as a full crawler plan. cURL proves a request. It does not replace scheduling, discovery logic, parser design, storage, monitoring, or retry discipline.
It is also easy to leave test-only controls in the final profile. Long waits, rendering, stronger routing, screenshots, and PDFs can be helpful, but they should not stay enabled just because they were tried once. Keep the command readable. Keep the output tied to the downstream consumer. Keep request cost aligned with what the target actually needs.
Practical takeaway: a good cURL test is not the most powerful request you can build; it is the clearest request that proves what production should send.
Where should a team start?
Start with one real public URL in the API Builder, generate the cURL command, and run it from the terminal. Inspect the response before writing wrappers or workers. If the content is present, keep the request light. If it is missing, add one control at a time and compare the result. Once the command is proven, move the same request shape into the implementation that owns the rest of the workflow.
For output decisions, use the response formats guide. For cost planning, review pricing after you know which request profiles your real targets require.












