






ScraperFlyAI-ready Web Data API

developer api

Scrape a website to JSON your app can inspect

JSON output is useful when your backend needs page context in a predictable response shape. ScraperFly can return supported public page metadata, links, headings, clean text, Markdown, and request evidence as JSON while keeping target-specific extraction logic under your control.

JSON response workflow

Return page context as JSON without pretending every target has the same schema

A website-to-JSON workflow is useful when your application needs a predictable response envelope around public page data. ScraperFly helps developers capture the page, preserve request evidence, and return supported context such as metadata, links, headings, text, Markdown, status, final URL, and response details.

The important boundary is honesty. ScraperFly can prepare the public page response and make it easier to inspect programmatically, but your product should still own target-specific extraction for custom fields such as prices, availability, ratings, author names, or internal business entities.
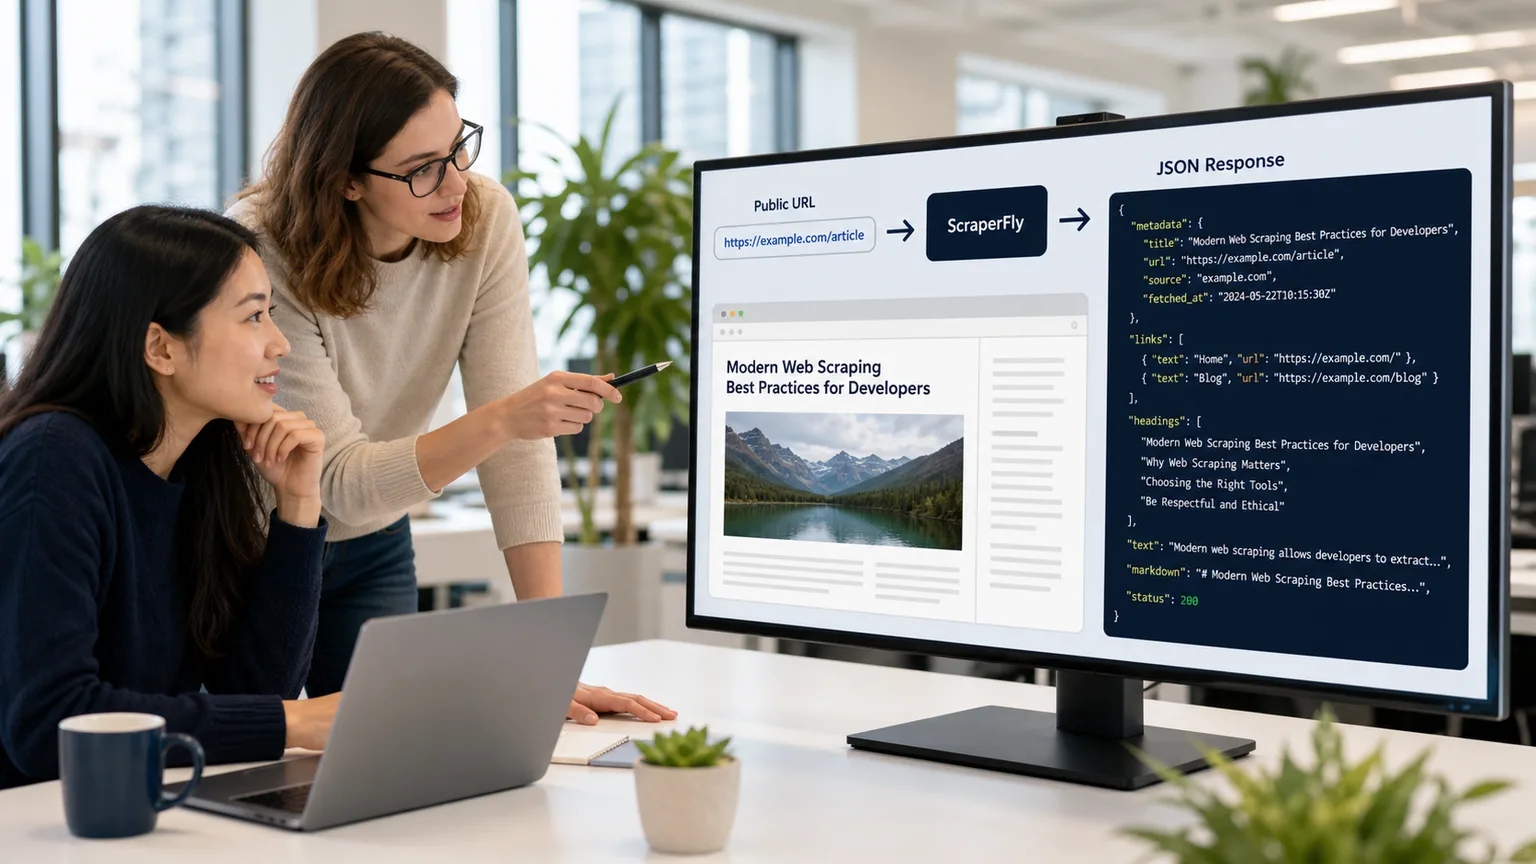
metadatalinks + headingsparser-ready context
Developers reviewing a public website converted into JSON metadata, links, headings, text, Markdown, and request evidence

What does it mean to scrape a website to JSON?

Scraping a website to JSON means fetching a public URL and returning useful page context in a structured response your application can read. Instead of handing every downstream system a raw blob of HTML, the API response can carry metadata, links, headings, readable text, Markdown, request status, final URL, content type, and other response evidence in fields that are easier to log, inspect, compare, and route.

That does not make every website a clean database table. Public pages do not share one schema. A product page, article, directory listing, search result page, and documentation page all expose different structures. ScraperFly gives your team a stable capture layer and supported response shapes; your parser still decides which target-specific fields matter for your use case.

Practical takeaway: use website-to-JSON output for page context and request evidence, then add custom extraction logic where the business schema is specific to the target.

When is JSON the right response shape?

JSON is the right shape when the consumer is a backend service, queue worker, monitoring job, agent, data pipeline, or internal tool that expects predictable keys. It helps when your workflow needs to store the final URL, status, page metadata, discovered links, headings, text, Markdown, and diagnostics beside the captured content. That makes debugging and downstream routing simpler because the application does not have to infer every detail from a single HTML string.

HTML is still the better primary input when selectors, attributes, table structure, DOM relationships, or embedded state matter. Text and Markdown are often better when the goal is search, summarization, classification, review, or AI ingestion. JSON is strongest when it wraps those useful outputs with traceable context.

Response shape Use it when What to avoid
JSON context Your backend needs metadata, links, headings, text, Markdown, and request evidence in predictable fields Do not treat page-level JSON as automatic custom extraction.
Raw HTML Your parser needs selectors, attributes, tables, links, or embedded source structure Do not convert to text too early if DOM relationships matter.
Rendered HTML The useful public content appears only after JavaScript execution Do not render every page before proving the source response is incomplete.
Text You need compact readable content for search, indexing, or simple comparison Do not use plain text when structured page relationships are required.
Markdown You want readable headings, lists, and links for AI or review workflows Do not expect Markdown to preserve every selector or layout detail.
Screenshot or PDF You need visual proof, QA review, archive output, or a human-readable record Do not use visual files as the main parser input when machine-readable data is enough.

What JSON fields are useful in production workflows?

Useful JSON begins with traceability. Your application should know which URL was requested, where the request finally landed, what status came back, what content type was returned, and how large the response was. That evidence helps separate a real target change from a redirect, thin response, block page, timeout, or unsupported format.

Page context comes next. Metadata, titles, descriptions, headings, canonical hints, links, clean text, and Markdown can help a pipeline decide what to parse, index, summarize, archive, or send to another service. For AI and RAG workflows, JSON metadata plus Markdown can be stronger than plain text because the response carries readable content and operational context together.

Target-specific fields come after that. If your product needs price, SKU, author, rating, job title, location, event date, or availability, build that extraction layer around the target pages you actually support. ScraperFly helps fetch and prepare the response; your app defines the business schema.

How should teams test website-to-JSON output?

Begin with one public target URL in the API Builder. Capture the source response first, inspect the returned context, and confirm which fields are actually present. Then compare alternate formats: HTML for parser work, text or Markdown for readable content, JSON metadata for diagnostics, and visual output when a reviewer needs proof.

If the page is JavaScript-heavy, compare source output with the JavaScript rendering API or rendered HTML API workflow. Rendering is worthwhile when it adds content your product needs. If rendering does not improve the response, inspect timing, redirects, request context, or target behavior before retrying.

Test step Question to answer Decision it supports
Fetch the public URL Does the response succeed and land on the expected final URL? Confirm the target is reachable before parser work starts.
Inspect source HTML Does the initial response contain the fields or content you need? Keep the request lightweight when source capture is enough.
Compare output formats Is HTML, text, Markdown, or JSON context the best downstream shape? Avoid building converters around the wrong format.
Render only if needed Does browser execution add meaningful public content? Use rendering for real content gaps, not as a default tax.
Define custom extraction Which target-specific business fields does your app need? Keep ScraperFly as the capture layer and your parser as the schema layer.

How does website-to-JSON differ from a parser API?

A parser API usually implies that the service understands the target-specific schema and returns custom entities. A website-to-JSON response is different. It gives your application structured page context and capture evidence so your own parser can make better decisions. That distinction keeps the workflow reliable because public websites vary too much to pretend that every target can be reduced to the same JSON object.

If your team needs clean readable content, compare the parse website content API, HTML to text parser API, and HTML to Markdown parser API pages. If you need DOM-level parsing, start from the HTML scraping API or HTML parser API for web scraping workflows.

How does ScraperFly keep JSON workflows practical?

ScraperFly keeps the workflow practical by letting the same API path start simple and add controls when the target proves they are needed. A public page that returns useful source HTML can stay light. A client-rendered page can use browser execution. A route with public context needs can add headers, cookies, country targeting, or sessions. A review workflow can add screenshots or PDFs. Each choice should improve the response, not merely make the request heavier.

This matters for cost and maintainability. Teams often overbuild website-to-JSON pipelines by running every target through a browser, converting everything to the same format, and then discovering that the downstream parser still needs target-specific rules. ScraperFly gives you the capture controls, response formats, and evidence to choose a smaller path first. The pricing page and web scraping API credit cost calculator can help estimate the impact before volume grows.

Practical takeaway: the best website-to-JSON workflow gives developers a clear response envelope, keeps request weight aligned with the target, and leaves custom business extraction where it belongs: in application logic.


Website to JSON

Return page-level JSON context your application can inspect immediately

ScraperFly helps teams fetch public pages and return supported response context as predictable JSON: metadata, links, headings, readable text, Markdown, request status, final URL, and diagnostics. Use the API Builder to compare formats before you build a converter or parser around the wrong shape.

01
01

Wrap metadata, links, headings, and content in one response

Keep the useful page evidence together so backend jobs, agents, and pipelines can inspect it without guessing from raw markup.

02
02

Combine JSON metadata with text or Markdown

Use text for compact analysis or Markdown when headings and links help AI, RAG, review, or documentation workflows.

03
03

Render or route only when the target proves it needs help

Start with source HTML, then add rendering, waits, sessions, headers, or stronger routing only when those controls change the response.

JSON response controls

url

The public page ScraperFly should fetch.

format

Choose HTML, text, Markdown, JSON metadata, screenshot, or PDF.

render

Run a browser when source HTML does not contain the useful public content.

wait

Allow browser-built content to settle when rendering is enabled.

keep_headers

Forward allowed request context such as language or content preferences.

download

Return visual files when screenshots or PDFs are needed for review.

cURL example

Generate Markdown with the same request shape you can move into production

curl "https://scraperfly.com/api/v1?url=https%3A%2F%2Fexample.com&format=markdown" \
  -H "apikey: YOUR_API_KEY"

JSON target evidence

Map what the website actually exposes before designing the JSON shape

A useful JSON workflow starts by inspecting the public response: source HTML, rendered state, metadata, links, headings, content type, final URL, and response size. ScraperFly gives teams that evidence so they can choose the right response format and add custom extraction only where the target-specific schema requires it.

Raw HTML response mapped to visible page data
01

Raw HTML availability

Check whether the fields you need are already present in the first HTML response.

Best first test for simple pages, articles, docs, listings, and product details.

Before and after JavaScript rendering comparison
02

JavaScript dependency

Compare raw HTML with the rendered DOM or screenshot before turning on browser rendering.

Use rendering when raw HTML is only a shell and scripts create the useful content.

Cookies, consent, session and access context for scraping
03

State & access context

Identify whether cookies, consent, login boundaries, pagination, or the same visitor state affect the response.

Use sessions and headers when continuity changes the data you receive.

Regional content variations across countries and routes
04

Geo/content variation

Test whether country, language, currency, inventory, SERP, ads, or route reputation changes the result.

Use geo or premium routing only when the target proves the response varies by route.

Questions that keep website-to-JSON work grounded

Where is the target field?

Find whether the field exists in raw HTML, rendered DOM, an API call, structured data, a file, or a later interaction state.

What changes the response?

Sample a few URLs and compare status, final URL, content length, redirects, empty states, and visible result differences.

What context is required?

Mark any dependency on consent, locale, cookies, headers, authentication boundary, pagination, filters, or previous requests.

What does failure look like?

Define the signals for blocked, partial, stale, redirected, empty, timed-out, or region-mismatched responses before scaling.

Check the response before writing parser rules

Fetch mode

Raw HTML availability decides whether the first request can stay simple or needs rendering, waits, screenshots, or extraction.

Request context

State requirements decide whether to add headers, cookies, sessions, consent handling, or a stable visitor profile.

Routing choice

Geo and reputation findings decide whether standard routing is enough or a country/premium route is justified.

Validation rules

Known failure states become checks for retries, escalation, QA review, and deciding when a lighter profile is still complete.

Practical structure

Why ScraperFly is a better starting point than raw HTML plus homegrown converters

Raw HTTP requests leave teams to solve response formats, rendering, routing, retries, visual evidence, and diagnostics around every target. ScraperFly gives one API layer for capturing public pages, choosing the output shape, and keeping request evidence close to the content your application will inspect.

Happy team validating a project on a laptop
01 / Start easy

Easy, free start before any billing pressure

ScraperFly gives you room to test the real target first. Use free credits to check whether the page works, whether the data is present, and which controls are actually needed before you commit money to a plan. That makes the first experiment feel light: no procurement loop, no forced subscription, no guessing your monthly volume on day one.

Free creditsNo card for first testsValidate before scaling
Smiling professional working successfully with a laptop
02 / Spend smart

Affordable, flexible billing for real-world scraping volume

Not every scraping workload is a neat monthly curve. Some projects spike, some pause, and some only become recurring after the data proves value. ScraperFly supports that reality with a pay-as-you-go path plus monthly credit plans when steady volume makes sense. You can buy what you need, keep costs visible, and avoid turning a small test into an oversized subscription.

Pay as you goMonthly when usefulCost control
Developer preparing structured output from a laptop
03 / Ship faster

Response preprocessing that removes cleanup work

A cheap fetch is not enough if your team still has to build converters, cleaners, screenshots, PDF capture, and LLM-ready formatting around it. ScraperFly can return the response as HTML, clean text, Markdown, structured JSON, PDF, or image output, so your pipeline gets closer to the final asset in one request. Less glue code, fewer moving parts, faster delivery.

HTMLTextMarkdownJSONPDFImage

Where ScraperFly helps website-to-JSON workflows stay realistic

The advantage is not pretending every page has the same schema. The advantage is getting a dependable capture layer, useful response context, and a simple upgrade path when a target needs rendering or stronger request controls.

Decision pointScraperFly advantageTypical competitor tradeoff
First experimentStart with free credits and validate the real target before spending. You can prove whether raw HTML, rendering, premium routing, or country targeting is actually needed.Trials often push you quickly toward a recurring plan or hide the true cost until add-ons enter the request.
Billing modelUse pay-as-you-go credits for uneven work, then move to monthly credits only when the workload becomes predictable. This keeps small tests and project-based scraping affordable.Many tools are optimized around monthly subscriptions, fixed allowances, or tier gates that can feel heavy before volume is proven.
Request weightKeep simple pages simple. Turn on JavaScript rendering, premium routing, sessions, headers, waits, or country routing only when the response evidence says they matter.Comparable controls may exist, but they are often bundled into higher tiers, defaults, or more complex pricing profiles.
Output formatsReturn the response in the shape your product needs: HTML for parsers, text or Markdown for content pipelines, JSON for structured metadata, and PDF/image output for visual proof.Some providers focus mainly on access and leave formatting, capture, cleanup, and downstream preparation to your own code.
Developer workflowOne API surface can cover target testing, escalation, rendering, routing, sessions, headers, response formatting, and status checks. The path from prototype to production stays compact.Proxy-first tools, actor marketplaces, and crawler platforms can be powerful, but often require more glue code or a heavier operating model.
Best fitTeams that want practical web data delivery: start small, measure cost per useful result, and scale only the controls that improve the outcome.Teams with fixed high-volume contracts, custom proxy infrastructure, or broad marketplace crawler needs may prefer a more specialized platform.

JSON cost control

Keep website-to-JSON workflows affordable by choosing the smallest useful capture path

A JSON response does not require every request to use browser rendering, visual files, sessions, or premium routing. ScraperFly lets teams start with lightweight source capture, then add heavier controls only when the target response proves they improve the data your application receives.

A lightweight HTML request returning a simple response
01

Basic fetch

Use a basic fetch when public HTML already contains the fields you need.

Lightest request profile; keep it when the response is complete.

JavaScript rendering producing a complete DOM
02

Rendering

Use rendering when raw HTML is a shell and JavaScript completes the page.

Heavier profile; use it only when browser output changes the result.

Several requests preserving cookies and visitor state
03

Stateful session

Use sessions when cookies, consent, locale, or pagination change the response.

Heavier state profile; preserve it only when continuity matters.

Request routing through geo and higher quality routes
04

Premium routing & geo

Use premium routing or geo only when origin, country, reputation, or regional content changes the result.

Heaviest routing profile; apply it only to targets that prove they need it.

What changes request weight

More infrastructure work

Browser rendering, routing choices, and longer waits mean the platform has to do more than return a simple response.

More target uncertainty

Redirects, empty states, rate limits, and challenge pages often require stronger delivery options or retries.

More state to preserve

Cookies, sessions, consent, and multi-page flows add moving parts that a plain stateless fetch does not have.

More evidence to return

Screenshots, PDFs, rendered output, and richer response artifacts are useful, but they are heavier than plain HTML.

How to keep JSON pipelines predictable

Sample before scale

Test a small URL set first and group targets by the lightest profile that returns complete data.

Do not render by default

Inspect raw HTML before turning on rendering. Many public pages already contain the data you need.

Escalate by evidence

Move up only when the response shows missing content, state dependency, geo variance, or routing problems.

Measure useful results

Optimize around valid records delivered, not raw request volume. A lighter profile is best only when it stays complete.

JSON questions

Common questions about scraping websites to JSON

Quick answers for teams evaluating web scraping API behavior: request formats, JavaScript rendering, proxy routing, credits, files, security, and billing.

Quick answers

What JSON output means

Use JSON as a response envelope, not a magic universal schema.

Does JSON output replace my parser?

No. JSON context helps your app inspect the page response, while target-specific fields still need parser logic.

What can be included in JSON context?

Useful context can include metadata, links, headings, text, Markdown, status, final URL, content type, and response evidence.

Choosing the response shape

Pick the format around the downstream system.

When is HTML better than JSON?

Use HTML when selectors, attributes, tables, links, and DOM relationships matter to your parser.

When is Markdown useful?

Use Markdown when readable headings, sections, and links help AI, RAG, search, or review workflows.

JavaScript and visual output

Add heavier controls only when the page needs them.

Can rendered content feed JSON workflows?

Yes. Enable rendering when JavaScript changes the useful public content, then return the supported response shape your app needs.

Should screenshots be part of JSON scraping?

Use screenshots or PDFs when a human needs visual proof. Keep machine-only workflows on lighter response formats when possible.

Production checks

Prove the target response before scaling volume.

How should I test the first target?

Use the API Builder to compare source HTML, rendered output, text, Markdown, and JSON metadata on a real public URL.

How do I keep request cost predictable?

Classify targets by the smallest useful capture profile and reserve rendering, sessions, visual output, and stronger routing for pages that prove they need them.








