






Parser-ready markup
Capture reliable HTML before extraction rules depend on it
An HTML parser is only as dependable as the page source it receives. If the request returns a thin shell, a redirect, a blocked fallback, or markup that appears only after JavaScript runs, selectors and extraction rules can fail even when the parser itself is correct.
ScraperFly gives teams a cleaner starting point: fetch public pages as raw HTML when the markup is already present, switch to rendered HTML when the useful DOM is browser-built, and preserve response evidence so parsing decisions are based on the actual page state.
What is an HTML parser API for web scraping?
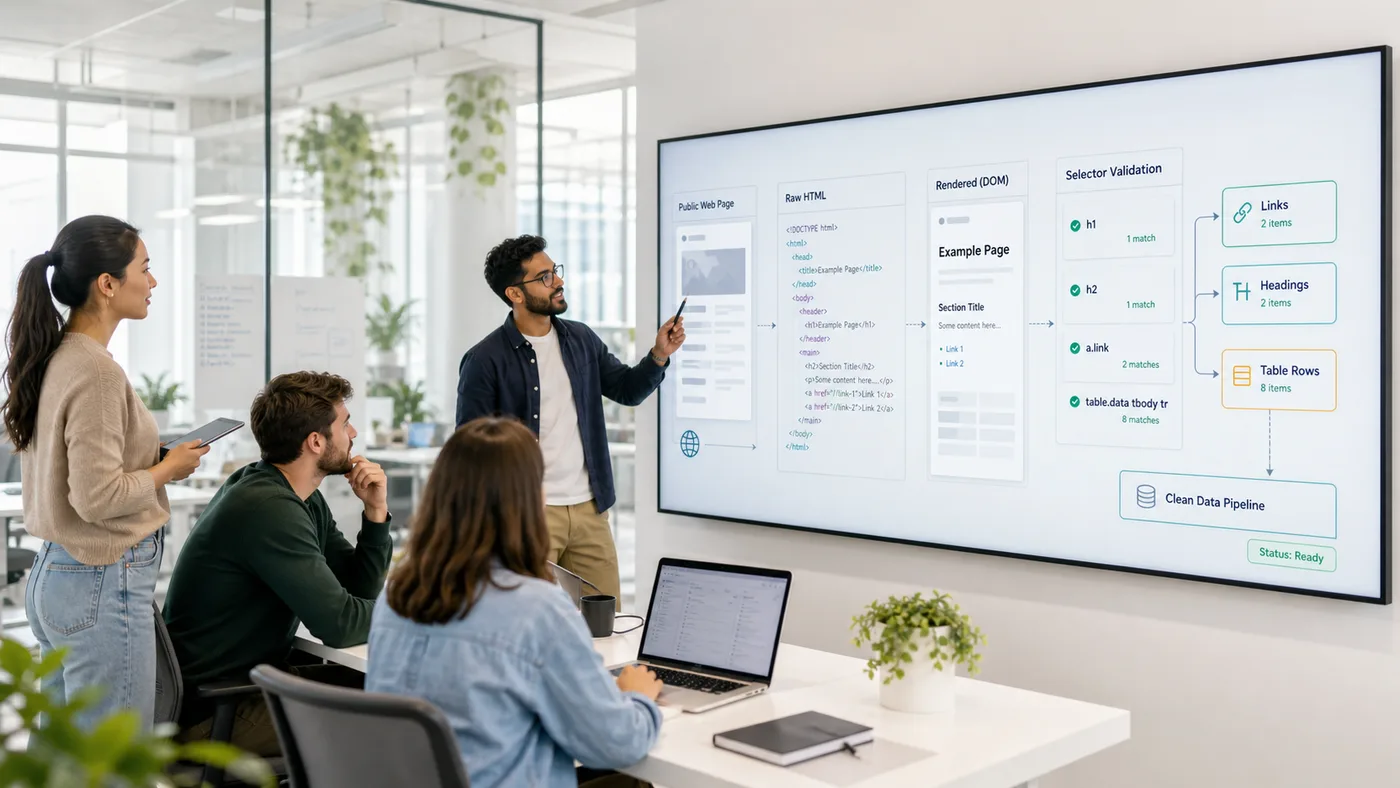
An HTML parser API workflow starts by retrieving a public page and giving your application markup it can inspect. The parser then extracts links, headings, tables, metadata, product cards, article sections, pagination, embedded data, or other page elements from that captured source.
The practical challenge is not only parsing. It is capturing the right version of the page before parsing begins. Some targets expose useful markup in the initial HTML response. Others send an empty app shell and build the DOM in the browser. Some return a different page depending on headers, cookies, region, or routing. ScraperFly handles that capture layer so your parser can work from a verified response instead of brittle browser glue.
When should the parser use raw HTML or rendered HTML?
Raw HTML is the best starting point when the target sends useful markup immediately. It is lighter, faster to inspect, and easier to compare across samples. Rendered HTML is useful when the initial source only contains a route container, hydration script, placeholder nodes, or late-loaded content that appears after browser execution.
The decision should be per target, not global. If every URL is forced through a browser by default, the workflow becomes heavier before the team knows whether rendering improves the captured source. A better pattern is to fetch source HTML first, compare it with the expected fields, then enable rendering only for pages where the parser cannot see the needed markup.
| Parser input | Use it when | Main advantage | Important check |
|---|---|---|---|
| Raw HTML | The initial response contains the links, fields, tables, or content blocks. | Lightweight and easy to debug. | Confirm the markup is present before writing selectors. |
| Rendered HTML | JavaScript builds the useful DOM after the source response loads. | Captures the browser-built page state. | Use rendering only when it changes the response. |
| Text or Markdown | The downstream workflow needs readable content rather than DOM relationships. | Cleaner input for content review, search, and AI workflows. | Do not use it when selectors or attributes matter. |
| JSON metadata | The application needs response context for logging, QA, or routing decisions. | Exposes operational evidence around the capture. | It complements parsing; it does not replace target-specific extraction rules. |
What should teams validate before scaling parser rules?
Parser rules often look stable on one sample and then break across a URL set. The fix is to validate response shape before scale: make sure the same sections exist, expected links are present, tables keep predictable structure, pagination is visible, and the response did not silently redirect to a different page type.
ScraperFly helps by keeping the request controls visible. You can compare raw and rendered output, preserve final URL and status, inspect response size, and use screenshots when visual proof matters. That makes selector failures easier to diagnose: the parser can tell whether the target changed, the markup moved, JavaScript was required, or the capture returned the wrong page.
| Validation point | Why it matters | Parser-safe action |
|---|---|---|
| Expected container | The parser needs a stable section to start from. | Check whether raw or rendered HTML contains the container. |
| Links and pagination | Many crawls fail when next-page links are absent or transformed. | Verify hrefs and page controls across samples. |
| Tables and lists | Data can shift columns, labels, or nesting between templates. | Compare structure before mapping fields. |
| Status and final URL | A parser may receive a login wall, redirect page, or soft block. | Log response evidence with each parsed result. |
| Response format | DOM parsing, text ingestion, and visual QA need different outputs. | Choose HTML, text, Markdown, JSON, screenshot, or PDF based on the consumer. |
Where does ScraperFly fit in an HTML parsing pipeline?
ScraperFly sits before your parser. Your application sends a target URL and a request profile, then receives a response shape your pipeline can use: raw HTML for source parsing, rendered HTML for browser-built pages, clean text or Markdown for content workflows, JSON metadata for diagnostics, or screenshots and PDFs for visual evidence.
That separation is valuable. Your team keeps control over selectors, extraction rules, validation, storage, and business logic. ScraperFly handles the fetch layer, browser rendering when it is actually needed, session and header context, routing options, and response formats. The result is a cleaner boundary between “get the right page source” and “extract the data we care about.”
For a broader view of supported outputs, compare the web scraping API response formats. To test a request profile before writing production code, use the public API Builder.
How can teams keep HTML parsing stable in production?
Production parsing needs evidence, not only selectors. Store the target URL, final URL, status, content type, response size, render setting, timing controls, and chosen output format with each capture. Those fields make it much easier to separate parser mistakes from target changes, delivery problems, and JavaScript rendering gaps.
When the parser starts missing fields, avoid rewriting extraction logic immediately. First inspect whether the captured markup still contains the expected source. If it does, update the parser. If it does not, adjust the request profile: render the page, wait for late content, preserve session state, add legitimate headers, choose country routing, or use stronger delivery for targets that prove they need it.
How does this make scraping cheaper to operate?
HTML parsing becomes expensive when teams use the heaviest request profile for every page. ScraperFly supports a more practical path: start with lightweight HTML capture, inspect whether the markup contains useful data, then add browser rendering, waits, sessions, headers, country targeting, premium routing, screenshots, or PDFs only when the target proves those controls improve the result.
This is especially useful for projects with mixed targets. Simple public pages can stay on simple captures. JavaScript-heavy pages can use rendered HTML. Pages that need proof can add screenshot or PDF output. Uneven projects can use pay-as-you-go credits, while predictable production workloads can move to monthly credits when the pattern is clear. The pricing page explains that path in detail.







