






Proxy routing
Choose stronger delivery only when the target proves it matters
Proxy rotation is valuable when public targets respond differently by route, reputation, region, session continuity, or request pressure. It is also easy to overuse. If every scrape starts with the heaviest route, teams pay more before they know whether the target actually needed that path.
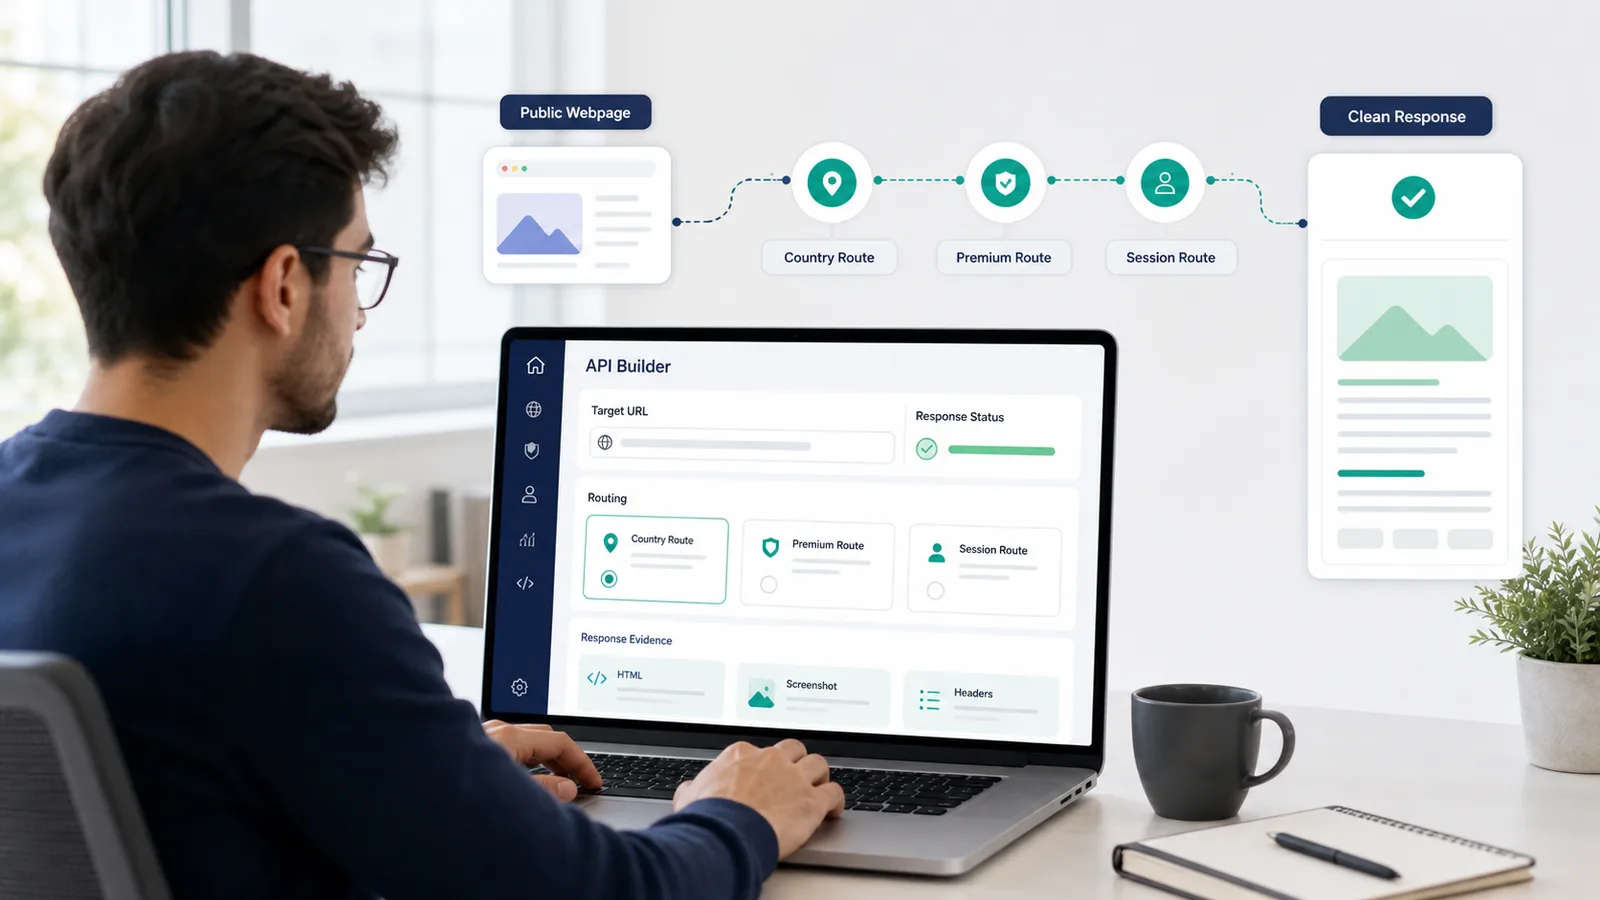
ScraperFly gives teams a practical routing workflow: start with a light request, inspect the response evidence, then add premium routing, country targeting, sessions, headers, rendering, waits, screenshots, or PDFs only where they improve the result. The goal is not more proxy movement. The goal is a cleaner public page capture with fewer blind retries and more predictable cost.
What is a rotating proxy scraping API?
A rotating proxy scraping API fetches public web pages through a managed request layer that can change delivery routes when the target response requires it. Instead of wiring a raw proxy pool into every scraper, the application sends a target URL and request options to one API. The API returns the response in a usable format, while response metadata helps the team understand what happened.
For ScraperFly, proxy routing is one part of a wider capture workflow. A request can stay simple for public pages that return clean HTML. It can add premium routing for harder targets, country targeting when regional context matters, sessions when continuity changes the response, and browser rendering when JavaScript builds the useful page state.
Practical takeaway: use rotating proxy behavior as a measured routing control, not as a default replacement for understanding the target.
When do scraping jobs actually need proxy rotation?
Proxy rotation helps when the delivery path changes the public response. That can happen when a target throttles repeated requests, returns different content by region, behaves differently under a stable session, or responds better through a stronger route. Rotation can also help spread request pressure across a workflow when the target is sensitive to repeated access from one route.
But proxy rotation does not fix every scraping problem. A malformed URL, missing API key, unsupported output format, empty JavaScript shell, too-short render wait, oversized response, redirect loop, or parser bug will not become a good scrape just because the request moves through another route. Those problems need diagnosis, not more rotation.
| Response evidence | Likely meaning | Better next action |
|---|---|---|
| Clean 200 response with useful HTML | The light path is already enough | Keep the simple request profile. |
| Repeated 403 or challenge page | The target may resist the current route | Test stronger routing after confirming the request is valid. |
| 429 or throttling pattern | Request pressure may be too high | Use backoff, reduce concurrency, then consider route changes. |
| Different content by country | The public page varies by region | Use country targeting for regional samples. |
| Empty shell but rendered page has content | JavaScript builds the useful state | Use rendering before blaming the proxy route. |
| Redirects to unexpected pages | Target rules, locale, consent, or route state may differ | Compare final URL, headers, cookies, country, and session behavior. |
How is proxy routing different from premium routing?
Proxy routing is the broad delivery idea: the request can move through managed network paths instead of relying on one direct route. Premium routing is a stronger escalation option for public targets that do not respond well to the simple path. Country targeting is a regional delivery control. Sessions keep continuity across related requests. Headers and cookies carry legitimate request context. Rendering executes browser JavaScript.
These controls often work together, but they solve different problems. Premium routing is not the same as country targeting. A session is not the same as rotation. Rendering is not a proxy fix. Good scraping architecture keeps those choices visible so a team can explain why a request profile exists.
| Control | Use it when | Do not use it as |
|---|---|---|
| Simple request | The target returns useful content without stronger delivery | A sign that the workflow is incomplete. |
| Premium routing | Simple delivery repeatedly fails after the request is validated | The first step for every public page. |
| Country targeting | The response changes by region, language, currency, or availability | A generic anti-blocking switch. |
| Sessions | Related requests depend on shared state or continuity | A replacement for routing evidence. |
| Headers and cookies | The public response depends on accepted request context | A way to promise private access. |
| JavaScript rendering | The useful content appears after browser execution | A proxy strategy. |
What response evidence should guide proxy routing?
The best routing decisions come from response evidence, not from guesswork. Status code, final URL, response size, content type, response body, redirect path, timeout behavior, route country, session state, and screenshot output can all show whether the target needs stronger delivery or a different request profile.
A single failed request rarely proves much. A small sample across route types is more useful: one light request, one request with the needed headers, one rendered request if the page is JavaScript-heavy, one country-targeted request if region matters, and one premium route only if the simpler tests do not return a usable response. That sequence keeps debugging clear.
Use the API Builder to test the request shape before moving it into production. If the page needs browser execution, compare the result with the JavaScript rendering API path before treating the issue as purely proxy-related.
How does ScraperFly reduce proxy infrastructure work?
A raw proxy setup can give a team network access, but it does not usually solve the rest of the scraping workflow. The team still has to maintain request construction, output formats, rendering, retries, headers, cookies, screenshots, PDFs, logging, response diagnostics, billing rules, and operational recovery. That is a lot of glue around every target.
ScraperFly packages the capture layer as an API workflow. Developers can request HTML, clean text, Markdown, JSON metadata, screenshots, or PDFs; add rendering when the page needs browser execution; add sessions or headers when continuity or request context matters; and add routing strength only when response evidence supports it. The team can focus on deciding what data matters instead of rebuilding capture infrastructure for every job.
How can proxy scraping stay cost-predictable?
Cost control starts by matching request weight to the target. A simple public page should not carry the same profile as a rendered browser request with premium routing, session continuity, visual output, and retries. The right process is to classify targets, keep easy pages light, and reserve stronger routing for pages that prove they need it.
ScraperFly's billing path supports that kind of testing. Start with free credits, buy credits for uneven projects, and move to monthly credits when recurring demand becomes predictable. The team can estimate cost from real samples instead of buying a broad proxy setup before the workload is understood.
Review pricing after sampling representative targets. For stateful workflows, compare with web scraping API sessions. For request context, see custom headers for scraping API requests. For regional pages, use country targeting; for harder targets, use premium routing only where the evidence supports it.
Where should a team start?
Start with one real public target URL and the lightest request profile. Check the status, final URL, response size, content type, and body. If the response is useful, keep that profile. If the response is blocked, empty, regional, unstable, or incomplete, change one control at a time and record what improved the result.
That approach makes rotating proxy scraping more practical. The team can explain why a target uses a simple route, a country route, a premium route, a session, rendering, or visual output. It also makes production recovery easier because the next action follows the evidence already captured by the request.

















