






Availability evidence
Capture the page state before stock signals drive decisions
Stock monitoring becomes unreliable when the capture layer cannot explain what it saw. A product can look available in one variant, sold out in another, hidden behind JavaScript, different by location, or temporarily replaced by a soft error page. ScraperFly gives teams a controlled way to capture public product pages before downstream systems label an item as in stock, out of stock, changed, or ready for review.
The goal is not to turn ScraperFly into an inventory database or alerting system. The goal is cleaner source evidence: HTML when the availability signal is already in the markup, rendered output when frontend code creates the final state, metadata for diagnostics, and screenshots or PDFs when a human needs proof of what the page showed.
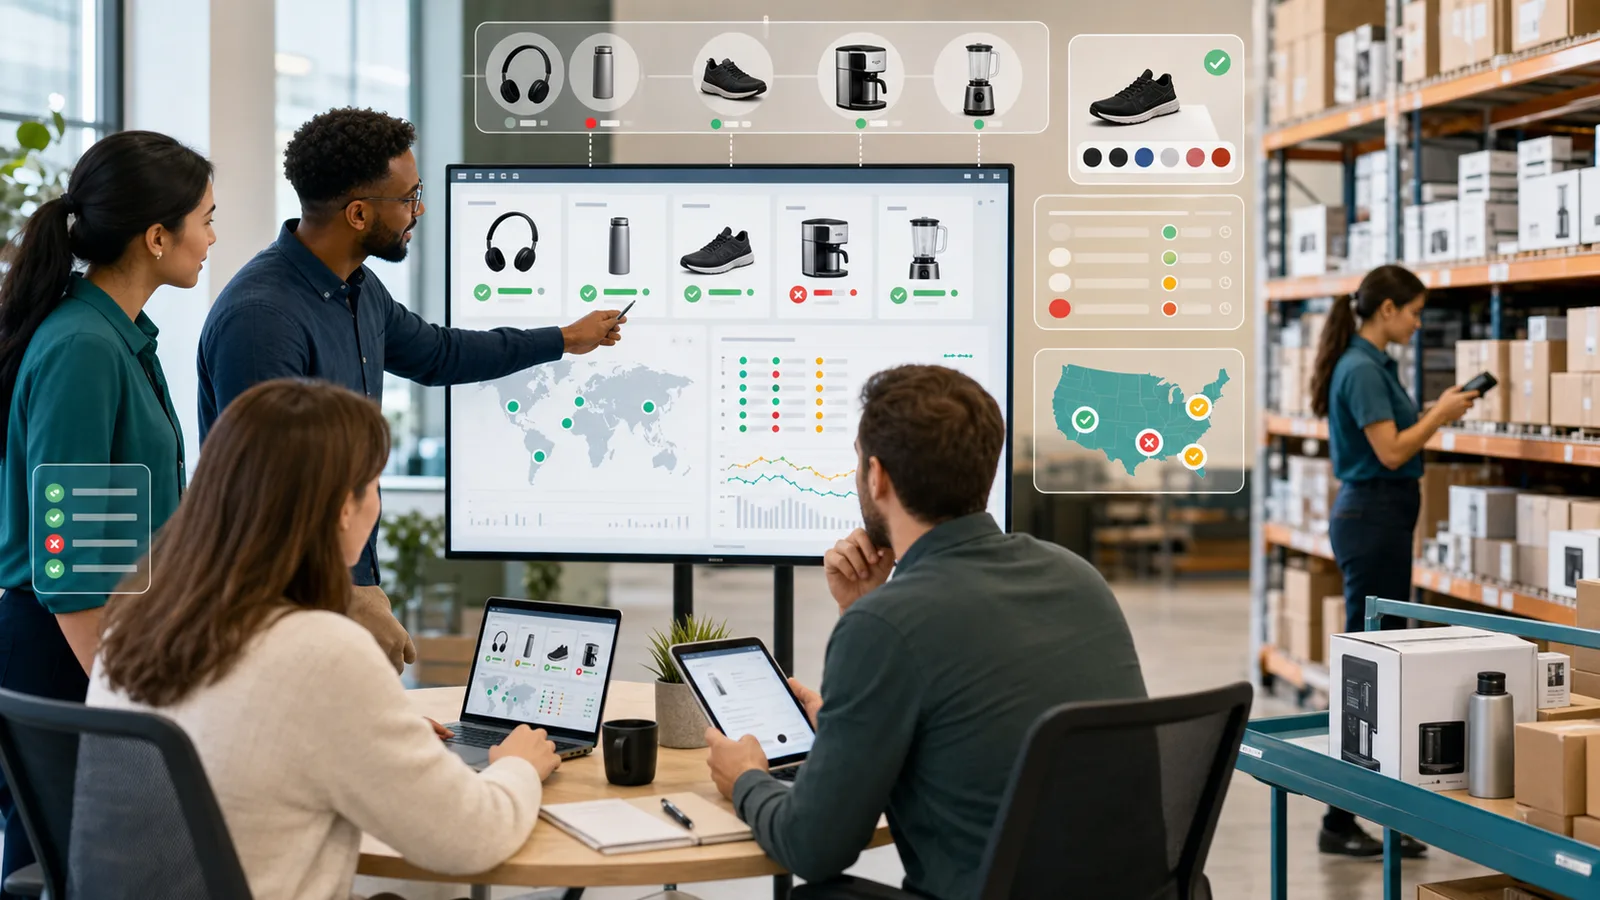
What is a stock availability monitoring scraping API?
A stock availability monitoring scraping API is a capture layer for public product pages. It retrieves the page, returns the response in a usable format, and gives your application enough context to decide whether an availability signal can be trusted. The downstream system still owns the actual monitoring logic: schedules, comparisons, alerts, thresholds, product matching, variant mapping, warehouse rules, and business decisions.
This boundary matters. Public product pages are not always neat data feeds. Availability can appear in source HTML, rendered DOM, embedded data, button labels, store pickup widgets, delivery panels, variant selectors, seller modules, or region-specific templates. A reliable workflow starts by preserving the public page evidence, then builds parsers and alert rules on top of that evidence instead of guessing from a single fragile field.
Practical takeaway: use ScraperFly to capture the public page state clearly, then let your own monitoring system decide what the availability signal means.
What availability evidence should teams capture?
The useful record is wider than a simple true or false value. A monitoring job should know which product was checked, which variant was selected, which seller or store context applied, which region or language influenced the page, what response format was used, and what the page looked like when the signal was captured. Without that context, an alert can become noisy fast: a colorway is sold out but the product is not, pickup is unavailable but delivery is open, a marketplace seller changed, or the request hit a fallback page rather than the actual product page.
ScraperFly helps by keeping the request profile visible. Teams can compare source HTML against rendered output, preserve the final URL and response metadata, request text or Markdown for review workflows, and add screenshots or PDFs for visual proof when availability changes need human verification.
| Evidence area | What to capture | Why it matters |
|---|---|---|
| Product identity | URL, title, SKU, canonical URL, marketplace seller | Prevents alerts from mixing similar products or duplicate pages. |
| Variant context | Size, color, configuration, pack size, selected option | Availability often changes at variant level, not product level. |
| Availability signal | In-stock copy, disabled buttons, stock badge, pickup or delivery state | Gives the downstream parser multiple signals to compare. |
| Market context | Country, language, currency, store, delivery area, cookie state | Public availability can change by geography and session context. |
| Capture proof | Status, final URL, response size, screenshot, PDF, timestamp | Makes false positives easier to investigate after an alert fires. |
Why do false stock signals happen?
False stock signals usually come from a mismatch between what the monitoring system thinks it captured and what the public page actually returned. A request can receive a successful status code but still land on a consent screen, location selector, unsupported-region page, empty app shell, generic product family page, removed-product page, or temporary upstream error. A variant selector may default to a popular size instead of the intended size. A marketplace page may switch sellers. A delivery module may require regional context before it shows a real answer.
The fix is not to make every request heavier. The fix is to preserve enough evidence to diagnose the failure. Compare raw and rendered HTML. Check final URL, response size, content type, and status. Use screenshots for disputed visual states. Add sessions only when continuity changes the response. Add country routing only when regional output matters. Retry temporary failures with bounded backoff, but do not retry invalid URLs, unsupported formats, or authentication mistakes as if they were stock changes.
When should stock monitoring use rendering, sessions, headers, or country routing?
Use JavaScript rendering when the availability signal appears only after browser execution. This is common for product pages with client-side variant selectors, store pickup modules, delivery panels, lazy-loaded inventory widgets, or frontends that hydrate stock state after the initial response. Start by comparing raw HTML and rendered HTML. If rendering does not change the availability evidence, keep the lighter request.
Use sessions when related requests depend on shared state, such as a selected store, region, cookie preference, or multi-step public interaction. Use headers when the page expects legitimate request context like language or accepted content type. Use country routing when availability, pricing, delivery, currency, or storefront content changes by region. Use stronger delivery only when response evidence shows the simple path is unstable.
For deeper setup, review the JavaScript rendering API, sessions API, custom headers scraping API, and country targeting guidance when the public page changes by market.
Which response format fits stock monitoring?
HTML is the natural starting point when your parser needs page structure, buttons, attributes, embedded data, product cards, or variant selectors. Rendered HTML is useful when the browser creates the final DOM. Text and Markdown are helpful for review, QA, and quick inspection when a human needs to understand what the page said without reading markup. JSON metadata helps logging and investigation because the monitoring system can store status, final URL, response shape, and diagnostics with the parsed result.
Screenshots and PDFs are useful when availability needs visual proof. They are not usually the best parser input, but they are valuable for disputed alerts, compliance reviews, QA snapshots, and before-and-after evidence. In practice, many teams store machine-readable output for automation and visual output only for selected events where proof matters.
| Format | Use it for | Best availability fit |
|---|---|---|
| HTML or rendered HTML | Parsers, selectors, embedded data, variant modules | Primary source for product and stock extraction. |
| Text or Markdown | Human review, summaries, QA, AI-assisted inspection | Readable evidence when markup is too noisy for review. |
| JSON metadata | Diagnostics, final URL, status, content type, logging | Operational context for explaining stock alerts. |
| Screenshot or PDF | Visual proof, archives, disputed changes, QA records | Evidence for selected alerts and human verification. |
What should stay downstream from ScraperFly?
ScraperFly should not be treated as a complete stock monitoring platform. It does not schedule every check, decide product matching rules, reserve inventory, alert merchandisers, interpret private inventory systems, or guarantee that public page copy equals actual warehouse stock. Those decisions belong in the application that knows the catalog, stores, rules, thresholds, and business process.
That separation is healthy. ScraperFly captures the public page evidence. Your monitoring system applies product logic, deduplication, variant mapping, alert thresholds, storage, dashboards, and escalation rules. Keeping those responsibilities separate makes the workflow easier to audit because every alert can point back to the response that created it.
How should teams start with ScraperFly?
Start with a small, representative sample: one simple product page, one variant-heavy product page, one regional page, one marketplace or multi-seller page, and one known out-of-stock page. Test them in the API Builder before writing production logic. Capture HTML first, compare rendered output only when the source response is incomplete, and decide which formats your parser, QA process, and archive actually need.
Once the request profile is proven, scale carefully. Keep straightforward pages on lighter requests, group JavaScript-heavy templates separately, and reserve screenshots, PDFs, sessions, country routing, or stronger delivery for targets that have shown a real need. When planning recurring checks, review pricing so request weight, check frequency, and monitoring value stay aligned.
Related workflows often share the same capture decisions. Product catalog teams can use the product data extraction guidance, ecommerce teams can compare broader ecommerce scraping patterns, and teams tuning output shape can review response formats before building converters.








































