






Review evidence
Capture reviews with the context that makes them trustworthy
Review monitoring is not just a star counter. Teams need the public review text, rating, date, source URL, product or location context, pagination state, language, and enough evidence to understand whether a change is real.
ScraperFly gives teams a practical capture layer for public review pages. Start with the lightest response, inspect the source, add rendering or routing only when the review page proves it needs them, and send cleaner evidence into your monitoring, reputation, product feedback, or reporting workflow.
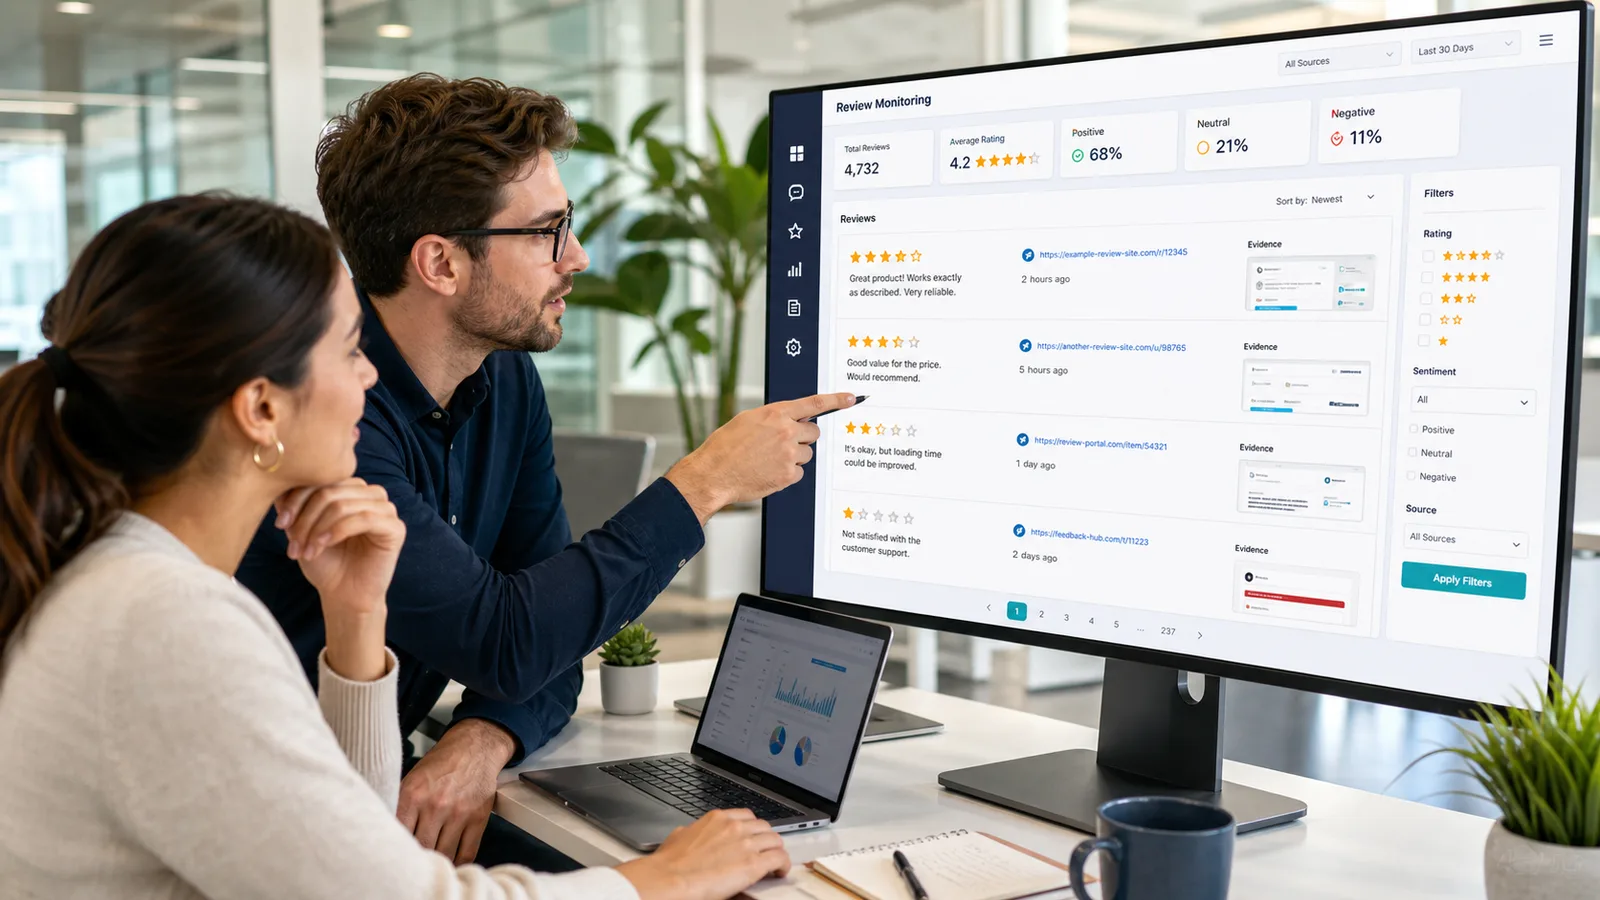
What is a review monitoring web scraping API?
A review monitoring web scraping API captures public review pages and returns the page evidence your application can inspect, parse, compare, archive, or route into downstream systems. The response can be raw HTML, rendered HTML, readable text, Markdown, JSON metadata, a screenshot, a PDF, or another supported format depending on how the review source behaves.
The API does not replace your review intelligence layer. Your product still owns sentiment scoring, deduplication, alert rules, customer response workflows, trend reporting, and storage. ScraperFly handles the public page capture side so those systems receive consistent source evidence instead of a fragile mix of local fetchers, browser workers, proxy experiments, and one-off converters.
Practical takeaway: use a review scraping API to collect trustworthy public source evidence before your own system decides what changed and what matters.
Which review fields should teams capture?
Useful review monitoring starts with fields that help a team verify the source, understand the customer signal, and compare changes over time. A rating without review text can hide the reason behind the score. Review text without date and source context can become difficult to trust. A capture without pagination or sort state can miss new reviews or double-count old ones.
Teams usually need both business fields and operational fields. Business fields describe the review itself. Operational fields explain how the page was captured and whether the result is reliable enough to compare, alert, or archive.
| Field group | Examples | Why it matters |
|---|---|---|
| Review signal | Rating, title, review body, pros, cons, response text | Shows the customer or user feedback your monitoring workflow is meant to track. |
| Source context | Product, location, profile, marketplace, category, source URL | Keeps each review tied to the public page and business object it belongs to. |
| Freshness | Review date, capture time, sort order, page number, final URL | Helps teams separate new reviews from reordered, paginated, or stale captures. |
| Quality evidence | Status, content type, response size, rendered state, screenshot, PDF | Explains whether a missing or changed review is a real source event or a capture issue. |
How do review pages fail in production?
Review pages can look simple in a browser and still be unstable as monitoring sources. Sorting can change the order of reviews. Filters can hide lower ratings. Pagination can lazy-load older reviews. Location, language, currency, cookies, or device context can change which reviews are visible. Some pages show summaries in source HTML while hiding full review text behind JavaScript. Others return a normal status code with an empty or partial review section.
The most expensive monitoring mistakes happen when those source behaviors are treated as business events. A missing review should not automatically become a deletion alert. A smaller response should not automatically become a reputation signal. A regional variant should not be compared against a different market as if both pages were the same source.
ScraperFly helps by making the capture profile explicit. Teams can inspect the final URL, status, response size, content type, source HTML, rendered state, screenshot proof, and output format before deciding whether the downstream workflow should retry, escalate, ignore, or alert.
Practical takeaway: review monitoring should compare source evidence, not just extracted fields.
When should review monitoring use JavaScript rendering?
Use JavaScript rendering when useful review content appears only after browser execution. That is common on review widgets, marketplace pages, location pages, and product pages where the first HTML response contains scripts, containers, summaries, or placeholders instead of the full review list. Rendering can expose the final DOM that a user would see after the page loads.
Rendering should still be a measured choice. Start by capturing source HTML. If the rating, review text, date, pagination controls, or response state are already present, keep the request lightweight. If they are missing or incomplete, compare rendered output and add waits only when timing changes the result. For deeper browser decisions, connect this page to the JavaScript rendering API and headless browser scraping API guides.
How should teams handle pagination, sorting, and regional review pages?
Review monitoring needs repeatable capture conditions. If one run uses newest-first sorting and another uses relevance sorting, the extracted reviews can look different even when the source has not changed. If one market shows local reviews and another market shows global reviews, comparing them directly can create false movement. If pagination is inconsistent, recurring jobs may skip older reviews or reprocess the same ones.
Build the workflow around source classes. Product review pages, location review pages, marketplace seller pages, app store listings, and testimonial pages can each need a different request profile. Track the URL pattern, sort mode, language, country, pagination method, and rendered behavior for each class. Then choose whether your downstream system should monitor only the first page, crawl multiple pages, follow next links, or use snapshots as review evidence.
Which response format is best for review monitoring?
The best response format depends on what happens after capture. HTML is useful when your parser needs selectors, attributes, embedded data, or DOM structure. Text and Markdown are useful when teams need readable content for review, summaries, AI-assisted triage, or internal search. JSON metadata helps debugging and logging because it preserves request context such as status, final URL, content type, and response size. Screenshots and PDFs are heavier, but they help when a stakeholder needs visual proof that a rating, badge, response, or review state appeared on the public page.
The broader response formats guide is useful when teams need to choose between parser-ready HTML, readable Markdown, metadata, screenshots, and PDF output. For review monitoring, the main rule is simple: pick the smallest output that preserves enough evidence for the decision.
| Monitoring need | Useful output | Decision rule |
|---|---|---|
| Custom review extraction | HTML or rendered HTML | Use when selectors, structure, or embedded data matter. |
| Readable review analysis | Text or Markdown | Use when downstream systems need clean customer language. |
| Alert debugging | JSON metadata | Use when status, final URL, content type, and size explain the capture. |
| Stakeholder proof | Screenshot or PDF | Use when a review change needs visual confirmation or archive evidence. |
How can review monitoring stay affordable?
Review monitoring can become expensive when every source is treated like a hard target. Rendering every page, waiting on every request, creating screenshots for machine-only workflows, or routing every capture through stronger delivery can add weight before the source proves it needs that work. A better path is to classify review sources and keep the default profile light.
Start with a few real public URLs from each source type. Capture source HTML, inspect the result, and only add rendering, waits, sessions, headers, country targeting, premium routing, screenshots, or PDFs where they improve completeness or proof. When recurring volume becomes predictable, review pricing and the credit cost calculator so monitoring jobs match the request profiles they actually use.
Practical takeaway: keep simple review pages on lightweight capture and reserve heavier controls for sources that prove they improve monitoring quality.
How should teams start with ScraperFly?
Start in the API Builder with one representative public review URL. Capture source HTML first, then compare text, Markdown, metadata, rendered output, screenshot, or PDF only when the workflow needs those shapes. Check whether rating, review body, author display name, review date, source URL, pagination, and sort context are present before building production extraction.
Once the request profile is proven, move it into the downstream monitoring system. Use ScraperFly for public page capture, then let your own product handle deduplication, sentiment, alerting, dashboards, history, and business rules. For adjacent monitoring patterns, compare this workflow with website change monitoring, brand monitoring, and sentiment analysis.












