






ScraperFlyAI-ready Web Data API

request control

Scraping API 403 errors: classify before escalating

A 403-style failure can point to very different work: fix API authorization, inspect a target-side forbidden response, add legitimate request context, or escalate routing for a hard public target. ScraperFly helps teams treat 403 as evidence, not a reason to retry blindly.

403 diagnosis workflow

Separate API authorization from target-side rejection before changing controls

A 403 in a scraping workflow is not one problem. It can mean the API request was not authorized, the account key is invalid or paused, or the public target returned a forbidden response after ScraperFly made the delivery attempt. Those cases need different fixes.

ScraperFly helps teams treat 403 as evidence. Check whether the failure happened at the API layer or at the target layer, inspect the response, then add headers, sessions, rendering, country routing, or premium delivery only when the target behavior makes that step reasonable.
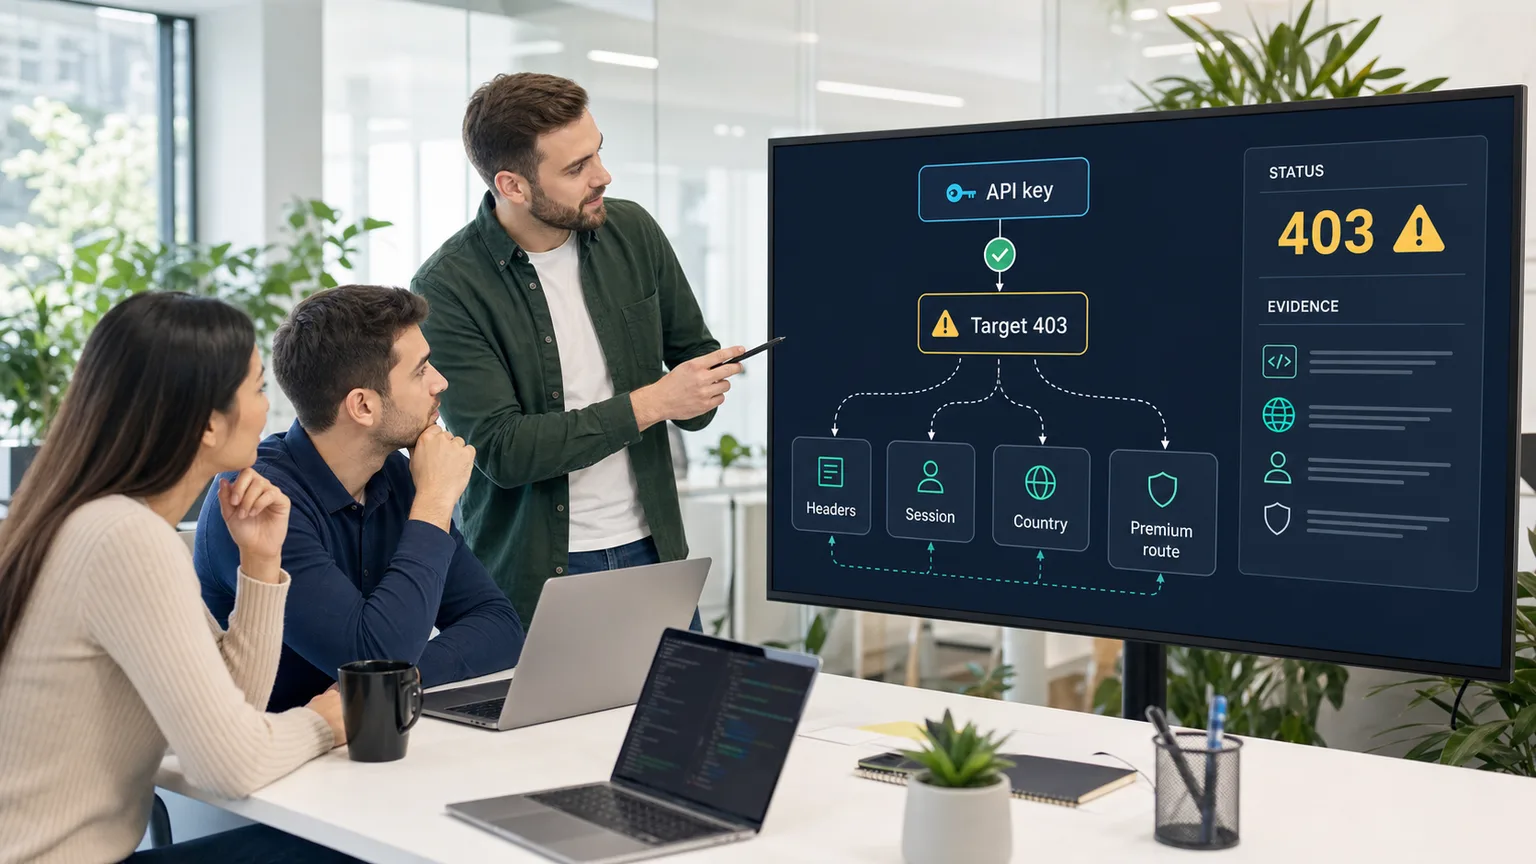
API keytarget 403evidence first
Team diagnosing a scraping API 403 error with API key, target 403, headers, sessions, country, and premium route checks

What does a 403 mean in a scraping API?

A 403 means something refused access, but the important question is where that refusal happened. If the API key is missing, invalid, disabled, or attached to an account that cannot make the request, the fix is configuration. Changing headers or proxies will not help because the request never became a meaningful target delivery attempt.

If the API call is valid and the public target returns a 403, the response becomes target evidence. It may reflect missing request context, regional behavior, a stricter target rule, a challenge page, a WAF decision, a route that expects continuity, or a target that does not expose the content through that request path. The next step is diagnosis, not blind retry volume.

Practical takeaway: classify the 403 source first, then choose the smallest change that explains the target behavior.

How do you tell API auth errors from target 403 responses?

Start with the layer that rejected the request. API authorization issues usually point to credentials, account state, request permissions, or missing required parameters. Target-side 403 responses show that a delivery attempt reached the public target and the target refused that request profile. Those two paths should never share the same recovery playbook.

For target-side 403 responses, compare a few samples instead of reacting to one event. Look at the final URL, status, content type, response size, body text, redirect behavior, whether a challenge page appeared, and whether the result changes with legitimate context such as language, session continuity, rendering, country routing, or delivery route.

403 signal Likely meaning Best next action
Missing or invalid API key The request failed before useful target delivery Fix authentication and account configuration before retrying.
Target returns a clear 403 page The public target rejected the current request profile Inspect response evidence before changing controls.
403 changes by country The page may be region-sensitive Test country routing only for affected route patterns.
403 follows consent or state changes The workflow may depend on continuity Use sessions or allowed cookies when public context requires them.
403 appears only on JavaScript-heavy pages The source request may not reproduce the browser-visible path Compare source output with rendered state and visual proof.
Repeated 403 on standard routing The target may require stronger delivery quality Escalate routing after evidence shows simpler controls are not enough.

Which controls should you test after a target-side 403?

Test one control at a time. Headers are useful when the target expects legitimate request context such as language, accepted content type, or referer. Sessions are useful when public pages depend on continuity, preferences, consent state, or cookies from a previous request. Browser rendering is useful when the response changes after JavaScript execution. Country routing is useful when public content differs by geography. Premium routing is useful when route reputation is the limiting factor.

That order matters because each control adds weight and complexity. If a page only needed an accepted language header, using a browser with premium routing hides the real requirement and makes every future request more expensive. If a target truly needs stronger routing, headers alone will not solve it. A small evidence loop keeps the recovery path honest.

Use the custom headers scraping API, web scraping API with sessions, JavaScript rendering API, and rotating proxy scraping API pages to compare request controls before moving a route into production volume.

How should a production system handle 403 retries?

A production system should not retry every 403 as if it were a temporary network failure. Retry policy should be tied to evidence. Temporary transport issues, rate-limit patterns, or upstream instability may justify bounded retries with backoff. A stable 403 response usually needs classification and a request profile change, not more copies of the same request.

Log the response evidence with the target route, request profile, final URL, status, response size, and chosen controls. That turns 403 handling into a decision system. Over time, your team can identify route classes: pages that work with basic HTML, pages that need headers, pages that need rendering, pages that need country routing, and pages that are not worth escalating for the value they return.

Recovery step Use it when Keep it controlled by
Fix API auth The key is missing, invalid, paused, or unauthorized Checking account and request configuration first.
Add allowed headers The public target expects clear language or content context Forwarding only the headers the workflow actually needs.
Use sessions Related requests depend on shared public state Scoping sessions to route classes with continuity requirements.
Render the page Useful content or target behavior appears after JavaScript execution Comparing source and rendered output before enabling the browser.
Use country routing Public content or access rules differ by region Testing the affected countries rather than changing every request.
Escalate delivery Standard routing repeatedly returns unusable target responses Applying stronger routing only to hard target patterns.

When is a 403 not worth escalating?

Some targets are expensive to recover relative to their value. If the page is not public, requires an account, blocks automated access under its rules, or only returns useful content after a fragile chain of context, escalation may not be the right business decision. A reliable scraping system should know when to stop as well as when to add controls.

This is where ScraperFly's evidence-first workflow helps. You can test the route, compare response shapes, estimate request weight, and decide whether the target justifies rendering, sessions, country routing, premium delivery, screenshots, or PDFs. A page that does not justify the heavier path should not define the default profile for every other target.

How does ScraperFly make 403 handling easier?

ScraperFly gives teams one API layer for request controls and response evidence. Instead of stitching together raw HTTP clients, browser workers, proxy pools, retry logic, logging, screenshots, and converters, your team can test the target path, inspect the result, and change the request profile deliberately.

Use the API Builder to compare a simple request with targeted controls. Start with the lightest useful profile, then add headers, sessions, rendering, country routing, or premium delivery when the evidence says that control changes the response. The pricing page and web scraping API credit cost calculator help keep those decisions connected to cost before volume grows.

Practical takeaway: 403 handling should make the next action clearer: fix authorization, adjust legitimate context, render when browser state matters, route when geography or reputation matters, or stop when escalation is not worth it.


403 evidence check

Classify the 403 before changing headers, rendering, or routing

A useful 403 workflow starts by separating API authorization from target-side rejection. ScraperFly helps teams inspect final URL, status, content type, response size, body evidence, rendered state, and route behavior before they add heavier controls.

Raw HTML response mapped to visible page data
01

Raw HTML availability

Check whether the fields you need are already present in the first HTML response.

Best first test for simple pages, articles, docs, listings, and product details.

Before and after JavaScript rendering comparison
02

JavaScript dependency

Compare raw HTML with the rendered DOM or screenshot before turning on browser rendering.

Use rendering when raw HTML is only a shell and scripts create the useful content.

Cookies, consent, session and access context for scraping
03

State & access context

Identify whether cookies, consent, login boundaries, pagination, or the same visitor state affect the response.

Use sessions and headers when continuity changes the data you receive.

Regional content variations across countries and routes
04

Geo/content variation

Test whether country, language, currency, inventory, SERP, ads, or route reputation changes the result.

Use geo or premium routing only when the target proves the response varies by route.

Checks that turn a 403 into a clear next action

Where is the target field?

Find whether the field exists in raw HTML, rendered DOM, an API call, structured data, a file, or a later interaction state.

What changes the response?

Sample a few URLs and compare status, final URL, content length, redirects, empty states, and visible result differences.

What context is required?

Mark any dependency on consent, locale, cookies, headers, authentication boundary, pagination, filters, or previous requests.

What does failure look like?

Define the signals for blocked, partial, stale, redirected, empty, timed-out, or region-mismatched responses before scaling.

Read the failure before choosing recovery controls

Fetch mode

Raw HTML availability decides whether the first request can stay simple or needs rendering, waits, screenshots, or extraction.

Request context

State requirements decide whether to add headers, cookies, sessions, consent handling, or a stable visitor profile.

Routing choice

Geo and reputation findings decide whether standard routing is enough or a country/premium route is justified.

Validation rules

Known failure states become checks for retries, escalation, QA review, and deciding when a lighter profile is still complete.

403 escalation

Escalate from simple delivery to stronger controls only when evidence repeats

A target-side 403 can point to missing public request context, regional behavior, browser-built state, route reputation, or a hard target. ScraperFly keeps escalation practical: add headers, sessions, rendering, country routing, or premium delivery in steps instead of making every scrape carry the heaviest profile.

A simple HTTP request returning a clean HTML response
01

Plain HTML request

Use this first for public pages that already include the required data in the initial HTML.

A page changing from an empty HTML shell to a rendered DOM after JavaScript runs
02

JavaScript rendering

Enable rendering when the server returns a shell, but the useful page content appears only after JavaScript executes.

Headers, cookies and session state preserved across two requests
03

Headers, cookies & sessions

Use visitor-state controls when the target expects continuity between requests or returns different content after consent, locale, or navigation state is set.

A request routed through a selected country and higher reputation proxy path
04

Premium proxy & geo

Escalate routing when the response depends on request origin, IP reputation, or target geography.

A browser automation flow with search, filters, scrolling and data capture steps
05

Browser flow

Use a full browser flow when the data is behind interaction rather than a single request: search boxes, filters, scrolling, tabs, or multi-step navigation.

Escalate when:

01

Plain HTML request

the raw response contains the fields you need, status codes are stable, and page size/content do not collapse after repeated checks.

  • Product details, article text, documentation, or listings are visible in the HTML response.
  • The final URL, status, and content length stay consistent across a small sample.
  • No consent wall, visitor state, or client-side API call is required for the target fields.
02

JavaScript rendering

the raw HTML is mostly placeholders, the rendered DOM contains the target fields, or key data arrives through client-side requests.

  • Raw HTML has app containers, loading skeletons, or empty product grids.
  • Browser inspection shows the fields after scripts finish.
  • Screenshots look correct while the HTML response alone is incomplete.
03

Headers, cookies & sessions

pagination, reviews, filters, or consent flows depend on the same visitor context across multiple requests.

  • The first request sets cookies that change later responses.
  • Locale, consent, currency, cart, or filter state must be preserved.
  • The page redirects or empties out when requests look stateless.
04

Premium proxy & geo

the same URL behaves differently by region, returns 403/429 from one route, or shows location-specific pricing, availability, SERP, ads, or catalog data.

  • Datacenter-like traffic receives blocks while a higher-reputation route works.
  • Country, language, currency, inventory, or search results change by geo.
  • Repeated requests trigger rate limits or challenge pages on specific routes.
05

Browser flow

the target data appears only after user-like navigation steps, or protected areas such as reviews, profiles, search result refinements, or special data panels behave differently from simple detail pages.

  • A click, scroll, search, or filter action is required before the fields appear.
  • Reviews, profiles, or dynamic result pages load in separate steps.
  • Simpler fetch/render attempts return partial content, challenge pages, or unstable states.

Stay lower & Credit impact:

01

Plain HTML request

Stay lower: the page already returns complete data. Adding rendering or premium routing here only adds latency and credit usage without improving the result.

Credit impact: lowest request profile because it avoids browser work and special routing.

02

JavaScript rendering

Stay lower: the fields are already present in raw HTML. A modern-looking site does not automatically mean JavaScript rendering is needed.

Credit impact: higher than plain HTML because browser work, wait time, and page resources are involved.

03

Headers, cookies & sessions

Stay lower: public content is stable without state. Do not invent sessions for pages that can be fetched cleanly as anonymous HTML.

Credit impact: usually moderate; the bigger cost is operational complexity and retry discipline.

04

Premium proxy & geo

Stay lower: the target is globally consistent and accepts normal routing. Premium and geo routing should be tied to evidence, not used as a default blanket setting.

Credit impact: can increase credit usage and latency, so apply it to the URL groups that actually need it.

05

Browser flow

Stay lower: a single HTML or rendered request already returns the target. Browser flows are the strongest tool in this ladder, not the default starting point.

Credit impact: highest request profile because it combines browser runtime, waits, navigation, and often heavier routing.

Escalate by evidence, not by habit

  • For most public websites, a plain HTML request or light JavaScript rendering is enough. Start there, inspect the response, and only then decide whether the next step is justified.
  • Anti-bot signals are usually visible in the response: unexpected 403 or 429 statuses, sudden redirects, tiny or empty HTML, challenge pages, CAPTCHA screens, login or consent loops, and content that disappears after repeated requests.
  • Large high-traffic targets such as Amazon, Google, LinkedIn, Instagram, TikTok, and major marketplaces often protect some surfaces aggressively. They may require rendering, sessions, careful routing, or a browser flow, and each target needs its own test profile.
  • Protection is not uniform even inside one site. Product/detail pages may open with a lighter profile, while reviews, profiles, search pages, price-sensitive views, availability panels, or account-adjacent data can require stronger escalation.
  • Geo and premium proxy settings affect both what you receive and how expensive the request profile becomes. Use them when country-specific content, IP reputation, or repeated blocks prove they matter.
  • The practical goal is not to turn on every ScraperFly control. The goal is to find the sufficient level that returns complete, repeatable data while keeping credit usage, latency, and failure modes under control.

403 recovery builder

Build a recovery request that changes the control most likely to matter

Use the API Builder to compare a simple request with targeted recovery options. Inspect the response evidence, then add allowed headers, sessions, rendering, country routing, or premium delivery only when that control explains the target-side 403.

01
01

Fix API authorization before target diagnosis

Missing, invalid, or paused keys are configuration work. Do not spend time changing routing when the API request itself is not authorized.

02
02

Add legitimate request context when the target expects it

Headers, cookies, or sessions help when public content depends on language, preferences, consent state, or request continuity.

03
03

Use rendering, country routing, or premium delivery for proven target behavior

Move up only when source evidence, rendered state, geography, or repeated samples show the lighter profile is not enough.

403 recovery controls

url

The public URL returning a target-side 403.

keep_headers

Forward allowed request context such as language or referer when needed.

session

Reuse public context for related requests that depend on continuity.

render

Run a browser when JavaScript state changes the page evidence.

country

Test regional behavior when access or content differs by location.

premium

Use stronger routing for hard target patterns after lighter profiles fail.

cURL example

Generate Markdown with the same request shape you can move into production

curl "https://scraperfly.com/api/v1?url=https%3A%2F%2Fexample.com&format=markdown" \
  -H "apikey: YOUR_API_KEY"

403 cost control

Keep 403 recovery affordable by escalating one control at a time

A 403 on one hard route should not make every scraping job expensive. ScraperFly helps teams prove which targets need headers, sessions, rendering, country routing, or premium delivery, then keep simple pages on lighter request profiles.

A lightweight HTML request returning a simple response
01

Basic fetch

Use a basic fetch when public HTML already contains the fields you need.

Lightest request profile; keep it when the response is complete.

JavaScript rendering producing a complete DOM
02

Rendering

Use rendering when raw HTML is a shell and JavaScript completes the page.

Heavier profile; use it only when browser output changes the result.

Several requests preserving cookies and visitor state
03

Stateful session

Use sessions when cookies, consent, locale, or pagination change the response.

Heavier state profile; preserve it only when continuity matters.

Request routing through geo and higher quality routes
04

Premium routing & geo

Use premium routing or geo only when origin, country, reputation, or regional content changes the result.

Heaviest routing profile; apply it only to targets that prove they need it.

What increases recovery cost

More infrastructure work

Browser rendering, routing choices, and longer waits mean the platform has to do more than return a simple response.

More target uncertainty

Redirects, empty states, rate limits, and challenge pages often require stronger delivery options or retries.

More state to preserve

Cookies, sessions, consent, and multi-page flows add moving parts that a plain stateless fetch does not have.

More evidence to return

Screenshots, PDFs, rendered output, and richer response artifacts are useful, but they are heavier than plain HTML.

How to keep 403 handling predictable

Sample before scale

Test a small URL set first and group targets by the lightest profile that returns complete data.

Do not render by default

Inspect raw HTML before turning on rendering. Many public pages already contain the data you need.

Escalate by evidence

Move up only when the response shows missing content, state dependency, geo variance, or routing problems.

Measure useful results

Optimize around valid records delivered, not raw request volume. A lighter profile is best only when it stays complete.

403 questions

Common questions about scraping API 403 errors

Quick answers for teams evaluating web scraping API behavior: request formats, JavaScript rendering, proxy routing, credits, files, security, and billing.

Quick answers

API or target rejection

Find where the refusal happened before changing controls.

Is every 403 a target block?

No. Some 403-style failures are API authorization issues. Check keys and account state before diagnosing target delivery.

What proves it is target-side?

A valid API request that reaches the public target and returns a forbidden response, block page, challenge, or access-denied body.

Headers and sessions

Use context when public route behavior depends on it.

When do headers help?

Headers help when the target expects legitimate context such as language, content type, or referer.

When do sessions help?

Sessions help when related public requests depend on shared cookies, preferences, consent state, or earlier route context.

Rendering and routing

Move up when response evidence supports the heavier path.

Should I render after a 403?

Render when browser execution changes the public page state. Rendering is not a universal fix for access rejection.

When should premium routing be used?

Use premium routing after repeated target evidence shows standard delivery is the limiting factor.

Retries and budgets

Avoid turning one hard target into an expensive default.

Should 403 responses be retried?

Only retry when evidence suggests a temporary condition. Stable 403 responses need diagnosis or a profile change.

How do I keep costs down?

Classify routes, keep simple pages light, and reserve heavier controls for targets that prove they need them.










