






Platform fit
Keep capture focused when your product owns the data logic
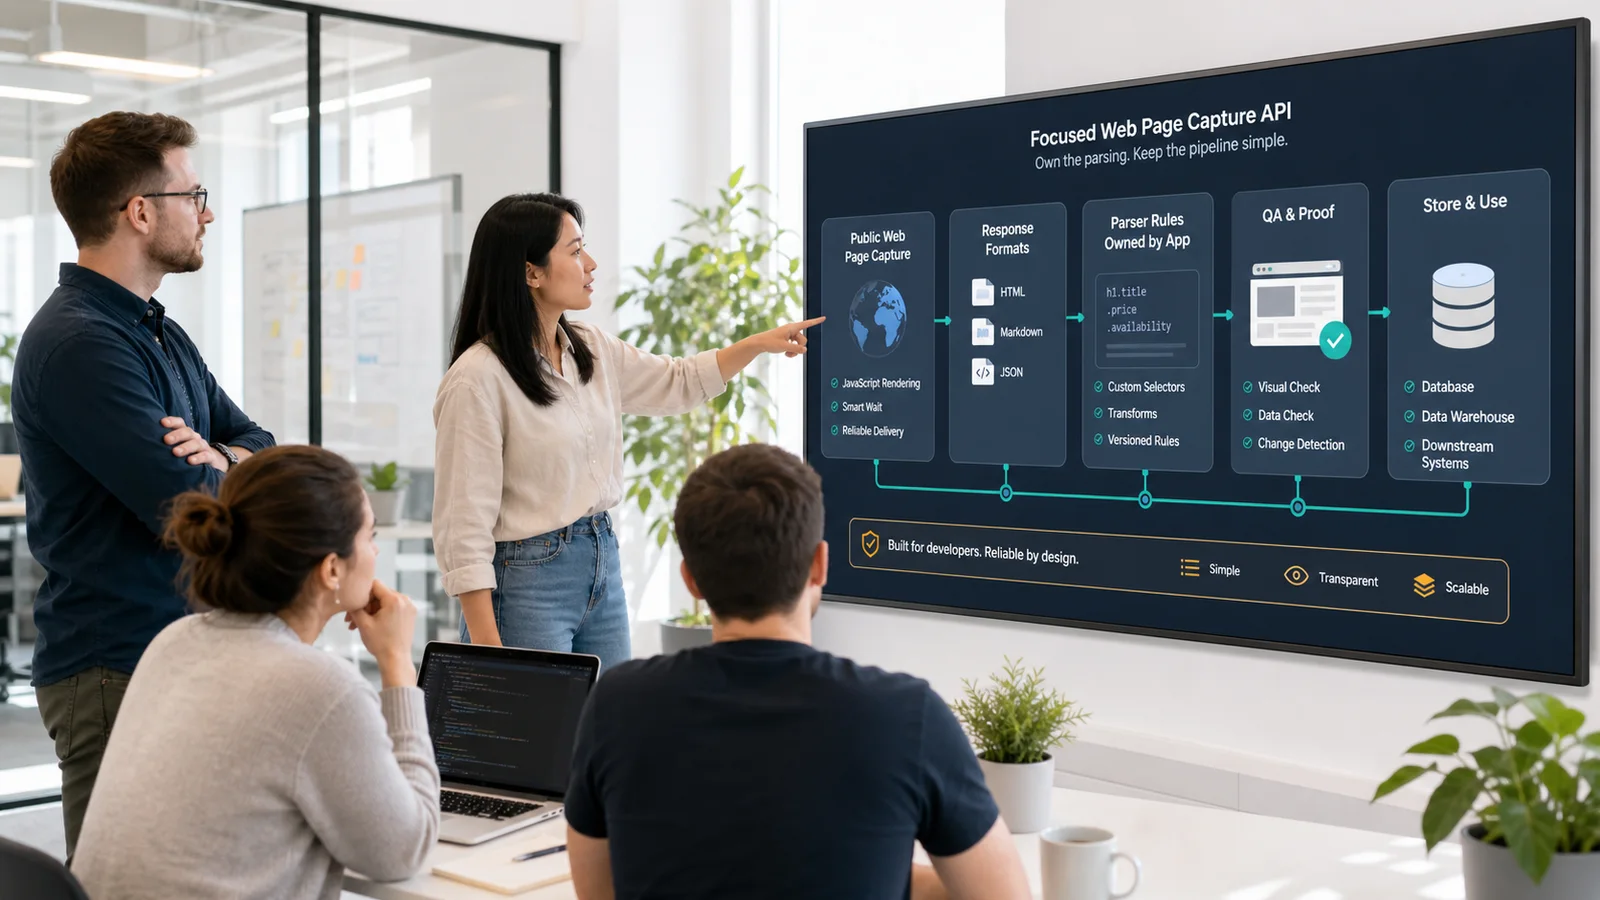
Zyte is often evaluated by teams looking at a broader scraping and extraction platform. That can be useful when the buying decision includes managed extraction, predefined data schemas, crawling operations, and platform-level data delivery. ScraperFly fits a different, very practical need: your team wants a dependable public page capture API while keeping parsing rules, enrichment, QA, storage, monitoring, and product logic inside its own stack.
That distinction matters. Many teams do not need to move the whole data workflow into a managed platform. They need to fetch public pages reliably, compare raw and rendered output, choose the right response format, keep request cost visible, and send the result into systems they already control. ScraperFly keeps that capture layer direct, flexible, and easy to test before production volume grows.
What should a Zyte alternative solve?
A useful Zyte alternative should make the operating model clear. Are you buying a broad managed data platform, or do you need a focused API layer that captures public pages and returns evidence your own application can use? The answer changes the page, the workflow, and the cost model.
ScraperFly is strongest when the team wants to keep control. Developers can start with source HTML, enable JavaScript rendering when client-side code changes the useful content, use headers or sessions when request context matters, choose country targeting or stronger routing when target behavior proves it is needed, and return the response as HTML, text, Markdown, JSON metadata, screenshot, or PDF.
That makes the first production decision smaller. Instead of buying around a full extraction platform before the target is understood, the team can validate capture behavior first and decide what parsing, enrichment, review, or storage should happen downstream.
Where does a managed platform become more than you need?
Managed scraping platforms can be attractive because they combine many layers: delivery, rendering, proxy routing, extraction, schemas, and data operations. The trade-off is that the workflow can become larger than the actual problem. If your application already has parser rules, validation checks, data models, and storage, a broader platform may add decisions your team does not want to hand off.
ScraperFly keeps the capture boundary clean. The API handles the public page request and the response shape. Your product keeps the domain logic: which fields matter, how records are validated, which changes are important, where data is stored, and how downstream systems consume it.
| Workflow layer | Broad platform approach | ScraperFly approach |
|---|---|---|
| Page capture | Often bundled with extraction and platform workflows. | Focused API request with explicit delivery controls and response formats. |
| Rendering | May be part of a larger extraction source decision. | Enable browser rendering when source HTML does not contain the content you need. |
| Extraction logic | Can be managed or schema-driven inside the platform. | Your application owns selectors, parsing rules, validation, enrichment, and storage. |
| Output formats | Often optimized around extracted records or platform outputs. | Return HTML, text, Markdown, JSON metadata, screenshots, or PDFs depending on the next step. |
| Cost control | Pricing can reflect target complexity, rendering, extraction, and account commitments. | Start free, keep simple captures light, and add heavier controls only after target evidence supports them. |
How should teams test ScraperFly against Zyte?
Use real targets instead of feature checklists. A comparison becomes useful when the team can see what each page returns, which controls change the result, and which response format is easiest for the product to consume. Start with the public URL. Capture source HTML. Compare rendered output when the source response is thin. Check status, final URL, content type, response size, redirects, and visual proof when the page is sensitive to browser state.
Then decide how much platform ownership the workflow really needs. If the team wants a vendor-managed extraction layer for standardized records, that is one kind of purchase. If the team wants to keep extraction and business logic in its own code while using an API for capture, rendering, routing, screenshots, PDFs, and response formatting, ScraperFly is the cleaner fit.
Which response shape belongs in production?
The response format is not a cosmetic option. It decides how much code your team writes after the capture succeeds. HTML is useful when parsers need DOM structure, attributes, links, tables, or embedded metadata. Text is useful for lightweight search, indexing, and monitoring. Markdown works well when human-readable structure helps content review, RAG, summarization, and internal tools. JSON metadata gives operations context for logging and debugging. Screenshots and PDFs provide visual evidence when layout, compliance, QA, or archive workflows matter.
ScraperFly lets the team pick that shape before building converters. This is one of the main reasons to evaluate it as a Zyte alternative: the capture API should make the next engineering step easier, not merely prove that the target can be reached.
| Production need | Useful ScraperFly output | Why it helps |
|---|---|---|
| Selectors and parser rules | Raw or rendered HTML | Preserves page structure, attributes, headings, links, and DOM relationships. |
| Content review or AI ingestion | Text or Markdown | Reduces layout noise and gives downstream systems cleaner reading material. |
| Debugging and observability | JSON metadata | Shows status, final URL, content type, timing, and other context around the request. |
| QA, compliance, or archives | Screenshot or PDF | Captures how the rendered public page appeared at the time of request. |
Why choose ScraperFly as the Zyte alternative?
Choose ScraperFly when the team wants a narrower, more developer-controlled buying path. You can validate public pages with free credits, keep easy targets on light request profiles, add rendering or routing controls where target evidence supports them, and send useful response formats into the systems your team already trusts.
The practical path is simple: test the target in the API Builder, compare source and rendered output with the JavaScript rendering API, choose the right output from the response formats page, and check pricing after the request profile is real. That is a calmer way to buy scraping infrastructure because the decision follows evidence, not assumptions.















