






Single page apps
Capture the route state after the app finishes rendering
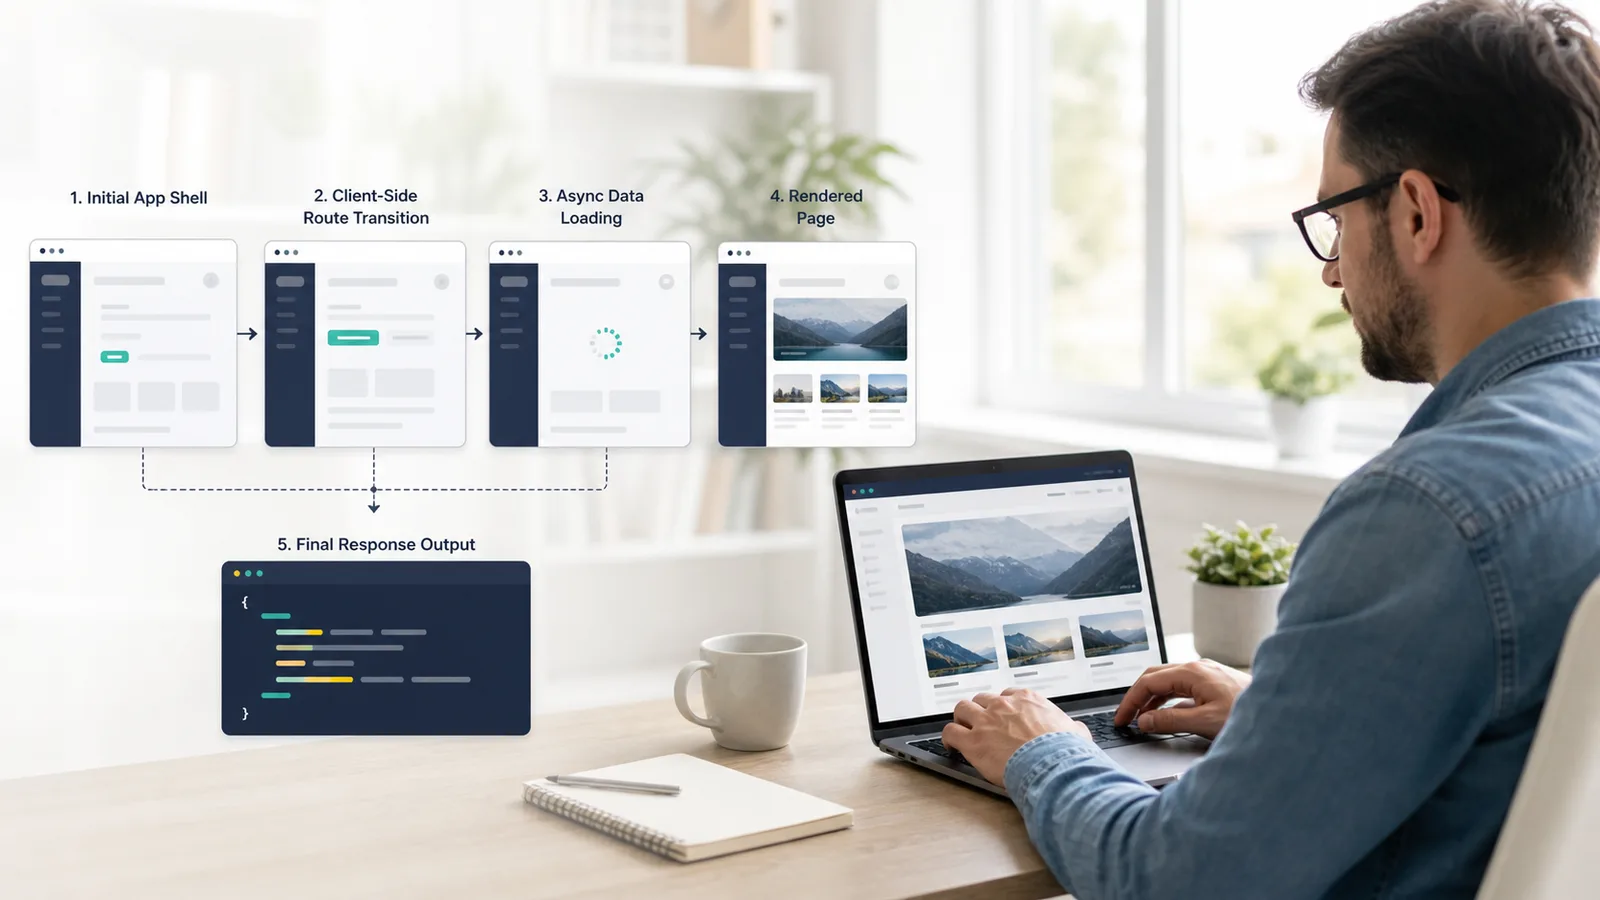
Single page apps can return a valid response while the useful page is still not there. The first HTML often contains a root element, scripts, route containers, and placeholders. The real content appears only after client-side routing, async data loading, hydration, or lazy sections finish in the browser.
ScraperFly helps teams capture public SPA routes with evidence: compare raw HTML and rendered output, wait only when timing matters, choose the response format your workflow can use, and keep full-app crawling, parsing, comparison, and storage in your own system.
What is a SPA website scraping API?
A SPA website scraping API captures public single page app routes through a hosted request layer. The API can fetch the initial HTML, execute browser JavaScript when needed, wait for the route state to settle, and return the result as rendered HTML, text, Markdown, JSON metadata, screenshot, or PDF output. Your application still owns route selection, extraction logic, validation, storage, monitoring, and business decisions.
This distinction matters because a single page app is not a normal multi-page site from a scraper's point of view. The URL may resolve, the server may return a 200 status, and the source HTML may still be too thin for the workflow. The useful content can depend on the browser executing the application and loading route data after the first response.
Practical takeaway: scrape SPA routes by proving the rendered page state, not by assuming the first HTML response contains the data.
Why are SPAs harder to scrape than static pages?
Static and server-rendered pages often put useful content directly in source HTML. SPAs frequently do not. They may load route content with JavaScript, reuse one document shell across many views, fetch data after navigation, hydrate components, lazy-load sections, or show a fallback state before the final content appears. A parser built against the initial response may miss the exact content a user sees in the browser.
SPAs also make failures easier to misread. An empty body can be a normal app shell, a timing issue, a redirect, a missing public route, a blocked asset, a region-specific response, or a real target problem. The right workflow compares evidence from source HTML, rendered HTML, screenshots, metadata, final URL, response size, and timing before retrying or escalating.
| SPA behavior | What it means | Best capture decision |
|---|---|---|
| Initial HTML is only an app shell | The route content is likely built in the browser | Test rendered output before writing parser rules. |
| Rendered DOM contains the target fields | Browser execution changes the result | Use rendering for that route class. |
| Rendered view appears late | Async data or lazy sections need more time | Add wait timing deliberately and log why. |
| Route output changes by state or region | Cookies, headers, sessions, or location may affect the public view | Add request context only where samples prove it matters. |
| Screenshot shows content but parser output is empty | The format or extraction logic may be wrong | Compare rendered HTML, text, Markdown, and metadata before retrying. |
When should ScraperFly render a SPA route?
Render a SPA route when the useful public content appears only after JavaScript runs. That is common for application shells, client-side route transitions, product grids, public dashboards, search results, filter views, lazy article sections, profile pages, and pages that fetch data after the first load. Rendering gives your workflow the page after the browser has built the state.
Rendering should be attached to a route class, not the whole site by default. Some routes may expose useful metadata or server-rendered content in source HTML. Others need rendering and waits. Others need screenshots for visual QA. Treat each representative route as evidence and keep the request profile as light as the route allows.
For framework-specific pages, compare the React and Vue guides: scrape React websites and scrape Vue websites. For broader browser capture decisions, use the JavaScript rendering API.
Which response format should a SPA workflow choose?
Rendered HTML is the right choice when a parser needs the final DOM, links, attributes, route content, tables, cards, or component output. Text and Markdown are useful when the route should feed search, classification, summaries, RAG ingestion, or content review. JSON metadata helps operations because it records status, final URL, content type, response size, and request context. Screenshots and PDFs are useful when people need visual proof of the rendered route.
The output should match the consumer. A monitoring job may need metadata plus a screenshot. A backend parser may need rendered HTML. An AI ingestion flow may prefer Markdown. A review workflow may need a PDF. Choosing this early prevents the team from building converters around the wrong response.
| SPA use case | Output to test | Why it fits | Keep in mind |
|---|---|---|---|
| Route DOM parsing | Rendered HTML | Captures the page after client-side routing and rendering | Field extraction still belongs downstream. |
| AI or content workflows | Text or Markdown | Returns readable content with less layout noise | May not preserve enough structure for selectors. |
| Debugging and logs | JSON metadata | Makes response evidence visible to jobs and monitoring | Does not replace target-specific parsing. |
| Visual QA | Screenshot | Shows whether the route rendered the expected state | Heavier than machine-readable output. |
| Archive or approval | Creates a portable record of the rendered page | Usually not the best parser input. |
How should waits, sessions, headers, and routing be used?
SPAs often need timing control, but waits should solve a real loading problem. Add wait behavior when the route renders before async content, lazy sections, or frontend data calls finish. Use sessions when related public routes depend on shared state. Use headers when legitimate request context affects the response. Use country routing when the route changes by region, language, currency, availability, or redirect behavior. Use stronger delivery only when repeated evidence shows the simple path cannot return a usable page.
The clean pattern is to test one control at a time. If a wait improves the response, keep it tied to that route class. If sessions matter, keep them scoped to related requests. If visual proof is needed, request screenshots where humans actually review the result. Avoid turning every SPA capture into the most expensive possible request.
Use sessions for state continuity, custom headers for request context, and routing controls when delivery path affects the public response.
Does ScraperFly navigate an entire SPA automatically?
No. ScraperFly captures supplied public routes and returns the response in the format you request. Your workflow should decide which routes to visit, how to discover URLs, what fields to extract, how to compare changes, where to store data, and how to handle downstream alerts or analysis. That boundary keeps the promise clear and useful.
This is usually the better architecture. The API handles page capture, rendering, waits, files, formats, and delivery controls. Your system owns the route map and product-specific meaning. If a route is incomplete, you can adjust capture. If parsing fails, you can adjust extraction. The two problems stay separate.
How can SPA scraping stay affordable?
Browser work is heavier than simple HTML capture, so cost control starts with route classification. Keep static or server-rendered routes light. Render routes that prove JavaScript changes the result. Add waits only when async content needs them. Reserve screenshots, PDFs, sessions, country routing, and stronger delivery for workflows that actually use those controls.
ScraperFly supports that path because you can start free, test representative SPA routes, buy credits for uneven projects, and move recurring workloads to monthly credits once the page mix is known. The buying decision becomes easier when the team knows which routes are light, which are rendered, and which require extra proof or routing.
Review pricing after sampling real SPA routes so the estimate reflects actual request profiles rather than blanket assumptions.
Where should a team start?
Start in the API Builder with one real public SPA route. Request source HTML first. If the content is missing, enable rendering and compare the output. Add waits only if the rendered route still captures too early. Then choose the format your workflow needs: rendered HTML for parsers, Markdown or text for readable content, JSON metadata for logs, screenshot or PDF for visual proof.
Once the request profile is proven, move it into cURL, Python, Node.js, a backend queue, monitoring job, or agent workflow. Keep that profile visible so future failures can be debugged from response evidence, not guesses.












