






Rendered HTML capture
Capture the DOM after JavaScript finishes the page
Some public pages return useful content in the first HTML response. Others send a thin shell and build the article, product list, table, route, or search result only after browser-side JavaScript runs. Rendered HTML is for that second case: when the parser needs the final DOM, not just the source markup.
ScraperFly lets teams compare raw HTML with browser-rendered HTML, then enable rendering only for targets that prove they need it. You keep simple pages fast and affordable, while still having a clean upgrade path for JavaScript-built public content.
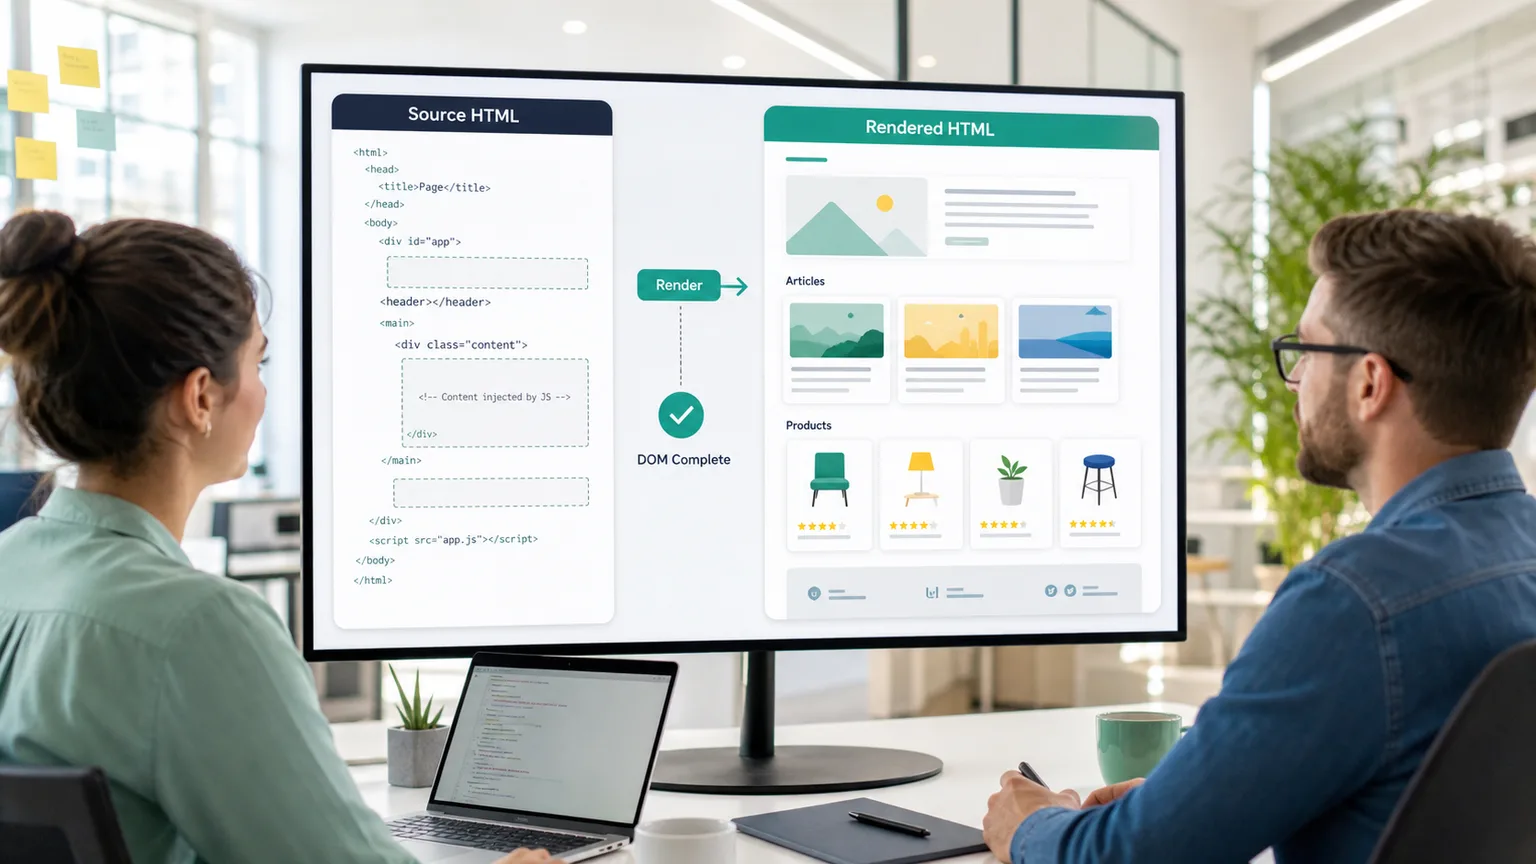
What is a rendered HTML API?
A rendered HTML API fetches a public page, runs browser-side JavaScript, waits for the page state to settle, and returns the resulting HTML markup. Instead of parsing the original source response, your application receives the DOM after the frontend has had a chance to create the useful content.
This is different from a screenshot or PDF. A screenshot proves what the page looked like. A PDF gives a portable visual record. Rendered HTML keeps the page as markup, so parsers can still inspect headings, links, tables, attributes, product cards, article bodies, pagination, embedded data, and repeated DOM patterns.
Practical takeaway: use rendered HTML when JavaScript changes the markup your parser needs, not when a simple source request already returns complete content.
When should a page use rendered HTML instead of raw HTML?
The decision should come from evidence. Start with raw HTML, inspect what comes back, and compare it with a rendered capture. If the source response already contains the useful article body, table, product data, links, or metadata, keep the request light. If the source response is missing the content, contains empty route containers, or only exposes placeholders, rendered HTML is the better input.
| Target behavior | What raw HTML shows | Better request |
|---|---|---|
| Static public page | Complete text, links, and metadata appear in the first response. | Use raw HTML, text, or Markdown without browser rendering. |
| Client-rendered page | The response contains an app shell, route container, or empty content area. | Use rendered HTML so the parser sees the completed DOM. |
| Delayed content | Important cards or tables appear only after async requests finish. | Use rendering with a measured wait rather than blind retries. |
| Layout proof needed | The parser needs markup, but reviewers also need visual evidence. | Use rendered HTML for parsing and screenshots or PDFs only for selected proof records. |
| Regional or stateful content | The visible result changes by language, location, cookies, or prior state. | Test headers, country routing, or sessions before making rendering the default. |
What can teams extract from rendered HTML?
Rendered HTML is still HTML. That makes it useful when downstream code needs selectors, attributes, structural relationships, canonical links, pagination, product cards, loaded comments, hydrated article bodies, or any page section that appears after frontend execution. It gives your parser the final markup without forcing a human to read a screenshot.
The API does not remove the need for target-specific rules. Your application still decides which fields matter, how records are validated, how duplicates are handled, and where extracted data goes. ScraperFly handles the capture side: browser execution, request options, response formats, metadata, and delivery controls.
| Parser need | Rendered HTML helps because | Useful companion output |
|---|---|---|
| Product or listing cards | The final DOM contains repeated elements the source response may not include. | JSON metadata for status and final URL. |
| Article body capture | Hydrated content can be parsed as markup after the browser runs. | Text or Markdown for readable review. |
| Search or category pages | Rendered sections expose links, filters, pagination, and visible ordering. | Screenshot for occasional QA proof. |
| Monitoring workflows | The parser can compare completed markup instead of empty shells. | Metadata and response size for change diagnostics. |
| AI or RAG ingestion | Rendered HTML can be converted into cleaner text or Markdown after dynamic content appears. | Markdown for model-ready context. |
For broader format decisions, compare the web scraping API response formats. If your workflow needs the full browser execution path, review the JavaScript rendering API page too.
How should teams test rendered HTML before production?
Pick a few representative public URLs and test them in the API Builder. Compare raw source HTML, rendered HTML, response size, final URL, content type, and wait timing. The goal is not to turn rendering on everywhere. The goal is to identify which target groups need it and which can stay on a cheaper, faster request profile.
When a rendered request is empty, do not immediately rewrite the parser. First check whether the page redirected, returned a consent or blocked state, needed a longer wait, changed by country or language, or returned a response that is too large for the intended capture. Good debugging separates capture problems from parser problems.
Practical takeaway: rendered HTML should be validated against real target pages before it becomes part of a recurring workflow.
How does rendered HTML affect cost and reliability?
Browser work is heavier than a basic fetch. That is exactly why ScraperFly treats rendering as a deliberate request control. A simple public page should not pay the same operational cost as a JavaScript-heavy page that needs browser execution, waits, screenshots, files, country routing, or premium delivery.
Use free credits to test raw and rendered results. Keep simple captures on source HTML, text, or Markdown. Add rendering only where it improves completeness. Use pay-as-you-go credits while targets and volume are still uncertain, then move predictable recurring rendered workloads to monthly credits once the pattern is proven. The pricing page and credit cost calculator help map request weight to real target behavior.
Where does rendered HTML fit in the ScraperFly workflow?
Rendered HTML sits between basic HTML capture and fully visual output. Start with the HTML scraping API when source markup is complete. Move to rendered HTML when JavaScript creates the useful DOM. Choose text or Markdown when the downstream consumer needs readable content instead of selectors. Add screenshots or PDFs when the workflow needs proof of appearance.
This lets teams keep the first request simple, make escalation evidence-based, and give parsers the markup they actually need. The result is less custom browser infrastructure, fewer blind retries, and a cleaner path from target testing to production capture.







