






Evidence-first recovery
Fix the cause before repeating the request
Scraping errors become expensive when every failure gets the same answer: retry harder. A bad URL, an invalid key, a target 403, a 429 limit, a render timeout, an empty HTML shell, and an oversized response are different problems with different fixes.
ScraperFly gives teams the request evidence they need to choose the next step deliberately. Inspect the status, final URL, response size, content type, output format, render behavior, and target signals before adding browser execution, sessions, headers, country routing, or premium delivery.
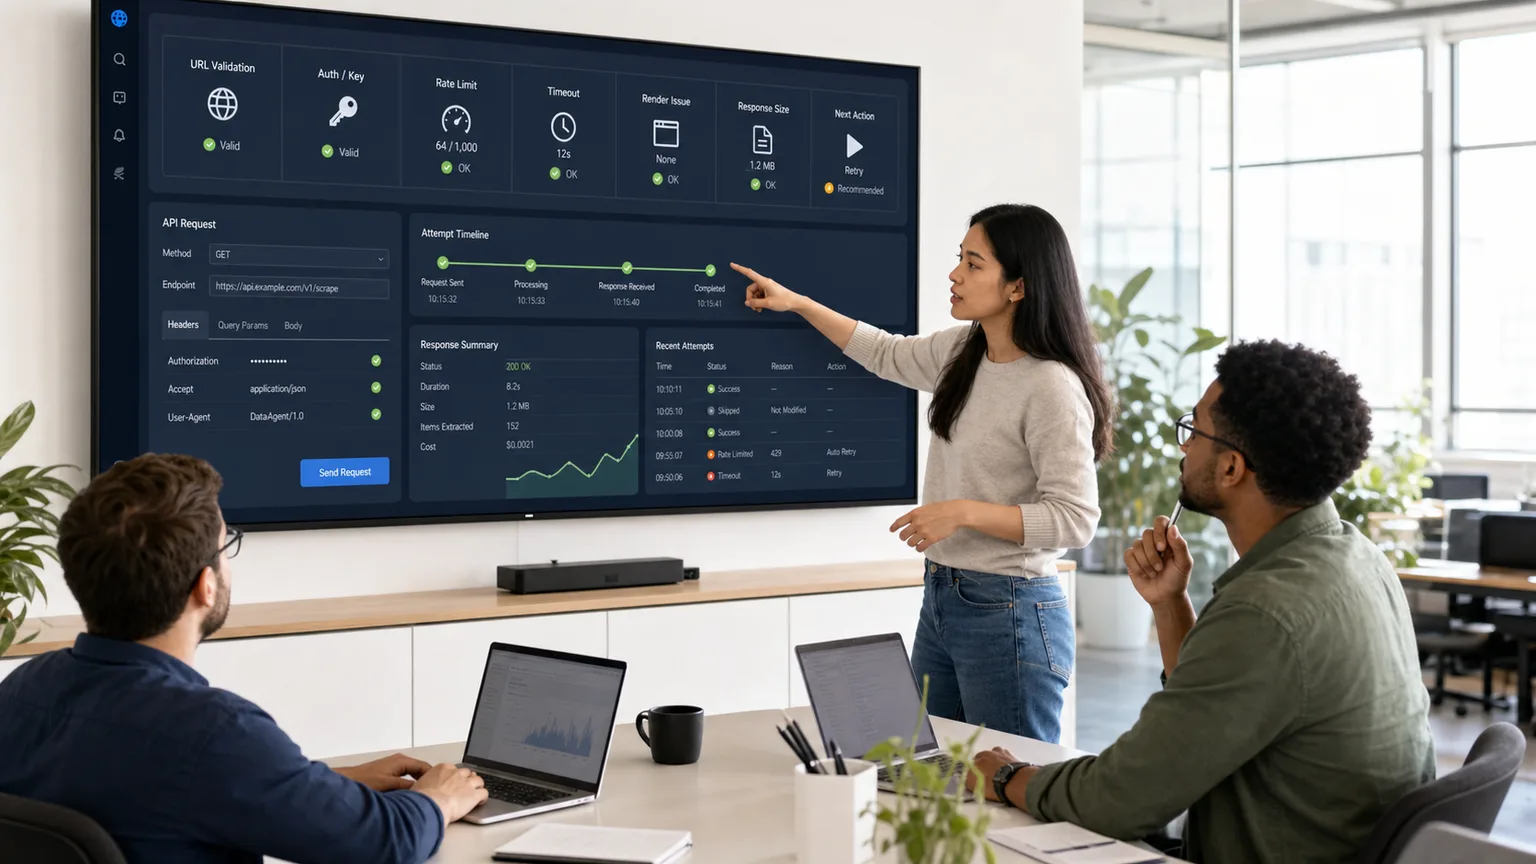
What does scraping API error handling need to answer?
Good error handling does more than say a request failed. It should answer whether the problem came from the request, the account, the target, the network path, the browser render, the selected output, or the downstream parser. That classification decides whether the next action is correction, retry, wait, escalation, or a smaller capture.
This is why a reliable scraping workflow should log both the visible error and the surrounding evidence. A 200 response with a tiny HTML body may be less useful than a clear 403. A successful screenshot of an error page is still a target failure. A PDF timeout may be an output-scope issue rather than a proxy problem.
Which scraping errors should be fixed instead of retried?
Some failures should stop the workflow immediately because another identical request cannot succeed. Missing URLs, malformed URLs, unsupported formats, invalid API keys, paused keys, incompatible file options, and impossible output combinations are configuration problems. They need validation and better feedback, not backoff.
Fix-first errors are where API discipline saves money. If the request is invalid, spending credits on rendering, premium routing, or repeated attempts only hides the real issue. Validate the request shape early, then send production batches only after the baseline request is correct.
| Error group | Common signal | Better next action |
|---|---|---|
| Input validation | Missing URL, invalid URL, unsupported parameter | Correct the request before retrying |
| Authentication | Missing, invalid, disabled, or paused API key | Fix account or key configuration |
| Output choice | Unsupported format, incompatible screenshot or PDF option | Choose a supported response format |
| Scope problem | Oversized response or file capture | Narrow the capture or use a lighter output |
Which failures deserve controlled retries?
Temporary failures can be retried, but the retry policy should be bounded. Network timeouts, transient upstream 5xx responses, and selected 429 rate limits may recover after backoff. Repeating them immediately at higher concurrency usually makes the workflow less stable.
A strong retry policy records the reason, waits before the next attempt, caps total retries, and changes the request only when the evidence supports a change. For example, a target-side 403 error may need access-context analysis, not a generic retry loop. An empty HTML response may need a raw-versus-rendered comparison before any routing change.
| Failure | Retry posture | Evidence to inspect |
|---|---|---|
| Timeout | Retry with a limit and backoff | Duration, target stability, render time, response start |
| 5xx upstream response | Retry if temporary pattern is plausible | Status history, final URL, response body size |
| 429 rate limit | Slow down before increasing pressure | Concurrency, request cadence, account limits, target tolerance |
| 403 target response | Diagnose before retrying | Headers, region, cookies, rendering, route behavior |
When should rendering, waits, or routing be escalated?
Escalation should follow proof. Enable JavaScript rendering when the useful public content is missing from source HTML and appears after browser execution. Add render waits when the browser opens the page but the content loads later. Consider headers, cookies, sessions, country targeting, or premium routing when the response evidence points to context, continuity, geography, or target-side access behavior.
The key is not to turn every target into the heaviest request. Use rendering for pages that need browser execution, review render timeout evidence when browser work fails, and inspect response-too-large cases before scaling the same profile.
How does ScraperFly make recovery decisions practical?
ScraperFly helps developers build recovery around observable request evidence: status, final URL, content type, response size, output format, render behavior, and routing profile. That makes it easier to keep simple targets light while giving harder targets a clean path to rendering, sessions, headers, country targeting, premium routing, screenshots, or PDFs when they are justified.
Use the API Builder to reproduce the target request, compare output formats, and test the next control before wiring a retry policy into code. Then use pricing and the web scraping API credit cost calculator to keep recovery experiments aligned with the real workload.







