






Empty response triage
Treat empty HTML as evidence before making the request heavier
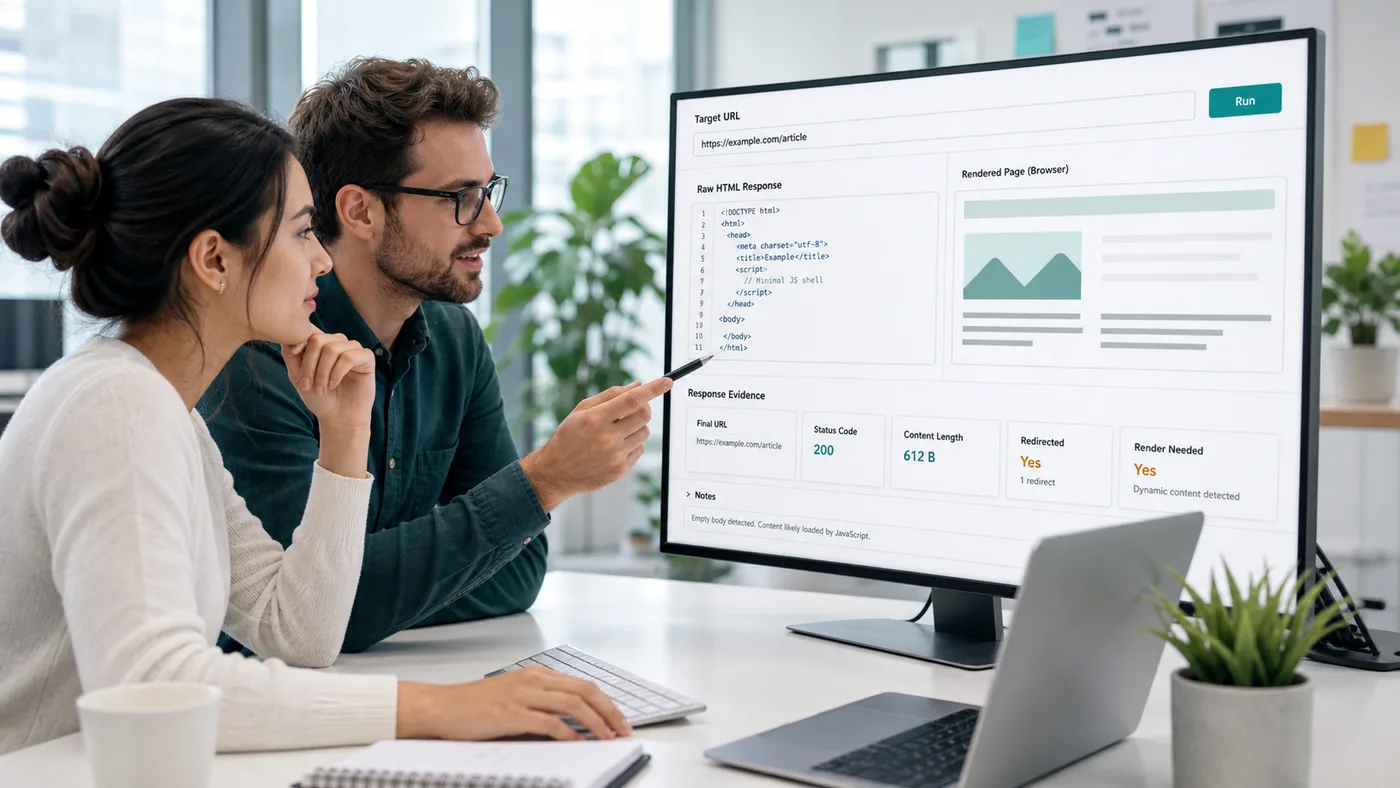
An empty HTML response is a signal, not a final diagnosis. The source body may be a thin JavaScript shell, a redirect may have landed on a placeholder, a consent or regional page may have replaced the content, or the target may have returned a soft block that looks like a successful request on the surface.
ScraperFly gives teams a practical debugging path: inspect the raw response, compare it with rendered output, check status and response size, then add rendering, waits, sessions, headers, country routing, or premium delivery only when the evidence points there.
What does an empty HTML response usually mean?
A scraping workflow can receive very little HTML for several different reasons. Some are normal: modern pages often send an app shell first and build visible content after JavaScript runs. Some are request-shape issues: the final URL changed, the page requires a cookie or accepted language, or the parser is reading the wrong response format. Some are delivery signals: the target returned a challenge page, blocked fallback, rate-limit response, or regional mismatch.
The first mistake is treating every empty body as the same failure. A good workflow separates source capture from rendered capture, network delivery from target behavior, and parser logic from request evidence. That keeps debugging fast and prevents teams from adding expensive controls before they know which control matters.
What should teams inspect before retrying?
Empty-response debugging works best when the team looks at the request evidence in a stable order. Start with the facts that are cheap to collect, then decide whether a second request should render JavaScript, wait longer, keep state, change routing, or return a visual proof.
| Evidence | What it can reveal | Next action |
|---|---|---|
| Final URL | The request may have redirected away from the expected page. | Compare the final URL with the target URL before parsing. |
| Status code | A 200 can still be a fallback, while 3xx, 4xx, and 5xx responses need separate handling. | Route retry logic by status family instead of retrying everything. |
| Response size | A tiny body often means shell markup, redirect output, or a soft block. | Store size thresholds and compare samples from the same target. |
| Raw HTML | The source may already contain useful content, hidden metadata, or only a mount point. | Use raw HTML when data is present; render only when it is missing. |
| Rendered output | Browser execution may reveal content that source HTML did not contain. | Enable rendering for targets that prove a JavaScript dependency. |
| Screenshot or PDF | Visual proof can show whether the page loaded, blocked, redirected, or displayed an empty state. | Use visual output for debugging, QA, monitoring, and escalation evidence. |
When does JavaScript rendering fix empty HTML?
JavaScript rendering is useful when the initial response contains a shell, hydration data, route container, or empty body that becomes meaningful only after browser execution. In that case, a rendered HTML request can return the DOM after the page scripts run, and text, Markdown, screenshots, or PDFs can capture the post-render state in a format that is easier to review.
Rendering should still be a targeted decision. If the source HTML already contains the needed fields, a browser session adds latency and request weight without improving the result. If content appears late, a render wait may matter more than simply turning on rendering. If the page depends on continuity, sessions or headers may be the missing piece instead of the browser itself.
For pages where the evidence points to client-side rendering, test the request in the API Builder, compare source HTML with rendered HTML, and then choose the response format that your workflow can consume. The JavaScript rendering API page goes deeper into when browser execution is worth using.
When is empty HTML a routing, access, or target signal?
Some empty responses are not rendering problems. A target can return a regional fallback, consent interstitial, login wall, challenge page, rate-limit body, or a polite placeholder with a successful HTTP status. Those cases require careful evidence before escalation, because adding every control at once makes the workflow harder to reason about.
Headers can help when the target expects a specific language, referrer, or content type. Sessions can help when one request establishes state that the next request needs to retain. Country routing can help when the public page changes by region. Premium routing can help when the standard route consistently returns access failures or blocked fallbacks. Each control should answer a visible symptom.
| Symptom | Likely direction | ScraperFly workflow |
|---|---|---|
| Thin app shell | Browser rendering or render wait | Compare raw and rendered output before changing the parser. |
| Unexpected final URL | Redirect handling or target validation | Log final URL and content type as part of the response record. |
| Soft block with 200 status | Headers, session, country, or routing review | Use screenshot proof and response size to avoid false success. |
| Repeated 429 or temporary 5xx | Backoff and concurrency control | Retry temporary failures with limits instead of increasing pressure. |
| Parser sees no fields | Format or selector review | Verify the captured response before treating extraction as broken. |
How should retries and parser logic handle empty responses?
Retries should be bounded and selective. Temporary network errors, upstream 5xx responses, and rate limits can justify backoff. Invalid URLs, unsupported output choices, missing API keys, and parser assumptions need correction, not repetition. Empty HTML sits between those categories, so the workflow should preserve enough evidence to classify it.
Parser code should not silently turn an empty capture into bad data. Store the response status, final URL, response size, content type, output format, and whether rendering was enabled. That record helps monitoring systems distinguish a target change from an infrastructure problem and gives developers a clear next request to test.
How does ScraperFly keep empty-response debugging affordable?
ScraperFly is built around a staged request path. Start with a lightweight capture, inspect the response, then add only the controls that improve that target: rendering for JavaScript-built content, wait timing for late sections, sessions for continuity, headers for legitimate context, country routing for regional pages, premium routing for harder delivery, and visual outputs when proof matters.
This keeps the buying path practical. Teams can validate the target with free credits, use pay-as-you-go credits for uneven projects, and move recurring work to monthly credits once the workflow is predictable. The response formats guide helps choose the output shape, while pricing explains how heavier request profiles affect cost.












