






Angular rendering workflow
Render Angular pages when the useful DOM appears after the app starts
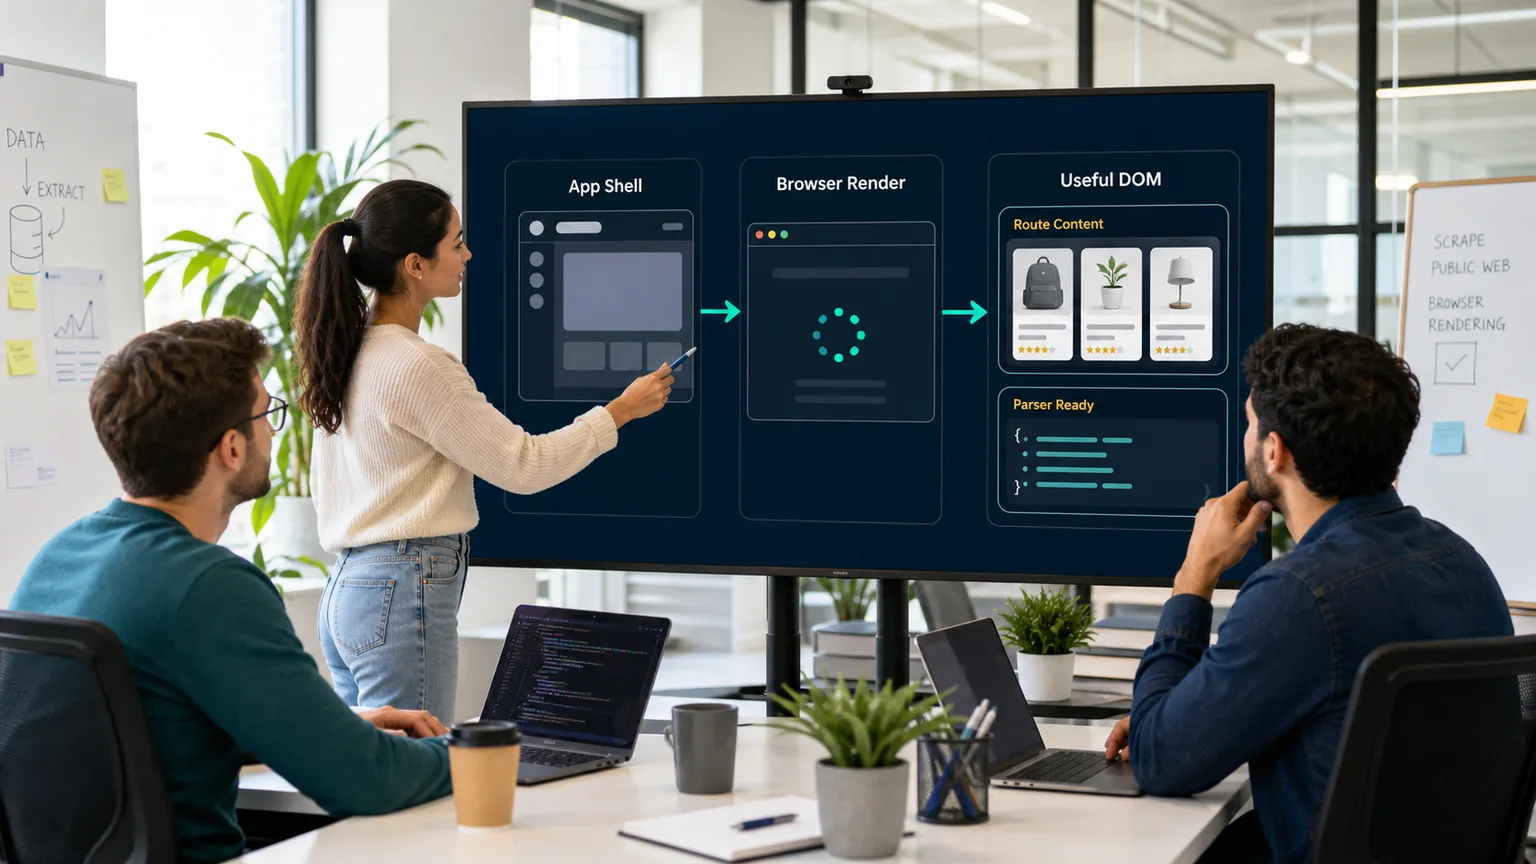
Angular websites often send a small app shell first, then build route content, listings, filters, product cards, article sections, or account-independent public data after JavaScript runs. A parser that only reads the first HTML response may see containers, placeholders, and scripts instead of the content your workflow needs.
ScraperFly gives teams a controlled way to scrape public Angular pages: inspect the raw response, render only when the target proves it needs browser execution, then return rendered HTML, text, Markdown, metadata, screenshots, or PDFs in one request path.
What makes Angular websites different to scrape?
An Angular page may not behave like a traditional document. The first response can contain the root app container, script bundles, styles, and a limited amount of server-rendered markup. The content a user sees may appear only after the Angular application boots, resolves routes, fetches public API data, renders components, and updates the DOM.
That does not mean every Angular page needs a browser. Some Angular sites use server-side rendering, pre-rendered content, embedded state, or metadata that already gives the parser what it needs. The correct workflow is to test the target, compare raw HTML with rendered HTML, and choose the lightest request that returns complete usable content.
Practical takeaway: scrape Angular pages by proving where the useful content appears, not by assuming every framework page needs the heaviest request.
When should Angular scraping use browser rendering?
Browser rendering is useful when Angular changes the captured result. That usually means the source HTML is only an app shell, route content appears after client-side navigation, important cards load after public API calls, or the page needs a short wait before the final DOM is ready. Rendering gives your parser the markup after those browser-side steps complete.
| Angular behavior | What you may see in raw HTML | Best next step |
|---|---|---|
| Client-rendered route | A root app element, scripts, and empty route containers. | Use rendered HTML and inspect the completed DOM. |
| SSR or pre-rendered content | Useful headings, links, text, cards, or embedded state already present. | Keep the request lightweight with raw HTML, text, or Markdown. |
| Delayed public API data | Placeholders or loading states without the final list or details. | Use rendering with a measured wait instead of repeated blind retries. |
| Route or filter state matters | The URL loads, but the visible page changes after the app resolves state. | Capture rendered HTML and compare final URL, status, and response size. |
| Visual proof needed | Markup alone is not enough for QA or archive review. | Use rendered HTML for parsing and screenshots or PDFs only for selected proof records. |
Which output format works best after rendering Angular?
Rendered HTML is the natural output when a parser needs selectors, attributes, links, component output, tables, cards, or repeated DOM structure. But Angular scraping does not always have to end with HTML. If the downstream system needs readable content, text or Markdown may remove layout noise and reduce cleanup. If the job is operational, JSON metadata helps explain status, redirects, content type, timing, and response size. If the job needs visual review, screenshots and PDFs can preserve what the rendered page looked like.
| Output | Use it for | Angular-specific value |
|---|---|---|
| Rendered HTML | Parsers, selectors, cards, tables, links, route content, and DOM relationships. | Captures markup after Angular builds the page. |
| Text | Search, matching, summarization, and compact content processing. | Helps when component layout creates too much markup noise. |
| Markdown | AI, RAG, analyst review, documentation, and readable content workflows. | Keeps useful headings and links after rendering without exposing every DOM detail. |
| JSON metadata | Debugging, logs, monitoring, and capture diagnostics. | Shows whether the rendered request reached the expected final state. |
| Screenshot or PDF | QA, archive, approvals, and visual proof. | Confirms what the Angular page displayed at capture time. |
For the broader output trade-offs, compare the web scraping API response formats. For framework-neutral rendering guidance, use the JavaScript rendering API page.
How should teams test an Angular scraping request?
Use representative public URLs, not only the homepage. Test a listing page, detail page, filtered route, pagination state, and any public page type that feeds the real workflow. In the API Builder, compare raw HTML, rendered HTML, text, Markdown, response size, final URL, status, and content type. This shows which routes need browser execution and which can stay simple.
When content is missing, inspect the capture before changing parser logic. The page may need a render wait, different public route URL, accepted language context, country routing, session continuity, or simply a smaller scope. Treat those as request-profile questions first, then update extraction rules once the page response is proven.
Practical takeaway: an Angular scraping setup should be tested per route type, because one app can mix static, server-rendered, delayed, and fully client-rendered pages.
How does ScraperFly keep Angular scraping practical?
Angular scraping can become expensive when every request is treated as a full browser job with extra waits, visual files, and stronger routing. ScraperFly supports a more disciplined path. Start with the source response, enable rendering only where it improves completeness, then choose the smallest output format your downstream workflow can use.
This keeps simple Angular pages affordable while still giving harder routes a clean upgrade path. Use pay-as-you-go credits while target behavior and volume are still being proven, then move predictable recurring work to monthly credits when the pattern is clear. The pricing page and credit cost calculator help map request weight to real capture choices.
Where does Angular scraping fit with other framework pages?
The same evidence-first logic applies across modern frontend frameworks, but the details differ by routing, rendering strategy, hydration, and data loading behavior. If the project includes multiple frontend targets, compare Angular with the React scraping API, Vue scraping API, and SPA scraping API guides.
ScraperFly keeps the capture layer consistent across those targets. Your application can test each public page, choose the needed controls, and keep framework-specific parsing logic outside the request infrastructure.







