






Clean text output
Extract readable page text without carrying markup noise downstream
Many scraping workflows do not need the full DOM. They need the readable parts of a public page: article copy, product descriptions, policy text, listing details, support content, or update notes that can move into search, QA, monitoring, summaries, or lightweight AI classification.
ScraperFly helps teams fetch the public page, render it when JavaScript creates the useful content, and return clean text as a practical output format. That keeps simple content workflows smaller while preserving the option to request HTML, Markdown, JSON metadata, screenshots, or PDFs when the job needs more structure or proof.
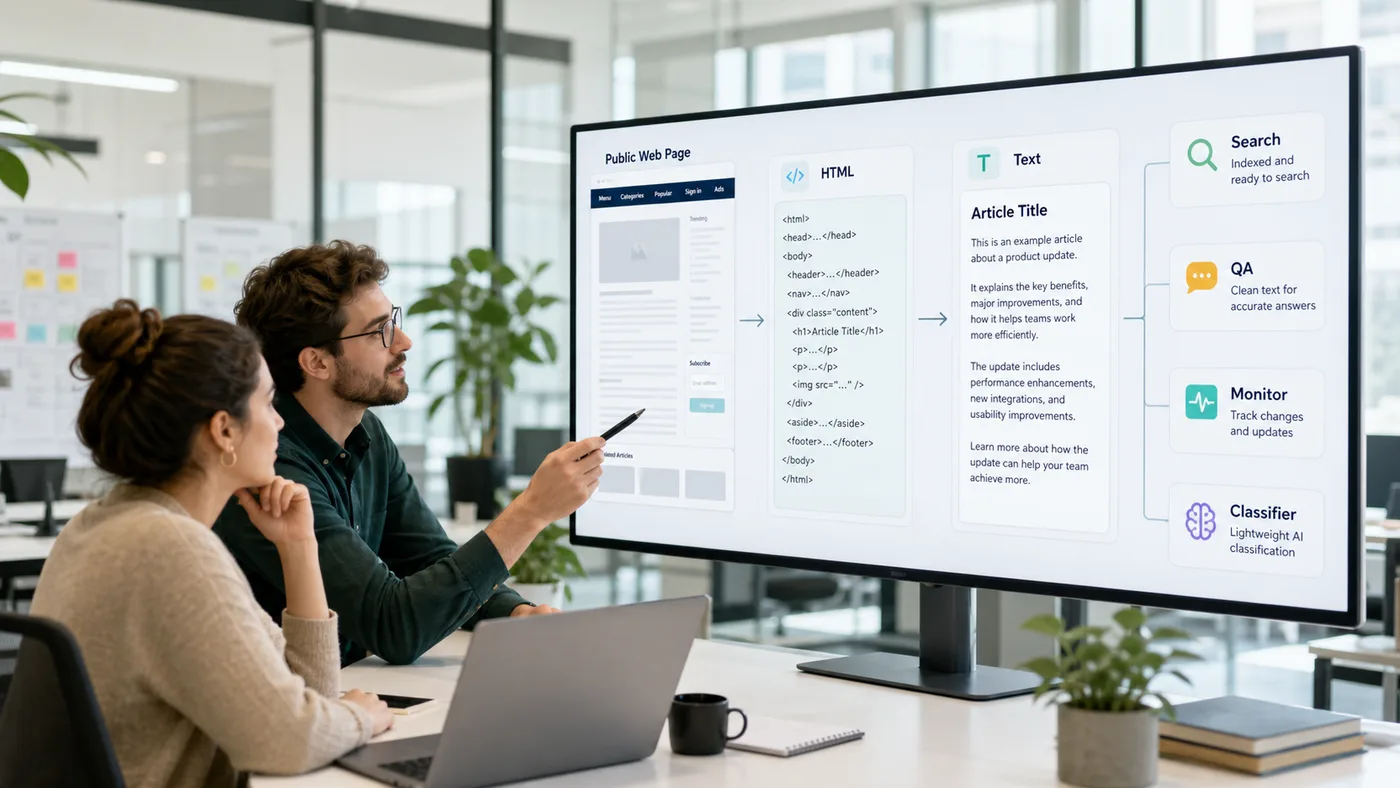
What is an HTML to text parser API?
An HTML to text parser API fetches a public web page and returns readable plain text instead of raw markup. The goal is not to preserve every DOM relationship. The goal is to remove layout code, repeated navigation, scripts, attributes, and visual scaffolding so the content can be inspected, indexed, compared, summarized, or routed into downstream systems.
The capture layer still decides whether the text is useful. If the target sends meaningful content in source HTML, text output can stay lightweight. If important content appears only after browser-side JavaScript runs, the request may need rendering before text conversion. ScraperFly keeps both paths available through one API surface.
When is text better than HTML or Markdown?
Text is the simplest useful format when a workflow cares about words more than structure. It is a good fit for search indexing, change monitoring, QA review, classification, duplicate detection, summaries, and lightweight AI preprocessing. It gives the application compact content that is easier to store and compare than raw HTML.
Text is not ideal when the workflow needs headings, links, citations, lists, table context, or DOM-specific extraction. In those cases, Markdown or HTML may carry more useful structure. The best production setup chooses the response format from the downstream consumer instead of treating every page as a generic scrape.
| Format | Best suited to | Main advantage | When to choose another output |
|---|---|---|---|
| Text | Search, monitoring, QA, summaries, classification, compact analysis. | Small, readable, and easy to compare. | When headings, links, or DOM relationships matter. |
| Markdown | RAG, documentation, editorial review, AI intake with readable structure. | Preserves more content shape than plain text. | When the workflow only needs compact prose. |
| HTML | Selectors, attributes, tables, links, source inspection, structured parsing. | Keeps page markup available for custom extraction rules. | When raw markup creates unnecessary cleanup work. |
| JSON metadata | Diagnostics, logging, response evidence, request QA. | Explains status, final URL, content type, and capture context. | When the application needs the actual readable body. |
How does JavaScript rendering affect text extraction?
Text conversion can only clean the content that the request captures. If the source HTML already contains the useful text, rendering adds weight without improving the output. If the page sends an app shell and fills the visible content after hydration, rendered capture can make the final text complete.
A disciplined workflow tests both states on real targets. Start with source capture, inspect the text, then enable rendering when important copy is missing. If the content arrives late, a wait setting may matter. If the page changes by language, cookie, or region, headers, sessions, or country routing may affect the captured text more than rendering itself.
For pages that require browser execution, the JavaScript rendering API explains the rendering decision. For comparing text against HTML, Markdown, JSON, screenshots, and PDFs, use the response formats guide.
What should teams validate before scaling text extraction?
Clean text is easy to consume, which makes bad text easy to miss. Before batching a large URL set, validate that the main content is present, repeated navigation is reduced, the language is correct, redirects did not change the page, and important disclaimers or price details did not disappear during cleanup.
Validation is especially important for monitoring and AI workflows. A classifier, search index, or summarizer may happily process incomplete text unless the capture record explains what happened. Store final URL, status, content type, response size, render setting, and output format with each result so the team can separate target changes from extraction mistakes.
| Check | Why it matters | Useful signal |
|---|---|---|
| Main body present | Search, summaries, and monitoring need the actual content, not only layout text. | Compare text output against source or rendered samples. |
| Noise level | Navigation and repeated boilerplate can distort classifiers and summaries. | Review repeated phrases across multiple URLs. |
| Language and region | Targets can vary copy by country, language, currency, or consent state. | Log headers, country routing, final URL, and visible content samples. |
| Response size | Tiny text output can reveal redirects, soft blocks, or empty rendered states. | Set expected size bands for each target type. |
| Format fit | Some workflows need links, tables, or citation structure. | Switch to Markdown or HTML when plain text removes too much context. |
Where does text output fit in production workflows?
Text output is useful when the scraping result feeds a system that reads, compares, or classifies content rather than extracting precise DOM fields. A monitoring job can compare text snapshots. A search pipeline can index readable copy. A QA process can inspect whether a public page changed. A lightweight AI workflow can classify or summarize content without carrying markup into the prompt.
ScraperFly keeps that workflow practical because text output is one option in the same request model. Teams can test the target in the API Builder, choose text output, add rendering only when needed, and keep HTML or screenshots available for debugging when text alone cannot explain the result.
How does text conversion stay affordable?
HTML-to-text conversion can stay light when the source response already contains the content. Cost increases when a workflow adds browser rendering, wait timing, sessions, country routing, premium delivery, screenshots, PDFs, or repeated retries. The efficient pattern is to start simple, inspect the output, and add controls only when they improve the captured text.
This makes text output a good fit for uneven projects and recurring systems. Teams can validate a few targets with free credits, use pay-as-you-go credits for occasional cleanup work, and move predictable extraction or monitoring jobs to monthly credits when the request profile is proven. The pricing page explains how that path scales without forcing every experiment into a subscription.







