






Link evidence first
Capture the public page state before your link parser decides what to follow
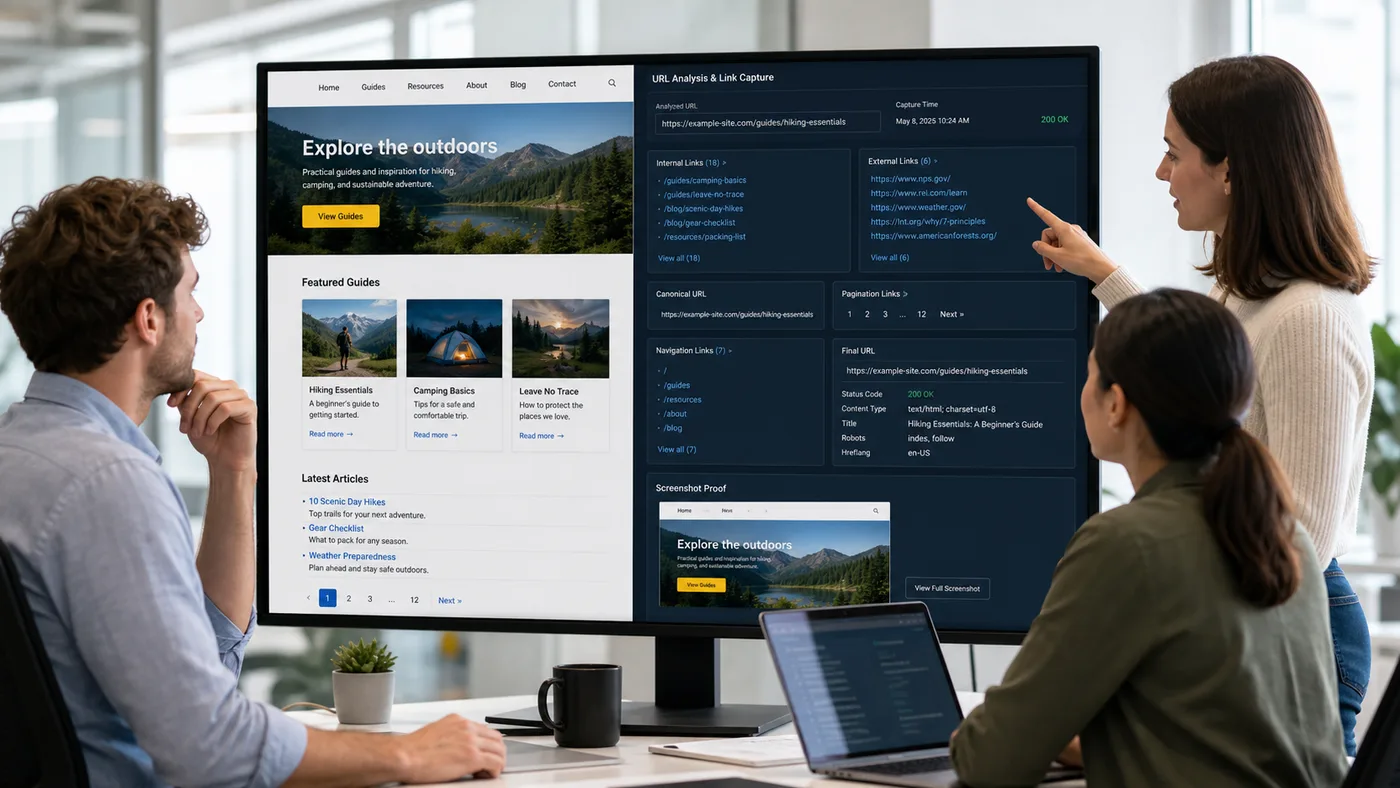
Link parsing sounds simple until the target page changes the evidence. Navigation can be server-rendered or browser-built, canonical URLs can differ from the requested URL, pagination may hide behind JavaScript, and public pages can mix internal links, external references, media links, hreflang, robots hints, and redirects in one response.
ScraperFly gives teams a reliable capture layer for that page evidence. Fetch public pages as raw or rendered HTML, keep response metadata, preserve visual proof when QA needs it, and let your own parser decide which links to extract, normalize, crawl, score, or ignore.
What is a webpage link parser API?
A webpage link parser API is a workflow that captures a public page and returns enough source evidence for downstream code to inspect links. That can include raw HTML, rendered HTML, final URL metadata, status, content type, response size, screenshots, PDFs, and other context that helps a parser decide what is present on the page.
The parser itself remains your product logic. ScraperFly does not replace crawl scheduling, link scoring, SEO auditing, URL normalization, deduplication, sitemap decisions, or business rules. It gives the parser a cleaner input layer so those decisions are based on what the public page actually returned.
This intent is narrower than a general web content parser API. The focus is link evidence: anchors, navigation, canonicals, pagination, hreflang, external references, and final URL behavior that can affect discovery, QA, monitoring, or internal tools.
Which links and URL signals should teams inspect?
A useful link parser should not treat every href as equally meaningful. Navigation links, pagination, canonical URLs, hreflang alternates, internal content links, outbound references, media links, script-created links, and redirected final URLs all carry different signals. Capturing them from the right page state matters.
Before scaling, define which link classes your workflow needs. An SEO QA tool may care about canonicals, hreflang, redirects, and crawlable navigation. A content discovery pipeline may care about article links and pagination. A monitoring workflow may care about whether a key public link disappeared from a rendered page.
| Signal | Why it matters | Best capture evidence | Downstream decision |
|---|---|---|---|
| Internal links | Reveal navigation, discovery paths, related content, and site structure | HTML or rendered HTML | Extract, normalize, deduplicate, or queue |
| External links | Show references, citations, partners, embeds, and outbound dependencies | HTML plus final URL metadata | Classify, verify, or monitor |
| Canonical URL | May differ from the requested URL and affect duplicate handling | HTML head and response metadata | Normalize records and avoid duplicate pages |
| Pagination links | Control whether a workflow can discover the next result pages | HTML, rendered HTML, screenshot proof | Build crawl scope carefully |
| Hreflang and regional links | Expose language or regional alternates | HTML head, final URL, country-aware samples | Map locale coverage or regional variants |
| Redirect and final URL | Shows the real destination after target behavior is applied | JSON metadata and status evidence | Debug routing, canonicalization, and link quality |
The strongest link workflows store both the link list and the capture context. When a parser produces an unexpected result, status, final URL, content type, response size, source HTML, and rendered state help explain whether the issue is in the page, the request profile, or the extraction rule.
When should link parsing use rendered HTML?
Many public pages still expose useful links in source HTML. In those cases, raw HTML is the fastest and most practical capture format. But some sites build navigation, product grids, infinite scroll, related links, or pagination after browser-side JavaScript runs. A parser that only sees source HTML may miss those links or mistake placeholders for real page evidence.
Use JavaScript rendering when the useful link set appears only in the browser-built page state. Compare raw and rendered responses before committing to a heavier request profile. If rendering does not change the links your parser needs, keep the request light.
Visual output can also help. Screenshots or PDFs are not the best source for machine extraction, but they are useful when QA needs to prove that a navigation area, pagination control, link module, or page state appeared at the time of capture.
How does ScraperFly support SEO QA and crawl planning?
ScraperFly can support SEO QA by capturing the public source pages that downstream tools inspect. The API can provide HTML for link extraction, metadata for status and final URL checks, rendered output for JavaScript-built navigation, and screenshots for review. Your own workflow still owns crawl rules, scoring, reporting, issue prioritization, and remediation logic.
This boundary keeps the page honest and useful. A link parser can use ScraperFly to collect reliable samples, then classify links by type, depth, destination, template, language, or source section. A monitoring workflow can compare whether important links remain present. A QA tool can preserve screenshot proof when a public page changes.
Use the API Builder to test a representative URL, compare raw and rendered HTML, inspect metadata, and decide whether the link parser needs simple HTML, rendering, headers, sessions, country routing, or visual files before scaling the target.
How can link parsing stay predictable and affordable?
Link extraction can become expensive when every page is treated like a complex rendered application. Most teams should start with simple HTML capture, prove what links are present, then add heavier controls only when the response evidence shows they improve the link set or debug value.
| Decision | Good default | Escalate when |
|---|---|---|
| Capture format | Raw HTML for anchor extraction | Rendered HTML changes navigation, pagination, or link modules |
| Metadata | Keep status, final URL, content type, and size | Debug redirects, canonicals, or inconsistent samples |
| Visual proof | Skip for machine-only link extraction | QA needs evidence that a link area appeared visually |
| Routing controls | Use the standard path first | Location, language, access, or redirects change public page links |
| Cost model | Use free credits and pay-as-you-go while testing | Move recurring link monitoring to monthly credits when volume is known |
ScraperFly's flexible billing model is useful here because link parsing often starts as an exploratory project. Test a few templates, keep simple pages light, add rendering or visual proof only where it matters, and use the Pricing page to estimate request weight before recurring monitoring begins.










