






ScraperFlyAI-ready Web Data API

rendering

Scrape Next.js websites with the right capture mode

Next.js pages can be server-rendered, statically generated, incrementally rebuilt, hydrated, or client-side. ScraperFly helps developers inspect public Next.js pages first, keep complete source HTML lightweight, and enable browser rendering only when JavaScript changes the content the workflow needs.

Next.js capture workflow

Choose raw HTML or rendered capture based on how the route is built

Next.js can serve a complete page before the browser runs, or it can send a light shell that becomes useful only after hydration and client-side data loading. ScraperFly gives teams a practical way to tell the difference before parser logic, retries, and browser capacity become part of the production workflow.

Start with the public source response, inspect whether the target content is already there, then compare rendered output when the page proves it needs JavaScript execution. That keeps static and server-rendered routes fast while still supporting client-built pages that need a browser to become complete.
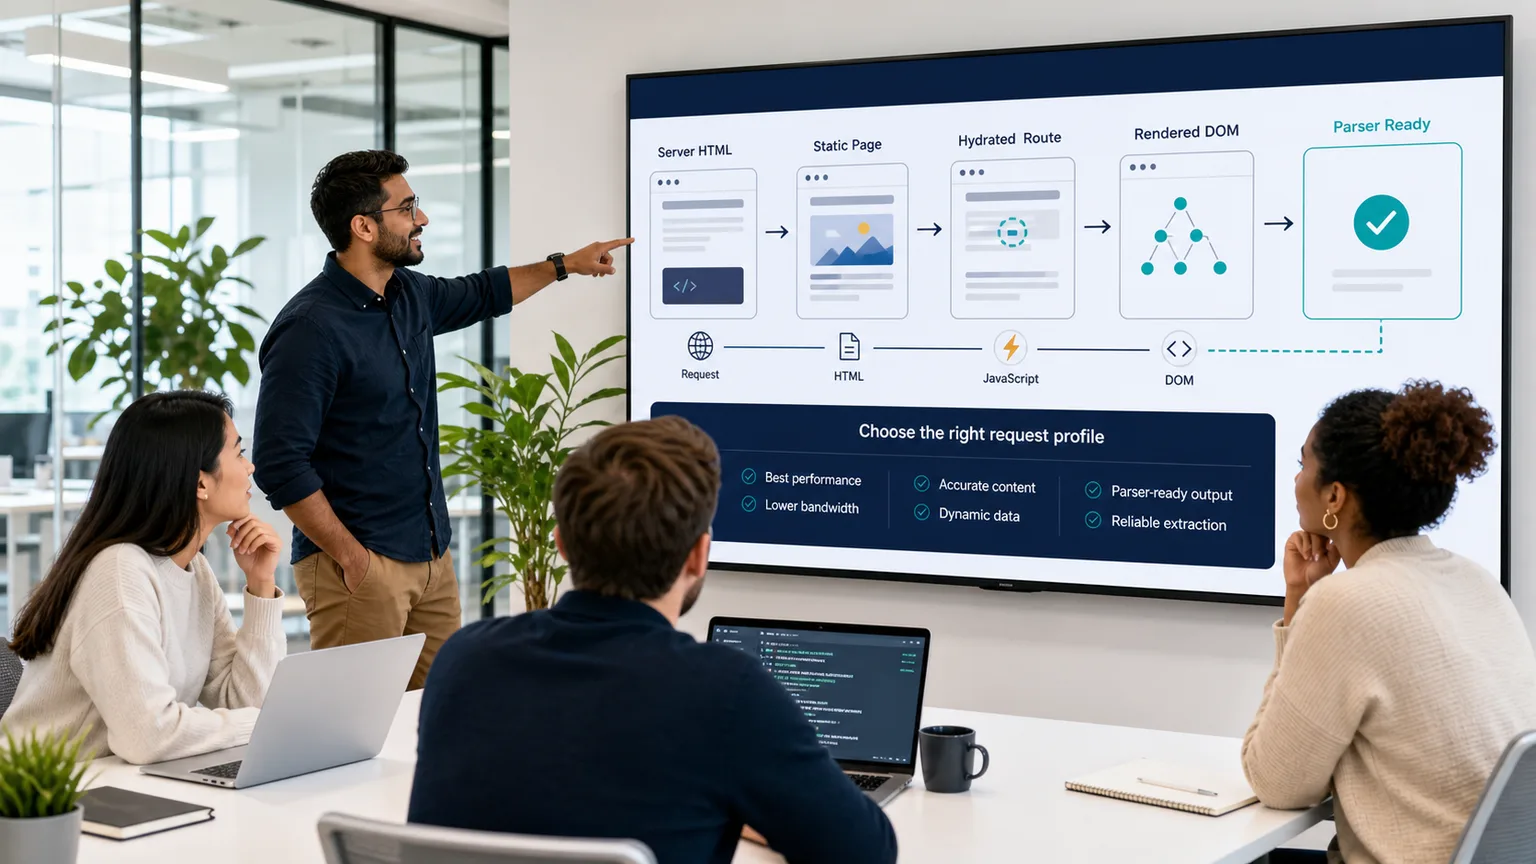
server HTMLhydrated routesrender when needed
Team comparing source HTML, static output, hydrated routes, and rendered DOM for a Next.js scraping workflow

Why do Next.js pages need a capture decision first?

Next.js is not one rendering pattern. A public route may be server-rendered for every request, statically generated at build time, updated through incremental regeneration, or assembled in the browser from client components and data calls. Two pages on the same site can behave differently, so a single default scraping profile often wastes time or misses content.

The useful question is not whether the site uses Next.js. The useful question is where the data appears. If the source response already contains product cards, article text, prices, links, metadata, pagination, or listings, a lightweight HTML request is often enough. If the first response contains a route shell, placeholders, scripts, or partial state, rendered capture may be the cleanest way to collect the page your users actually see.

Practical takeaway: treat Next.js scraping as a response inspection problem first, then choose the smallest request profile that returns the needed content.

When is source HTML enough for a Next.js scrape?

Source HTML is enough when the initial response includes the fields your application will parse. That is common on server-rendered pages, static marketing pages, documentation pages, article routes, category pages, and public listings where content is placed into the HTML for speed, SEO, or reliability. In those cases, adding a browser can make the request slower and heavier without improving the result.

A source-first workflow also makes debugging easier. Your team can inspect the final URL, status, content type, response size, and markup before adding waits or browser execution. If the required selectors, links, headings, tables, or embedded metadata are already present, keep the route on raw HTML and reserve heavier controls for the targets that prove they need them.

Next.js route signal What it usually means Best ScraperFly profile
Useful content appears in source HTML The page is likely server-rendered or static enough for direct parsing Use raw HTML and keep the request lightweight.
Source HTML has a shell, scripts, or placeholders The visible content may be created after hydration Compare rendered HTML before building parser logic.
Rendered output contains the missing fields Browser execution changes the scrape result Use rendering for this route pattern and log why it is needed.
Content changes by locale, cookie, or previous state The route may depend on request context Add headers, cookies, or sessions only where that context matters.
Rendered output is still empty or blocked The issue may be routing, timing, access rules, or target behavior Inspect evidence before retrying or escalating delivery.

When should Next.js scraping use browser rendering?

Use rendering when the useful public content appears only after browser-side code runs. That can happen on hydrated application routes, interactive product grids, search results, infinite lists, review widgets, dynamic pricing blocks, maps, dashboards with public data, or pages where the initial HTML mostly points the browser toward JavaScript bundles.

Rendering should be a targeted control, not a reflex. Compare the source response with the rendered state and look for a real content difference. If rendering adds the missing fields, it is worth using for that route class. If rendering does not improve the output, the next step is not blind retries; inspect timing, redirects, status, resource behavior, response size, and whether the public page actually exposes the data.

For deeper browser decisions, compare this page with the JavaScript rendering API, the headless browser scraping API, and the rendered HTML API guides.

Which output format should a Next.js workflow request?

The right format depends on what the downstream system will do with the page. HTML is best when selectors, DOM relationships, links, attributes, tables, or embedded state matter. Text and Markdown are better when the output feeds search, summaries, classification, content review, or AI pipelines. JSON metadata helps with diagnostics because it preserves request evidence such as status, final URL, response size, and content type. Screenshots and PDFs are useful when a human needs visual proof of what the rendered page showed.

Output format Use it for Next.js advantage
Raw HTML Server-rendered or static routes Fast, parser-friendly, and usually the lowest-weight capture.
Rendered HTML Hydrated routes and browser-built content Captures the DOM after JavaScript changes the page.
Text Search, monitoring, lightweight analysis Removes layout noise when structure is not required.
Markdown AI, RAG, documentation, content review Keeps readable headings, links, and sections for language-model workflows.
JSON metadata Logging and routing decisions Makes request outcomes easier to compare across route samples.
Screenshot or PDF QA, compliance review, visual monitoring, archives Shows what the public page looked like after capture.

How should teams test Next.js routes before production?

Test a small set of representative routes first. Include a static route, a server-rendered route, a dynamic route, and a route that appears client-heavy. Send each target through the API Builder, compare source HTML with rendered output, and choose the smallest format that your parser or application can use directly.

That test set becomes your request playbook. Simple routes can stay on raw HTML. Client-built routes can use rendered HTML or a cleaner text and Markdown output. Routes that need continuity can add sessions. Routes that depend on language, region, or routing context can add headers, cookies, country targeting, or stronger delivery only when the evidence supports it.

Practical takeaway: build the Next.js scraping profile from route evidence, not from a site-wide assumption about the framework.

How does ScraperFly keep Next.js scraping affordable?

Cost control starts by avoiding unnecessary browser work. A page that returns complete server-rendered HTML should not carry the same request weight as a hydrated route with waits, visual output, session context, and stronger routing. ScraperFly makes that decision easier because the same API path can start light and add controls only when the target proves they change the result.

Use pricing as an engineering feedback loop. Classify route patterns, keep raw HTML as the default for complete responses, reserve rendering for client-side content, and generate screenshots or PDFs only when visual proof is part of the workflow. The pricing page and web scraping API credit cost calculator help teams estimate how those choices affect volume before they scale.

How does Next.js scraping compare with React and SPA scraping?

Next.js often sits between classic HTML scraping and full SPA scraping. It can behave like a server-rendered site, a static site, a hydrated React app, or a client-heavy single-page application depending on the route. That makes it important to test the actual public URL rather than treating every Next.js page as a browser-only target.

If the site behaves like a React application, the React scraping API guide is a useful comparison. If navigation and content depend heavily on browser-side routing, review the SPA scraping API workflow. If the target gives you complete source markup, keep the capture path closer to the HTML scraping API approach and save the browser for pages that truly need it.


Next.js target check

Prove where the Next.js content appears before choosing a browser

Next.js routes can return complete server HTML, static content, hydrated shells, or browser-built views. ScraperFly helps teams inspect the real public response first, then choose raw HTML, rendered capture, sessions, headers, routing, or visual output only when those controls make the result better.

Raw HTML response mapped to visible page data
01

Raw HTML availability

Check whether the fields you need are already present in the first HTML response.

Best first test for simple pages, articles, docs, listings, and product details.

Before and after JavaScript rendering comparison
02

JavaScript dependency

Compare raw HTML with the rendered DOM or screenshot before turning on browser rendering.

Use rendering when raw HTML is only a shell and scripts create the useful content.

Cookies, consent, session and access context for scraping
03

State & access context

Identify whether cookies, consent, login boundaries, pagination, or the same visitor state affect the response.

Use sessions and headers when continuity changes the data you receive.

Regional content variations across countries and routes
04

Geo/content variation

Test whether country, language, currency, inventory, SERP, ads, or route reputation changes the result.

Use geo or premium routing only when the target proves the response varies by route.

Checks that keep Next.js scraping precise

Where is the target field?

Find whether the field exists in raw HTML, rendered DOM, an API call, structured data, a file, or a later interaction state.

What changes the response?

Sample a few URLs and compare status, final URL, content length, redirects, empty states, and visible result differences.

What context is required?

Mark any dependency on consent, locale, cookies, headers, authentication boundary, pagination, filters, or previous requests.

What does failure look like?

Define the signals for blocked, partial, stale, redirected, empty, timed-out, or region-mismatched responses before scaling.

Map the route before scaling requests

Fetch mode

Raw HTML availability decides whether the first request can stay simple or needs rendering, waits, screenshots, or extraction.

Request context

State requirements decide whether to add headers, cookies, sessions, consent handling, or a stable visitor profile.

Routing choice

Geo and reputation findings decide whether standard routing is enough or a country/premium route is justified.

Validation rules

Known failure states become checks for retries, escalation, QA review, and deciding when a lighter profile is still complete.

Next.js request builder

Build a Next.js scraping request that starts light and renders only when evidence calls for it

Use the API Builder to compare source HTML with rendered output, choose the response format your parser can use immediately, and copy a canonical ScraperFly request into your app once the route behavior is clear.

01
01

Capture raw HTML when the route already contains the data

Keep static and server-rendered pages light instead of paying browser cost for content that is already present.

02
02

Use browser execution for hydrated or client-loaded routes

Return rendered HTML, text, Markdown, screenshots, or PDFs when JavaScript changes the public page state.

03
03

Preserve diagnostics for route decisions

Compare status, final URL, content type, response size, and visual proof before moving a route into production volume.

Next.js request controls

url

The public Next.js route to capture.

render

Run a browser when hydration or client-side data changes the response.

format

Return HTML, text, Markdown, JSON metadata, screenshot, or PDF.

wait

Give client-side route data time to settle when rendering is enabled.

keep_headers

Preserve allowed headers when locale, content type, or public request context matters.

session

Reuse context only for related routes that depend on shared state.

cURL example

Generate Markdown with the same request shape you can move into production

curl "https://scraperfly.com/api/v1?url=https%3A%2F%2Fexample.com&format=markdown" \
  -H "apikey: YOUR_API_KEY"

Next.js cost control

Keep browser work for the Next.js routes that prove they need it

ScraperFly lets teams separate complete HTML routes from hydrated routes before scale. Use low-weight source capture where the page is already complete, then add rendering, waits, sessions, visual files, or stronger routing only for route patterns where those controls change the output.

A lightweight HTML request returning a simple response
01

Basic fetch

Use a basic fetch when public HTML already contains the fields you need.

Lightest request profile; keep it when the response is complete.

JavaScript rendering producing a complete DOM
02

Rendering

Use rendering when raw HTML is a shell and JavaScript completes the page.

Heavier profile; use it only when browser output changes the result.

Several requests preserving cookies and visitor state
03

Stateful session

Use sessions when cookies, consent, locale, or pagination change the response.

Heavier state profile; preserve it only when continuity matters.

Request routing through geo and higher quality routes
04

Premium routing & geo

Use premium routing or geo only when origin, country, reputation, or regional content changes the result.

Heaviest routing profile; apply it only to targets that prove they need it.

What changes request weight

More infrastructure work

Browser rendering, routing choices, and longer waits mean the platform has to do more than return a simple response.

More target uncertainty

Redirects, empty states, rate limits, and challenge pages often require stronger delivery options or retries.

More state to preserve

Cookies, sessions, consent, and multi-page flows add moving parts that a plain stateless fetch does not have.

More evidence to return

Screenshots, PDFs, rendered output, and richer response artifacts are useful, but they are heavier than plain HTML.

How to keep volume predictable

Sample before scale

Test a small URL set first and group targets by the lightest profile that returns complete data.

Do not render by default

Inspect raw HTML before turning on rendering. Many public pages already contain the data you need.

Escalate by evidence

Move up only when the response shows missing content, state dependency, geo variance, or routing problems.

Measure useful results

Optimize around valid records delivered, not raw request volume. A lighter profile is best only when it stays complete.

Next.js questions

Common questions about scraping Next.js websites

Quick answers for teams evaluating web scraping API behavior: request formats, JavaScript rendering, proxy routing, credits, files, security, and billing.

Quick answers

Raw HTML vs browser capture

Decide based on the response, not the framework name.

Should every Next.js page use rendering?

No. Start with source HTML and render only when JavaScript adds the content your workflow needs.

What proves rendering is needed?

A meaningful difference between source HTML and rendered output: missing fields, lazy sections, client-loaded data, or a route shell that becomes useful after execution.

Formats for Next.js routes

Choose the response shape around the downstream workflow.

Is rendered HTML always the best output?

Rendered HTML is best for DOM parsing. Text, Markdown, metadata, screenshots, and PDFs can be better for search, AI, diagnostics, or visual review.

When should I use Markdown?

Use Markdown when readable headings, sections, and links matter more than exact DOM relationships.

Headers, sessions, and routing

Add request context only when the route behavior depends on it.

Do Next.js pages need sessions?

Only when public content depends on shared cookies, preferences, consent state, or a previous request.

When does country routing matter?

Use country routing when a public page changes by location, currency, language, availability, or regional redirects.

Testing before production

Classify route patterns before increasing volume.

What should I test first?

Test representative static, server-rendered, hydrated, and client-heavy routes, then assign each route class the smallest request profile that works.

How do I keep costs predictable?

Keep complete HTML routes lightweight and reserve rendering, waits, visual output, and stronger routing for the routes that prove they need those controls.





