






ScraperFlyAI-ready Web Data API

use cases

News Monitoring Scraping API for public web intelligence

Monitor public news sources, publisher pages, article URLs, press rooms, blogs, and mention pages with a request workflow that captures source evidence before alerts fire. ScraperFly helps teams fetch public pages, render JavaScript only when the site needs it, and return the response format that monitoring, research, PR, risk, or AI pipelines can use.

News intelligence workflow

Capture public news evidence before alerts become noise

News monitoring is only useful when the source record is clear. A headline, mention, or article change should come with enough evidence to understand where it appeared, when it was captured, whether the page redirected, and which format your team can review or process next.

ScraperFly gives monitoring teams a practical request layer for public news pages, publisher pages, press rooms, article archives, blogs, and search-style result pages. Start with the lightest capture, inspect the response, then add rendering, sessions, headers, country targeting, or stronger routing only when the source proves those controls improve the result.
public pagesfreshness checksarticle evidence
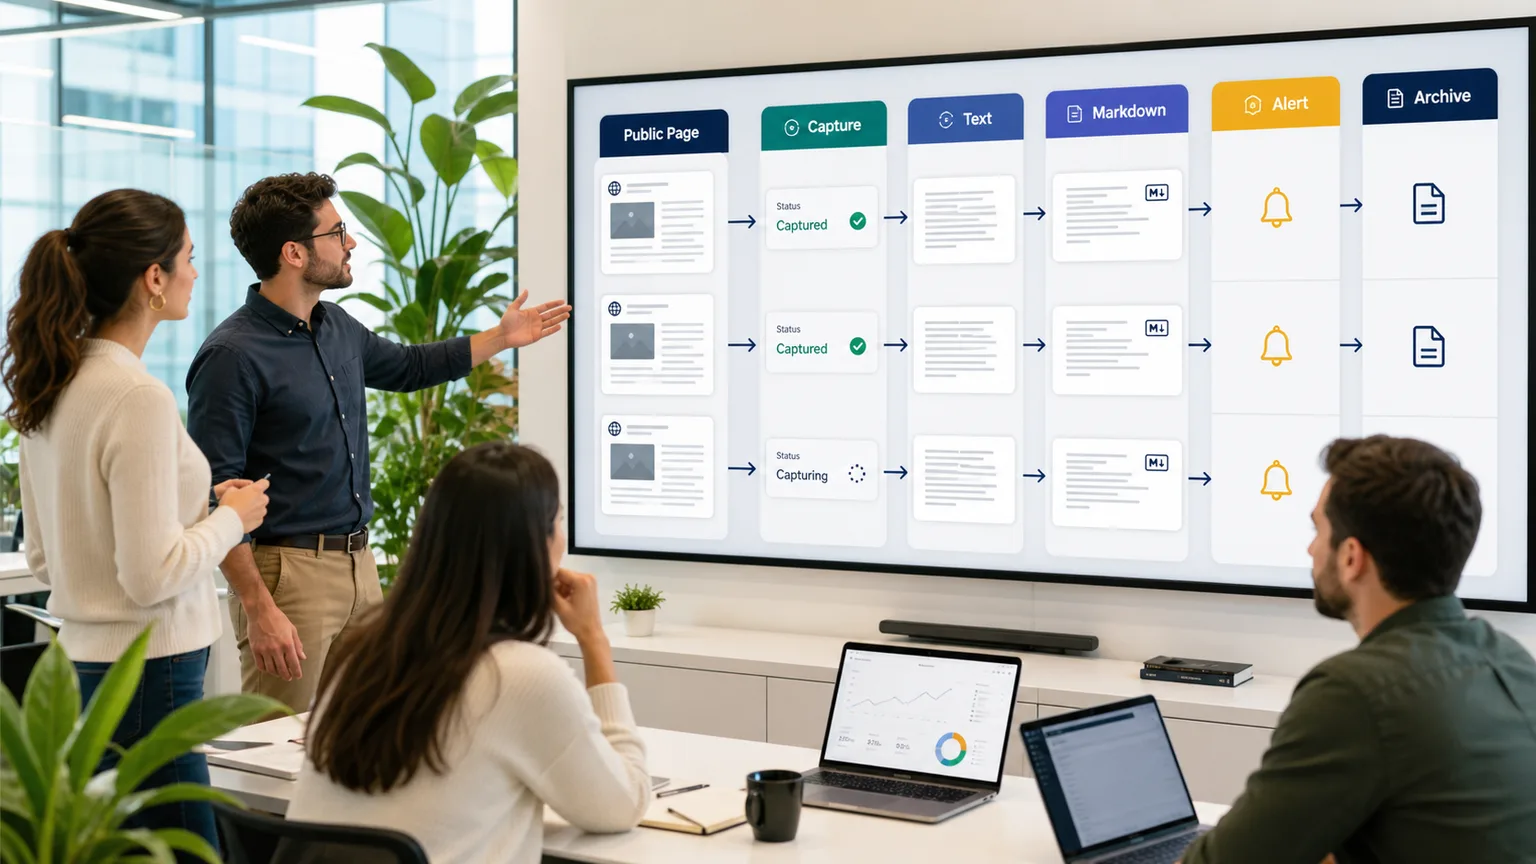
Team monitoring public news pages with capture status, text, Markdown, alerts, and archive evidence

What is a news monitoring scraping API?

A news monitoring scraping API is a hosted request layer that fetches public news and publisher pages so your own system can classify, compare, summarize, alert, or archive the result. Instead of maintaining browser workers, proxy routing, retries, converters, and capture logic in every monitoring project, your application sends a target URL and receives a usable response.

The important point is control. A monitoring workflow may need raw HTML for link discovery, rendered HTML when JavaScript builds the article body, clean text for fast matching, Markdown for analyst review or AI ingestion, JSON metadata for logging, or screenshots and PDFs for visual evidence. ScraperFly keeps those choices inside one API path so teams can test the source before turning a watchlist into a recurring production job.

Practical takeaway: treat news monitoring as source capture first, then let your own product decide which mentions matter.

Which public news sources can teams monitor?

News monitoring rarely depends on one page type. A market intelligence team may watch category pages, press releases, corporate blogs, local publisher pages, author pages, search result pages, and individual article URLs. Each source behaves differently, so the scrape should prove the target shape before the job runs at volume.

Source typeWhat to captureDecision to make
Article pagesHeadline, body text, publish date, canonical URL, author, image references, and final status.Use text or Markdown when the article body is present; use rendered HTML when the useful content appears after browser execution.
Publisher category pagesFresh article links, timestamps, summaries, pagination, and repeated layout patterns.Keep the request light when the link list is in source HTML; add waits only when the list loads late.
Press rooms and company blogsNew announcements, update pages, media posts, and archived releases.Store stable source evidence before downstream classification or stakeholder alerts.
Search and mention pagesResult titles, snippets, URLs, locations, and visible filtering state.Inspect redirects, region behavior, and response size before scaling recurring checks.
Visual evidence pagesRendered page state, screenshots, PDF captures, and review-ready records.Generate visual output only when a human reviewer, compliance process, or archive needs proof of appearance.

How should a monitoring workflow choose the response format?

The right output depends on the consumer. A deduplication job may only need clean text and metadata. An analyst review queue may prefer Markdown because headings and links stay readable. A legal, compliance, or communications archive may need a screenshot or PDF alongside machine-readable content. A crawler that discovers new article URLs may need HTML because DOM structure and links matter.

Choosing one format for every source creates unnecessary work. HTML everywhere means every downstream system needs parsers and cleanup. Screenshots everywhere make comparison harder and request weight higher. Plain text everywhere can remove the structure needed to explain why a mention was matched. ScraperFly lets teams test the source and choose the output that fits the monitoring decision.

Monitoring needBest starting outputWhy it works
Fast keyword or entity matchingTextCompact content is easy to compare, index, and route through simple rules.
AI summaries and analyst reviewMarkdownReadable structure preserves headings and links without forcing reviewers through raw markup.
Link discovery and source parsingHTML or rendered HTMLDOM structure helps parsers find canonical links, pagination, article cards, and metadata.
Operational debuggingJSON metadataStatus, final URL, content type, and response size help explain changes before alerts fire.
Visual proof or archiveScreenshot or PDFHuman reviewers can see what the public page looked like at capture time.

Test formats in the API Builder before committing to a monitoring pipeline, and compare the full output set on the web scraping API response formats page.

When does JavaScript rendering matter for news monitoring?

Many public news and publisher pages still return useful source HTML. Those pages should stay on a simple capture path because it is easier to inspect, faster to compare, and usually lighter. Rendering is valuable when the source response is a thin shell, article cards load after client-side execution, consent state changes the visible page, or the monitoring team needs a screenshot of the rendered view.

The best workflow is evidence-based. Fetch the page first, compare source HTML with rendered output, check response size and final URL, and then decide whether the target needs browser execution. ScraperFly supports that escalation path without forcing every monitored source into the same heavy profile. For pages that genuinely need a browser, review the JavaScript rendering API workflow.

How do teams keep recurring monitoring reliable?

Recurring news capture should not treat every missing article as a breaking event. Pages move, redirects change, publishers update layouts, some regions see different content, and upstream responses can be temporary. A stable monitoring system records enough source evidence to separate a real content change from a delivery issue.

Use status, final URL, response size, content type, and capture format as operating signals. Keep sessions only when continuity changes the result. Use headers when language, content negotiation, or accepted context matters. Add country routing when public content genuinely differs by region. Use backoff for temporary failures instead of increasing pressure blindly.

Practical takeaway: a reliable news monitor captures source evidence, avoids noisy retries, and escalates request controls only when the response proves they help.

How does ScraperFly help control monitoring cost?

News monitoring can become expensive when every watched page is treated as a browser job with visual output and premium routing. Most sources do not need that by default. ScraperFly fits a more practical pattern: start with source capture, keep straightforward pages lightweight, and reserve heavier controls for targets that prove they need them.

This matters for teams that test new watchlists, expand coverage across publishers, or run uneven projects for PR, risk, research, investing, or competitive intelligence. Use free credits to validate source behavior, pay as you go for project-based monitoring, and move predictable recurring work to monthly credits only when the volume is clear. The pricing page and web scraping API credit cost calculator help map request weight to the actual capture profile.


Publisher behavior

Map news source behavior before turning monitoring into a recurring job

Public news pages can differ by publisher, region, JavaScript behavior, redirects, pagination, and archive structure. A practical monitoring setup checks those signals first so the request profile matches the source instead of forcing every URL into the same expensive path.

Raw HTML response mapped to visible page data
01

Raw HTML availability

Check whether the fields you need are already present in the first HTML response.

Best first test for simple pages, articles, docs, listings, and product details.

Before and after JavaScript rendering comparison
02

JavaScript dependency

Compare raw HTML with the rendered DOM or screenshot before turning on browser rendering.

Use rendering when raw HTML is only a shell and scripts create the useful content.

Cookies, consent, session and access context for scraping
03

State & access context

Identify whether cookies, consent, login boundaries, pagination, or the same visitor state affect the response.

Use sessions and headers when continuity changes the data you receive.

Regional content variations across countries and routes
04

Geo/content variation

Test whether country, language, currency, inventory, SERP, ads, or route reputation changes the result.

Use geo or premium routing only when the target proves the response varies by route.

News source questions worth answering early

Where is the target field?

Find whether the field exists in raw HTML, rendered DOM, an API call, structured data, a file, or a later interaction state.

What changes the response?

Sample a few URLs and compare status, final URL, content length, redirects, empty states, and visible result differences.

What context is required?

Mark any dependency on consent, locale, cookies, headers, authentication boundary, pagination, filters, or previous requests.

What does failure look like?

Define the signals for blocked, partial, stale, redirected, empty, timed-out, or region-mismatched responses before scaling.

Signals to check before scheduling capture

Fetch mode

Raw HTML availability decides whether the first request can stay simple or needs rendering, waits, screenshots, or extraction.

Request context

State requirements decide whether to add headers, cookies, sessions, consent handling, or a stable visitor profile.

Routing choice

Geo and reputation findings decide whether standard routing is enough or a country/premium route is justified.

Validation rules

Known failure states become checks for retries, escalation, QA review, and deciding when a lighter profile is still complete.

News request builder

Build capture requests that fit alerts, review, and archives

Use the API Builder to test a public article or publisher page, compare output formats, and copy a request shape that your monitoring workflow can repeat with confidence.

Source capture
Source capture

HTML and rendered HTML

Fetch source markup for simple pages, or render when the article body, list, or visible state depends on JavaScript.

Readable content
Readable content

Text, Markdown, and metadata

Return compact text for matching, Markdown for review and AI workflows, and JSON metadata for diagnostics and evidence.

Visual proof
Visual proof

Screenshots and PDFs

Capture visual records when a reviewer, archive, or compliance workflow needs proof of how the public page appeared.

Request controls for public news capture

url

The public news, article, publisher, or mention page to capture.

format

Choose html, text, markdown, json, screenshot, or pdf based on the downstream consumer.

render

Run browser execution when source HTML does not contain the useful content.

country

Route through a country-specific proxy when public content changes by region.

keep_headers

Forward allowed language, content, or referrer headers when the source expects them.

download

Return visual files as downloadable artifacts when review or archive workflows need them.

cURL example

Generate Markdown with the same request shape you can move into production

curl "https://scraperfly.com/api/v1?url=https%3A%2F%2Fexample.com&format=markdown" \
  -H "apikey: YOUR_API_KEY"

Monitoring cost control

Keep recurring news capture affordable by matching request weight to source evidence

News monitoring often starts with uncertain sources and uneven volume. ScraperFly supports that reality: validate targets with free credits, keep simple captures light, buy pay-as-you-go credits for project-based watchlists, and move to monthly credits when recurring demand is predictable.

A lightweight HTML request returning a simple response
01

Basic fetch

Use a basic fetch when public HTML already contains the fields you need.

Lightest request profile; keep it when the response is complete.

JavaScript rendering producing a complete DOM
02

Rendering

Use rendering when raw HTML is a shell and JavaScript completes the page.

Heavier profile; use it only when browser output changes the result.

Several requests preserving cookies and visitor state
03

Stateful session

Use sessions when cookies, consent, locale, or pagination change the response.

Heavier state profile; preserve it only when continuity matters.

Request routing through geo and higher quality routes
04

Premium routing & geo

Use premium routing or geo only when origin, country, reputation, or regional content changes the result.

Heaviest routing profile; apply it only to targets that prove they need it.

What makes a request heavier

More infrastructure work

Browser rendering, routing choices, and longer waits mean the platform has to do more than return a simple response.

More target uncertainty

Redirects, empty states, rate limits, and challenge pages often require stronger delivery options or retries.

More state to preserve

Cookies, sessions, consent, and multi-page flows add moving parts that a plain stateless fetch does not have.

More evidence to return

Screenshots, PDFs, rendered output, and richer response artifacts are useful, but they are heavier than plain HTML.

How to keep request weight predictable

Sample before scale

Test a small URL set first and group targets by the lightest profile that returns complete data.

Do not render by default

Inspect raw HTML before turning on rendering. Many public pages already contain the data you need.

Escalate by evidence

Move up only when the response shows missing content, state dependency, geo variance, or routing problems.

Measure useful results

Optimize around valid records delivered, not raw request volume. A lighter profile is best only when it stays complete.

News monitoring FAQ

Common questions about news monitoring with ScraperFly

Practical answers for teams evaluating public news capture, response formats, rendering, alerts, archives, and recurring monitoring cost.

News FAQ

Public news pages

For teams watching publishers, articles, press rooms, blogs, and mention pages.

Can I monitor any news website?

ScraperFly is for public web pages. Your team remains responsible for permissions, target rules, and lawful use of collected public data.

Can I monitor article lists and category pages?

Yes. Fetch the visible page, inspect links, timestamps, pagination, and response size, then decide whether source HTML or rendered HTML is the right capture profile.

Article evidence

Choose a response format that fits matching, review, AI, or archives.

Should monitoring use text or Markdown?

Use text for compact matching and Markdown when analysts, search, or AI workflows benefit from readable headings, links, and article structure.

When do screenshots or PDFs help?

Use visual files when reviewers need proof of how a public page appeared, not as the default format for every machine-only comparison.

Dynamic publishers

Enable browser execution only when it changes the captured result.

Do news pages always need rendering?

No. Many pages expose useful source HTML. Render when article text, lists, consent state, or visual proof depends on browser-side code.

How do I know a source changed?

Compare status, final URL, response size, content type, source HTML, rendered output, and captured content across samples before changing request controls.

Recurring jobs

Keep monitoring useful without making every watched source heavy.

How do I avoid expensive monitoring jobs?

Start with simple capture, add rendering or visual output only for sources that prove they need it, and use monthly credits once recurring volume is clear.

Does ScraperFly create alerts for me?

ScraperFly captures the public page response. Alert rules, deduplication, classification, and routing belong in your monitoring application.





