






RAG source intake
Give retrieval systems cleaner public web context
RAG work starts before embeddings, ranking, or answer generation. The first decision is whether the source page can produce useful content at all: clean text, Markdown with headings and links, HTML for custom parsing, or JSON metadata that helps the pipeline understand the response.
ScraperFly focuses on that first mile. Fetch the public page, render JavaScript when the content is browser-built, choose the lightest response format that downstream systems can trust, and keep bad pages out of the knowledge base before they become bad answers.
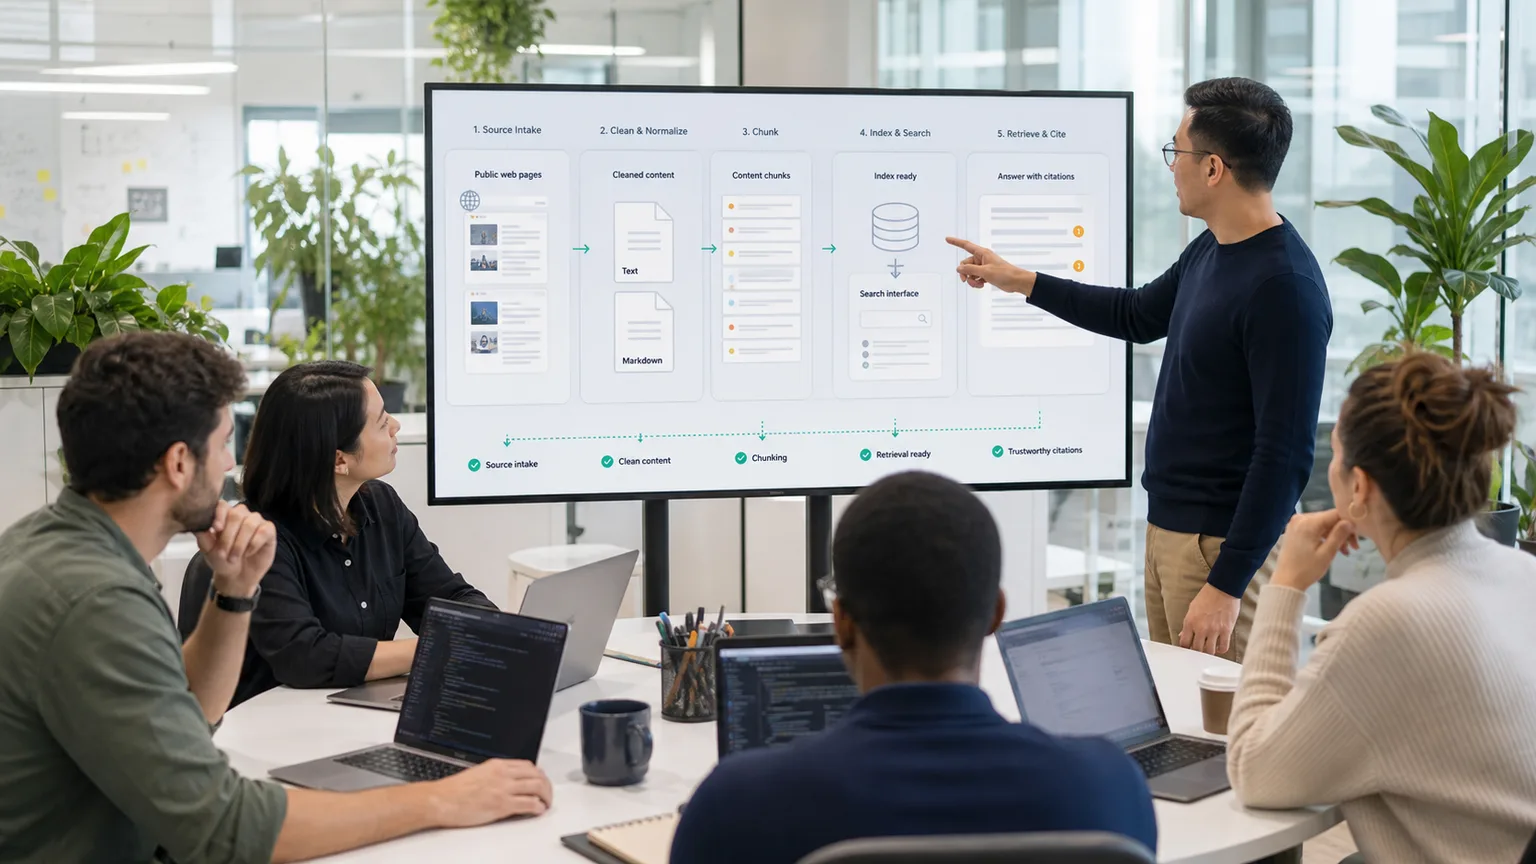
What does a web scraping API contribute to RAG?
A web scraping API gives a RAG system the source material it needs before the AI layer begins. It retrieves public pages, handles request delivery, returns a response format, and provides enough context to decide whether the page is usable for chunking, indexing, retrieval, and citation.
That role is narrower and more practical than a full RAG platform. ScraperFly does not need to own embeddings, vector storage, retrieval ranking, or answer generation to be valuable. It helps teams feed those systems with cleaner source content and better request evidence.
Which response format is best for RAG intake?
The best format depends on what the pipeline needs to preserve. Clean text is compact and easy to chunk. Markdown keeps useful headings, links, lists, and reading order. HTML is better when the system still needs selectors, tables, DOM relationships, or custom extraction. JSON metadata helps inspect final URL, status, content type, headings, links, text, and Markdown before ingestion rules run.
Choosing the format early prevents a common RAG problem: stuffing the index with navigation, footer text, repeated boilerplate, cookie banners, duplicate cards, and empty templates. The goal is not to scrape the biggest response. The goal is to capture the source shape that your retrieval workflow can actually use.
| Format | Best RAG use | What to watch |
|---|---|---|
| Text | Simple chunking, search indexing, compact context | May remove useful structure and links |
| Markdown | LLM-ready source review, RAG chunks, documentation-like pages | Still needs deduplication and quality checks |
| HTML | Custom parsing, selectors, tables, metadata, link extraction | Can include layout noise and boilerplate |
| JSON metadata | Diagnostics, source inspection, ingestion decisions | Does not replace target-specific extraction logic |
| Screenshot or PDF | QA proof and visual review | Usually not ideal as primary retrieval input |
How should teams validate source quality before indexing?
RAG pipelines fail quietly when bad source pages make it into the index. A successful HTTP response can still be useless if it is an empty shell, a redirect, a consent wall, a blocked page, duplicated navigation, or a page where the important content appears only after JavaScript runs.
Before scaling ingestion, test representative URLs. Compare raw HTML with rendered output. Review text and Markdown samples. Check final URL, status, content type, response size, headings, links, repeated sections, dates, and language. Keep examples of accepted and rejected pages so the ingestion rules are based on evidence rather than assumptions.
| Quality check | Why it matters | Useful ScraperFly output |
|---|---|---|
| Content completeness | Prevents missing answers and weak citations | HTML, rendered HTML, Markdown, text |
| Boilerplate noise | Reduces irrelevant chunks and repeated context | Text, Markdown, JSON metadata |
| Source identity | Helps citation and freshness decisions | Final URL, status, metadata, links |
| JavaScript dependency | Shows whether browser rendering is necessary | Raw HTML compared with rendered output |
When does JavaScript rendering matter for RAG?
Rendering matters when the useful public content is not present in the initial HTML response. Many modern pages send a shell first, then load article bodies, product details, comments, documentation panels, or search results after browser-side code runs. Indexing the source HTML from those pages can create empty or misleading context.
The right approach is to prove the gap before enabling browser execution broadly. Start with a simple request, inspect the source response, then enable JavaScript rendering only for source classes that need it. That keeps static pages inexpensive while giving dynamic pages a clean path into the RAG pipeline.
How does ScraperFly fit into a production RAG workflow?
ScraperFly fits at the source-intake layer. Teams can use it to test target URLs, choose response formats, handle rendering when needed, preserve request context, and collect source evidence before content moves into chunking, embeddings, retrieval, ranking, and answer generation.
Use the API Builder to compare formats before writing ingestion code. Review web scraping API response formats to decide between HTML, text, Markdown, JSON, screenshots, and PDFs. For model-ready content, compare HTML to Markdown and HTML to text workflows, then use pricing and the credit cost calculator before scaling recurring ingestion.










