






MARKDOWN OUTPUT
Turn public pages into Markdown your pipeline can actually read
ScraperFly gives teams a practical path from a public URL to clean Markdown. Instead of sending raw page markup into an AI prompt, documentation tool, content review queue, or search index, your application can request a response that keeps useful headings, paragraphs, lists, and links in a readable shape.
The important part is control. Start with a lightweight request, inspect what the target returns, then enable browser rendering, waits, sessions, headers, country targeting, or stronger routing only when those controls improve the Markdown your workflow receives.
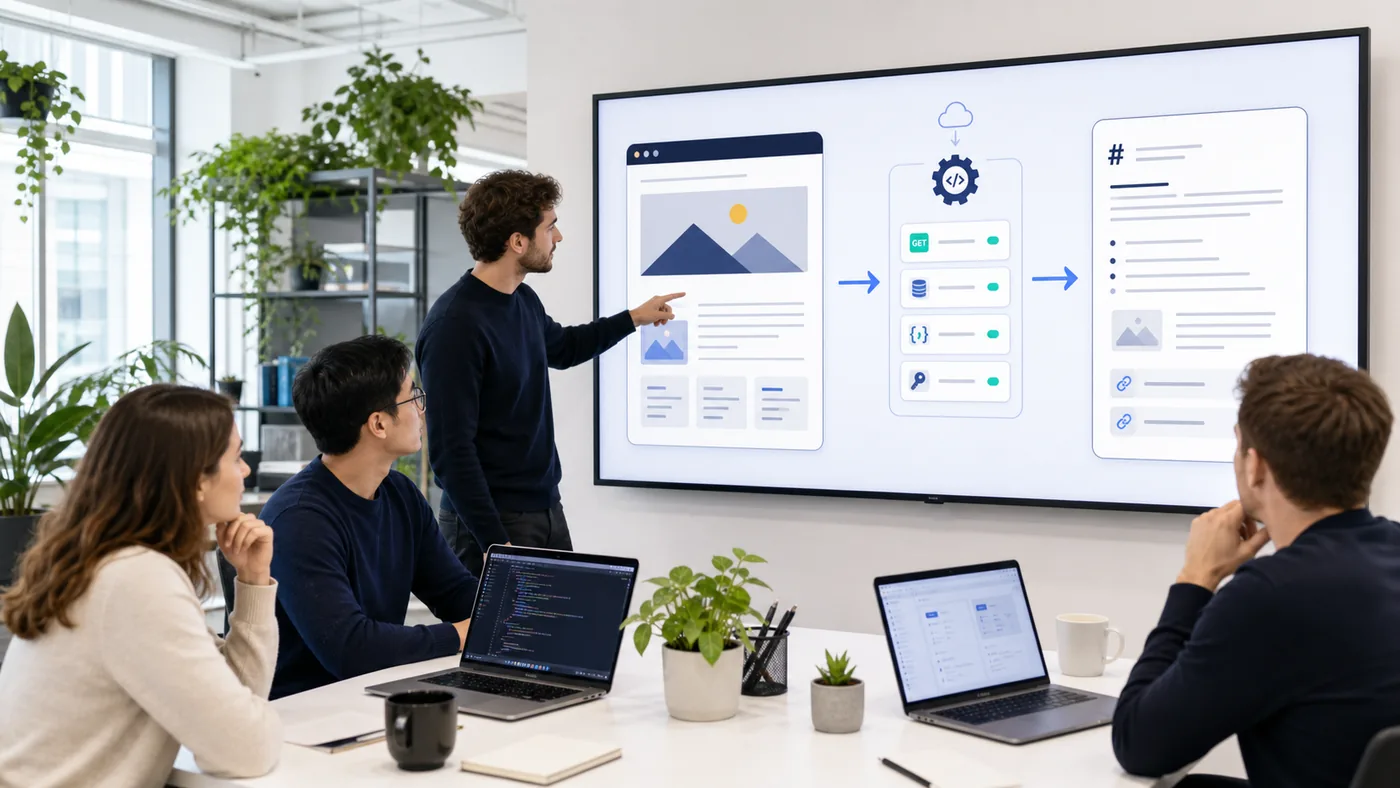
What is a web page to Markdown API?
A web page to Markdown API fetches a public URL and returns the captured page content as Markdown. The response is meant for systems that need readable content rather than browser infrastructure: RAG ingestion, AI agents, internal search, editorial review, documentation imports, monitoring notes, and lightweight content analysis.
Markdown is useful because it sits between raw HTML and plain text. It can preserve headings, paragraph flow, lists, and links without forcing every downstream consumer to understand DOM nesting, repeated navigation, attributes, scripts, styles, or template noise.
This is not the same as promising perfect article extraction or custom schema extraction. A Markdown response should be treated as a clean content format. If your product needs exact product fields, bylines, dates, prices, ratings, or selector-level structure, validate those fields separately or keep HTML and metadata available for the parser.
Practical takeaway: use page-to-Markdown when the consumer needs readable page content, not exact DOM evidence.
When should teams use Markdown instead of HTML or text?
Markdown is strongest when the page content will be read, chunked, summarized, reviewed, indexed, or passed into a language-model workflow. It gives the receiving system more structure than plain text, but less noise than raw HTML.
HTML is still the better fit when selectors, attributes, nested tables, exact links, or DOM relationships matter. Plain text is better when the workflow only needs compact readable copy. JSON metadata helps with request diagnostics. Screenshots and PDFs help when the visual state is the proof.
| Workflow | Why Markdown helps | When another format is better |
|---|---|---|
| RAG and AI intake | Keeps headings, lists, links, and readable sections for cleaner chunking. | Use HTML when the extraction depends on selectors or hidden attributes. |
| Editorial review | Makes public page content easier for humans to scan and annotate. | Use screenshot or PDF when layout and visual proof matter. |
| Documentation import | Moves page sections into a format that docs tools can handle naturally. | Use text when only plain copy is needed. |
| Search indexing | Preserves useful structure without adding HTML boilerplate to the index. | Use JSON metadata to track final URL, status, content type, and request context. |
| Monitoring notes | Captures readable page changes without storing a full rendered artifact every time. | Use screenshots for visual regressions, broken layouts, or approval evidence. |
Practical takeaway: choose Markdown when structure helps the reader or model, and keep HTML or visual formats when proof needs to be exact.
How does rendering change Markdown output?
A Markdown converter can only work with content the request captures. Many public pages send useful content in the first HTML response. Those pages should stay simple: fetch the URL, request Markdown, and avoid browser execution unless the output proves something is missing.
Other pages ship a thin HTML shell and build the useful content after JavaScript runs. In that case, JavaScript rendering can capture the rendered page state before the response is converted to Markdown. That makes the Markdown more complete, but it also makes the request heavier, so rendering should be a decision based on evidence.
Useful evidence includes the source HTML, rendered HTML, final URL, response size, status code, screenshot state, and a few representative target samples. If the Markdown is already complete from source capture, keep the profile light. If important sections appear only after browser execution, render that URL pattern intentionally.
Practical takeaway: render for Markdown completeness, not because rendering is available.
How is page-to-Markdown different from an HTML-to-Markdown parser?
The phrase HTML to Markdown parser API usually starts with captured HTML and focuses on conversion. A web page to Markdown API starts earlier in the workflow: it accepts a public URL, fetches the page, handles request controls, and then returns Markdown as the chosen response format.
That difference matters in production. Page capture may involve redirects, headers, cookies, sessions, country targeting, wait timing, proxy routing, JavaScript rendering, content type checks, and response size limits. A converter alone does not solve those delivery questions. ScraperFly lets the same request model move from simple source capture to a more complete page state when the target proves it is needed.
If your team already has trusted HTML and only needs conversion, a parser-focused workflow may be enough. If the problem starts with public URL delivery and continues into readable content, page-to-Markdown is the more complete mental model.
What should teams check before scaling Markdown capture?
Good Markdown output is not only a formatting question. It depends on the target page, the response state, the content your downstream system expects, and the amount of noise the page adds around the useful sections.
- Final URL and status. Redirects, soft errors, consent pages, or challenge pages can produce readable Markdown that is still the wrong content.
- Source versus rendered content. Compare raw capture with rendered capture before making browser execution the default.
- Heading structure. Check whether headings reflect the useful content or mainly repeat navigation and template sections.
- Links and lists. Make sure important links, list items, and section boundaries survive conversion in a shape your app can use.
- Repeated boilerplate. Navigation, footers, cookie banners, recommendations, and ads can still appear in Markdown and should be handled before indexing.
- Tables and complex layouts. Markdown can simplify complex structures. Keep HTML available when table shape or exact DOM relationships matter.
These checks keep the output honest. They also prevent a team from treating Markdown as a magic cleanup layer when the real issue is delivery, rendering, target selection, or a downstream extraction requirement.
How should teams choose between Markdown and other ScraperFly formats?
The safest approach is to test the same target through several response formats in the API Builder. Use Markdown for readable structure, text for compact copy, HTML for parser control, JSON metadata for diagnostics, screenshots for visual QA, and PDFs for portable records.
| Format | Best fit | Decision rule |
|---|---|---|
| Markdown | AI, RAG, docs, review, and readable content workflows. | Use it when headings, links, and section flow improve the consumer experience. |
| HTML | Selectors, DOM parsing, attributes, tables, and exact source relationships. | Use it when the parser needs structural precision. |
| Text | Lightweight search, summaries, and simple language processing. | Use it when structure is unnecessary. |
| JSON metadata | Logging, status checks, final URL, content type, and request diagnostics. | Use it beside content formats to make the request easier to debug. |
| Screenshot or PDF | Visual proof, QA, archive, compliance, or human review. | Use visual files when appearance matters more than machine-readable text. |
For a broader format comparison, review the web scraping API response formats guide. For AI-specific workflows, connect Markdown decisions with the Scraping API for RAG page and validate whether your content pipeline needs Markdown, text, HTML, metadata, or a mix.
Practical takeaway: do not standardize on one format too early; test the target and choose the response your product can use immediately.
How can ScraperFly keep Markdown workflows predictable?
ScraperFly is useful when Markdown conversion is part of a larger public web data workflow. The API can keep simple pages light, add rendering when JavaScript creates useful content, preserve request context with headers and sessions, route through country-specific or stronger delivery when needed, and return alternative formats when Markdown is not enough.
That flexibility matters for cost as much as quality. A page that converts cleanly from source HTML should not carry the same request profile as a rendered page that needs waits, session continuity, or visual proof. Connect the output decision to request weight, and use pricing only after the target behavior is clear.
If the goal is content extraction rather than Markdown formatting, compare this page with the web content parser API. If the goal is a portable artifact, use the PDF or screenshot pages instead. The best page-to-Markdown workflow is specific enough to be useful and flexible enough to avoid unnecessary infrastructure.



